
A SAS DLPy model uses Batch Normalization (BN) layers between Conv2d layers. How do Batch Normalization layers behave differently during inference (scoring) compared to during training?
Select an answer to reveal the explanation.
Short Explanation
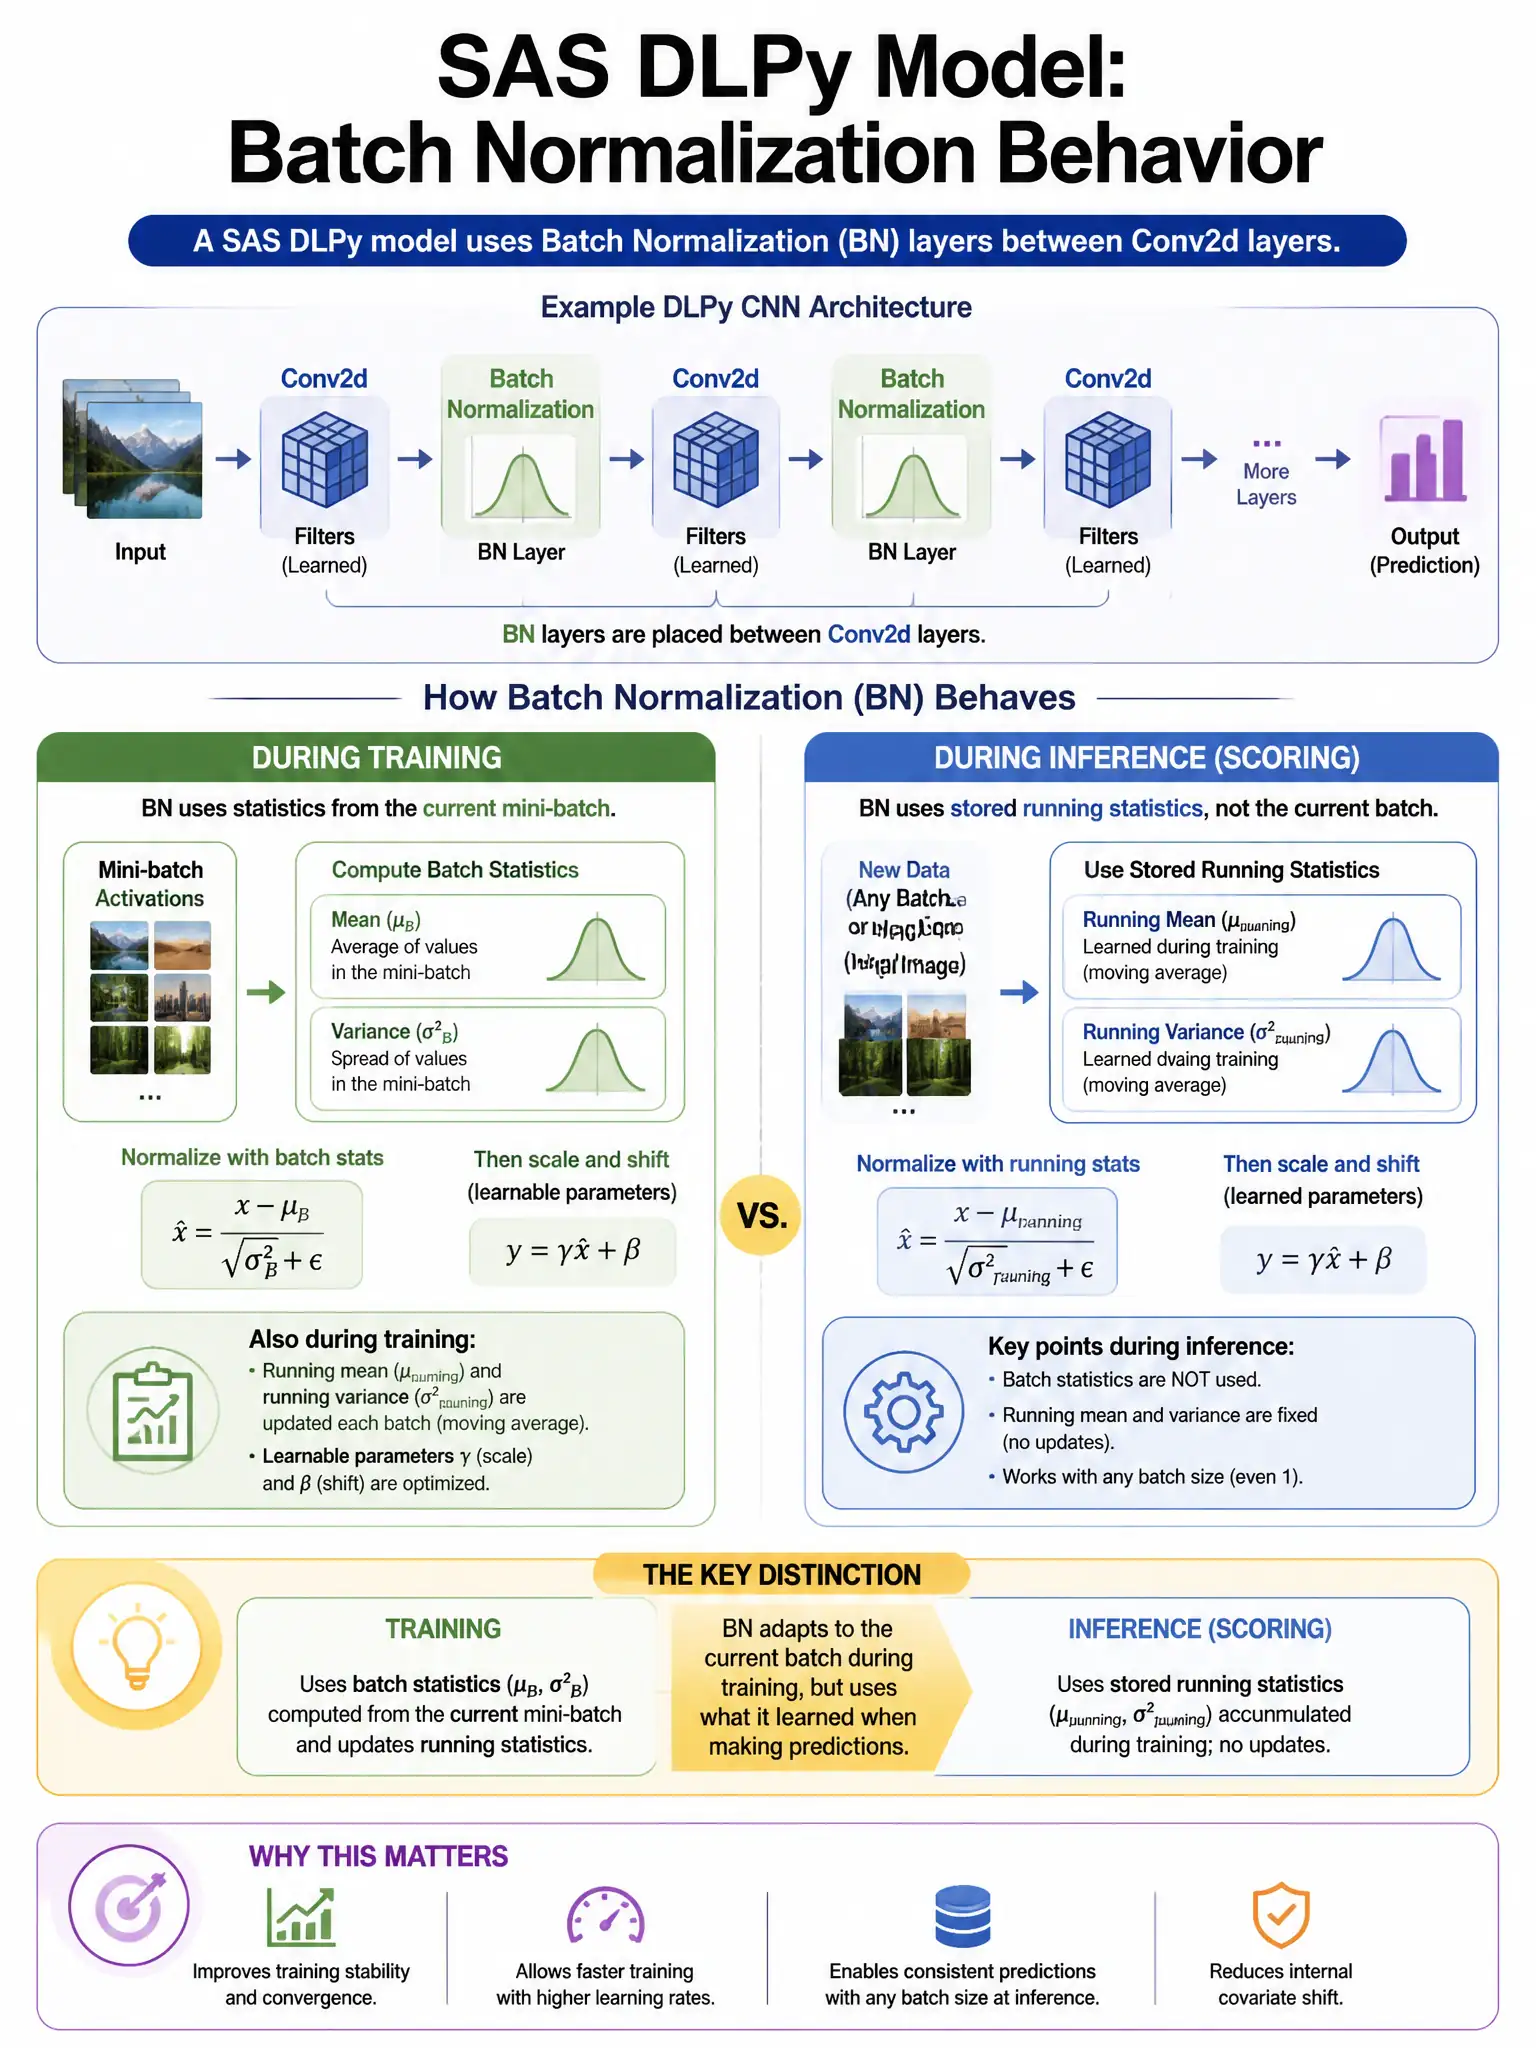
Here's the deal — Batch Normalization has two modes. During training, you normalize activations with the current mini-batch mean and variance. During inference, you use running averages accumulated during training.
Full Explanation
Batch Normalization has two operational modes. During training, it normalizes activations using the current mini-batch mean and variance, which vary per batch and reduce internal covariate shift. During inference, using single-observation or small-batch statistics would be noisy, so it uses exponential moving averages of mean and variance accumulated across training batches; these running statistics are fixed. The option about applying random dropout during inference is wrong because Batch Normalization does not apply dropout. The option about removing Batch Normalization layers during inference is wrong because they remain in the inference graph. The option about using identical global dataset statistics in both modes is wrong because training uses batch statistics, not global statistics.