
PROC ACECLUS is run as a preprocessing step before PROC CLUSTER. What does PROC ACECLUS estimate that improves subsequent clustering?
Select an answer to reveal the explanation.
Short Explanation
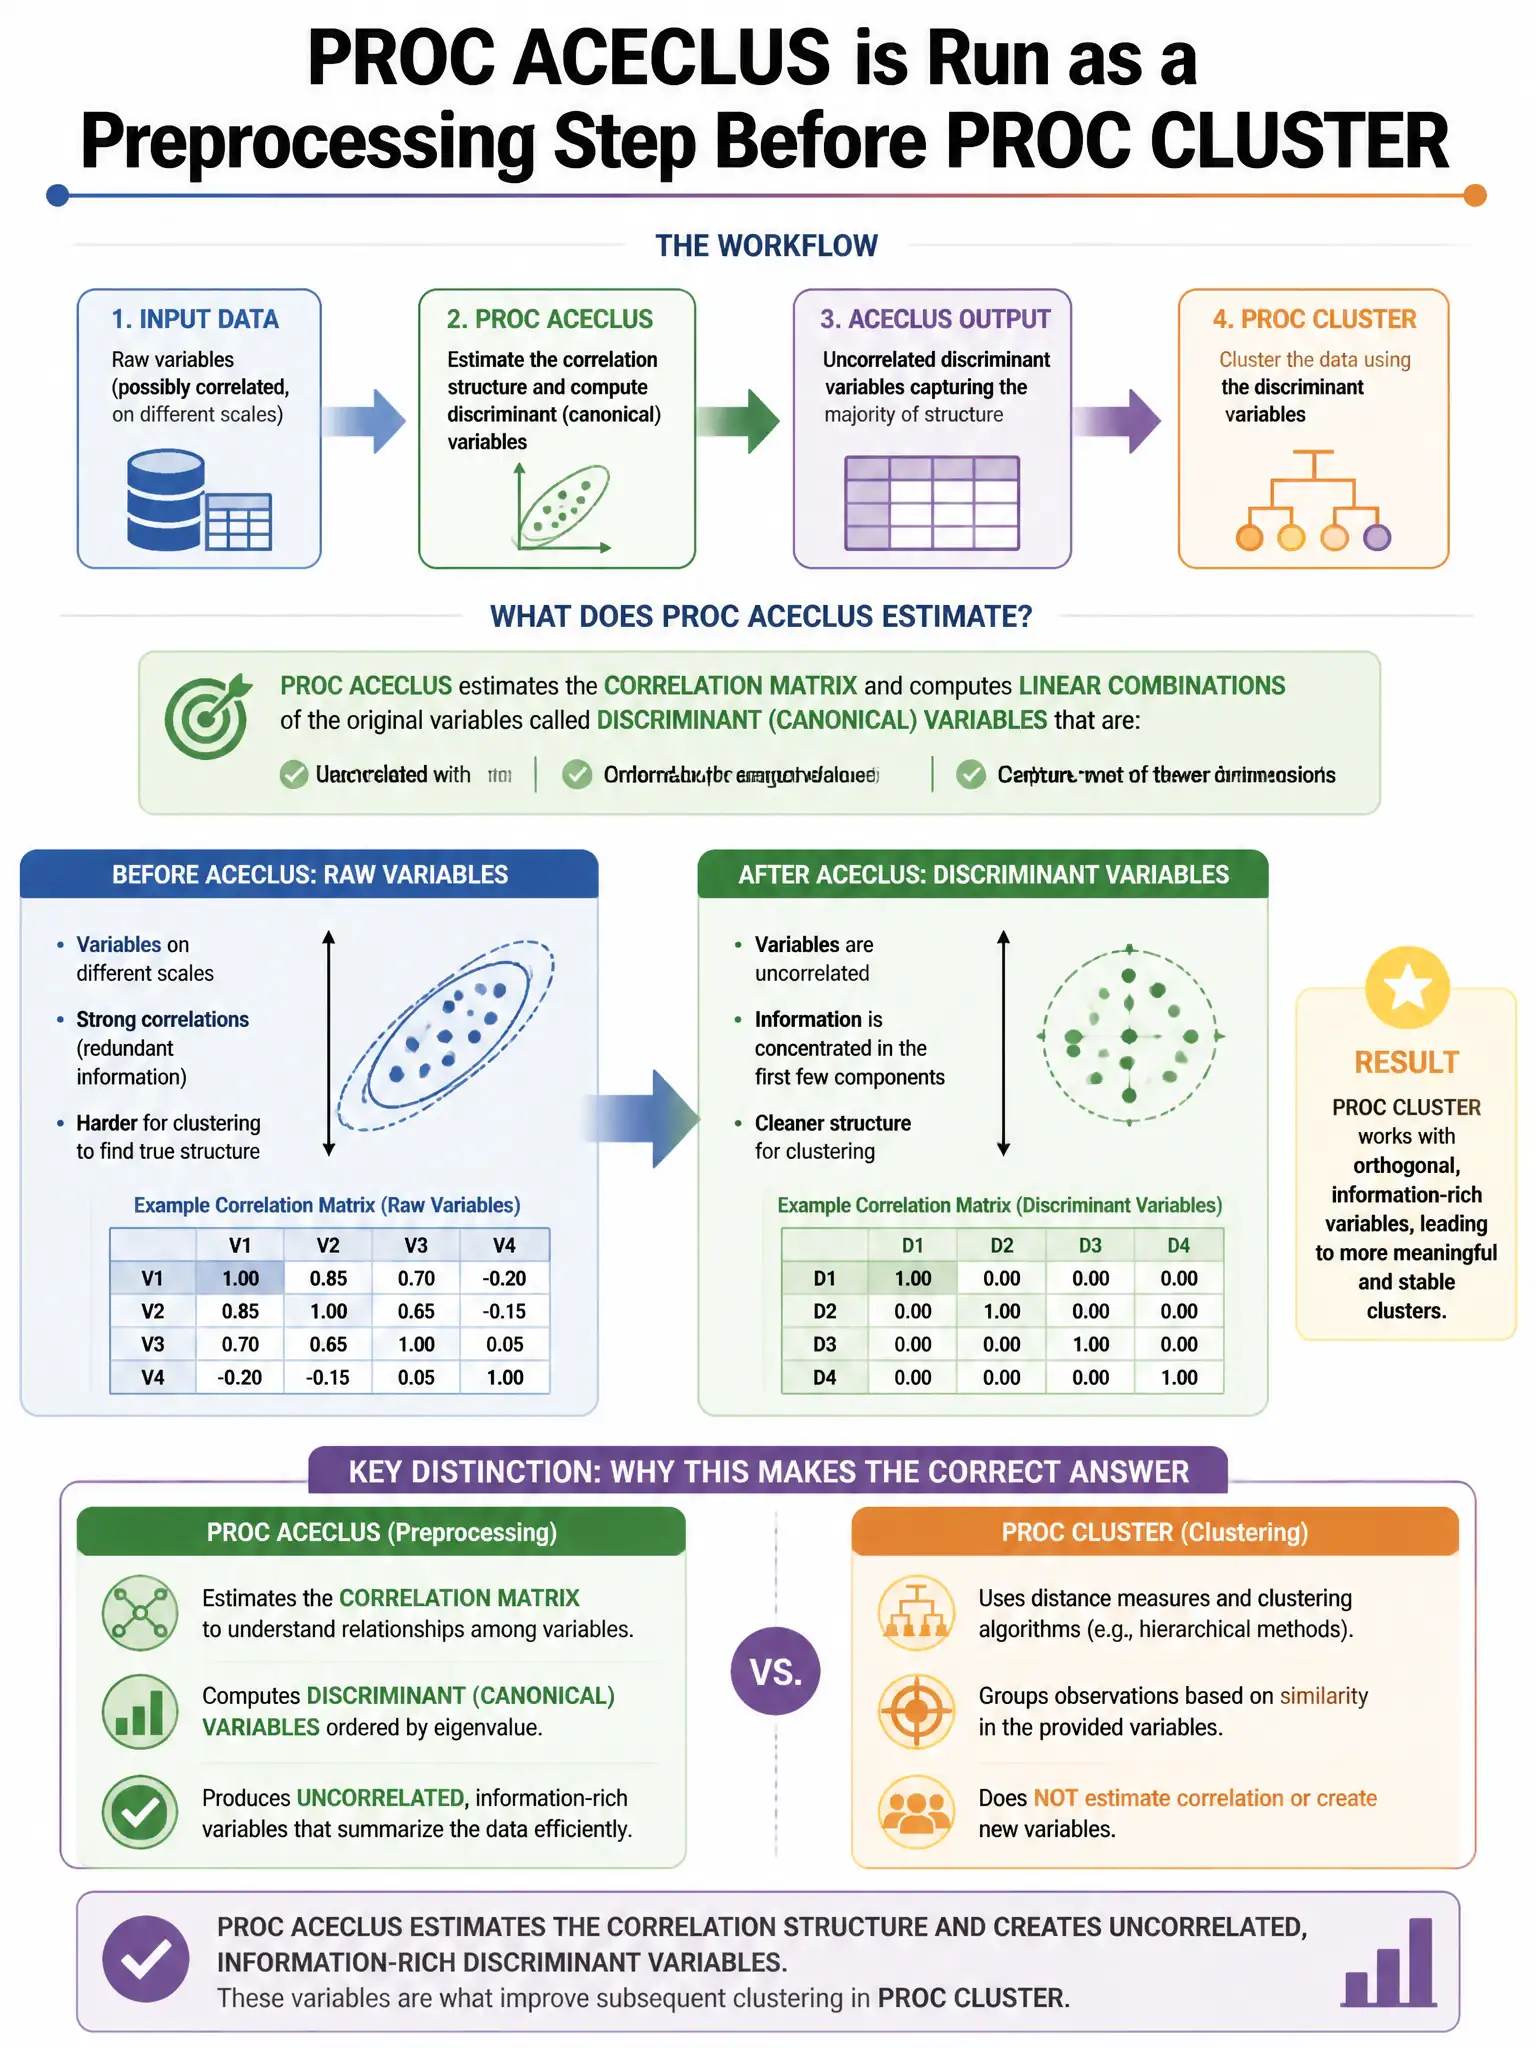
Here's the deal — PROC ACECLUS estimates an approximate within-cluster covariance structure using nearest neighbors, even before you know the cluster assignments. You then use that covariance in PROC CLUSTER to compute Mahalanobis-style distances, which handle correlated variables and scale differences better than plain Euclidean distance.
Full Explanation
The option saying PROC ACECLUS estimates an approximate within-cluster covariance matrix for Mahalanobis-style distance is correct. PROC ACECLUS (Approximate Covariance Estimation for Clustering) estimates a pooled within-cluster covariance structure using a nearest-neighbor approach without knowing cluster assignments. That covariance is then used in PROC CLUSTER to compute a Mahalanobis-type distance, accounting for variable correlations and scale differences, improving cluster quality over Euclidean distance on correlated features. The gap-statistic option is wrong because PROC ACECLUS does not compute gap statistics. The principal-components option is wrong because dimensionality reduction is PROC PRINCOMP's role. The linkage-criterion option is wrong because PROC ACECLUS does not select linkage criteria.