
A SAS administrator wants to use PROC SQL to identify duplicate customer records based on email address. Which approach correctly identifies duplicate email addresses?
Select an answer to reveal the explanation.
Short Explanation
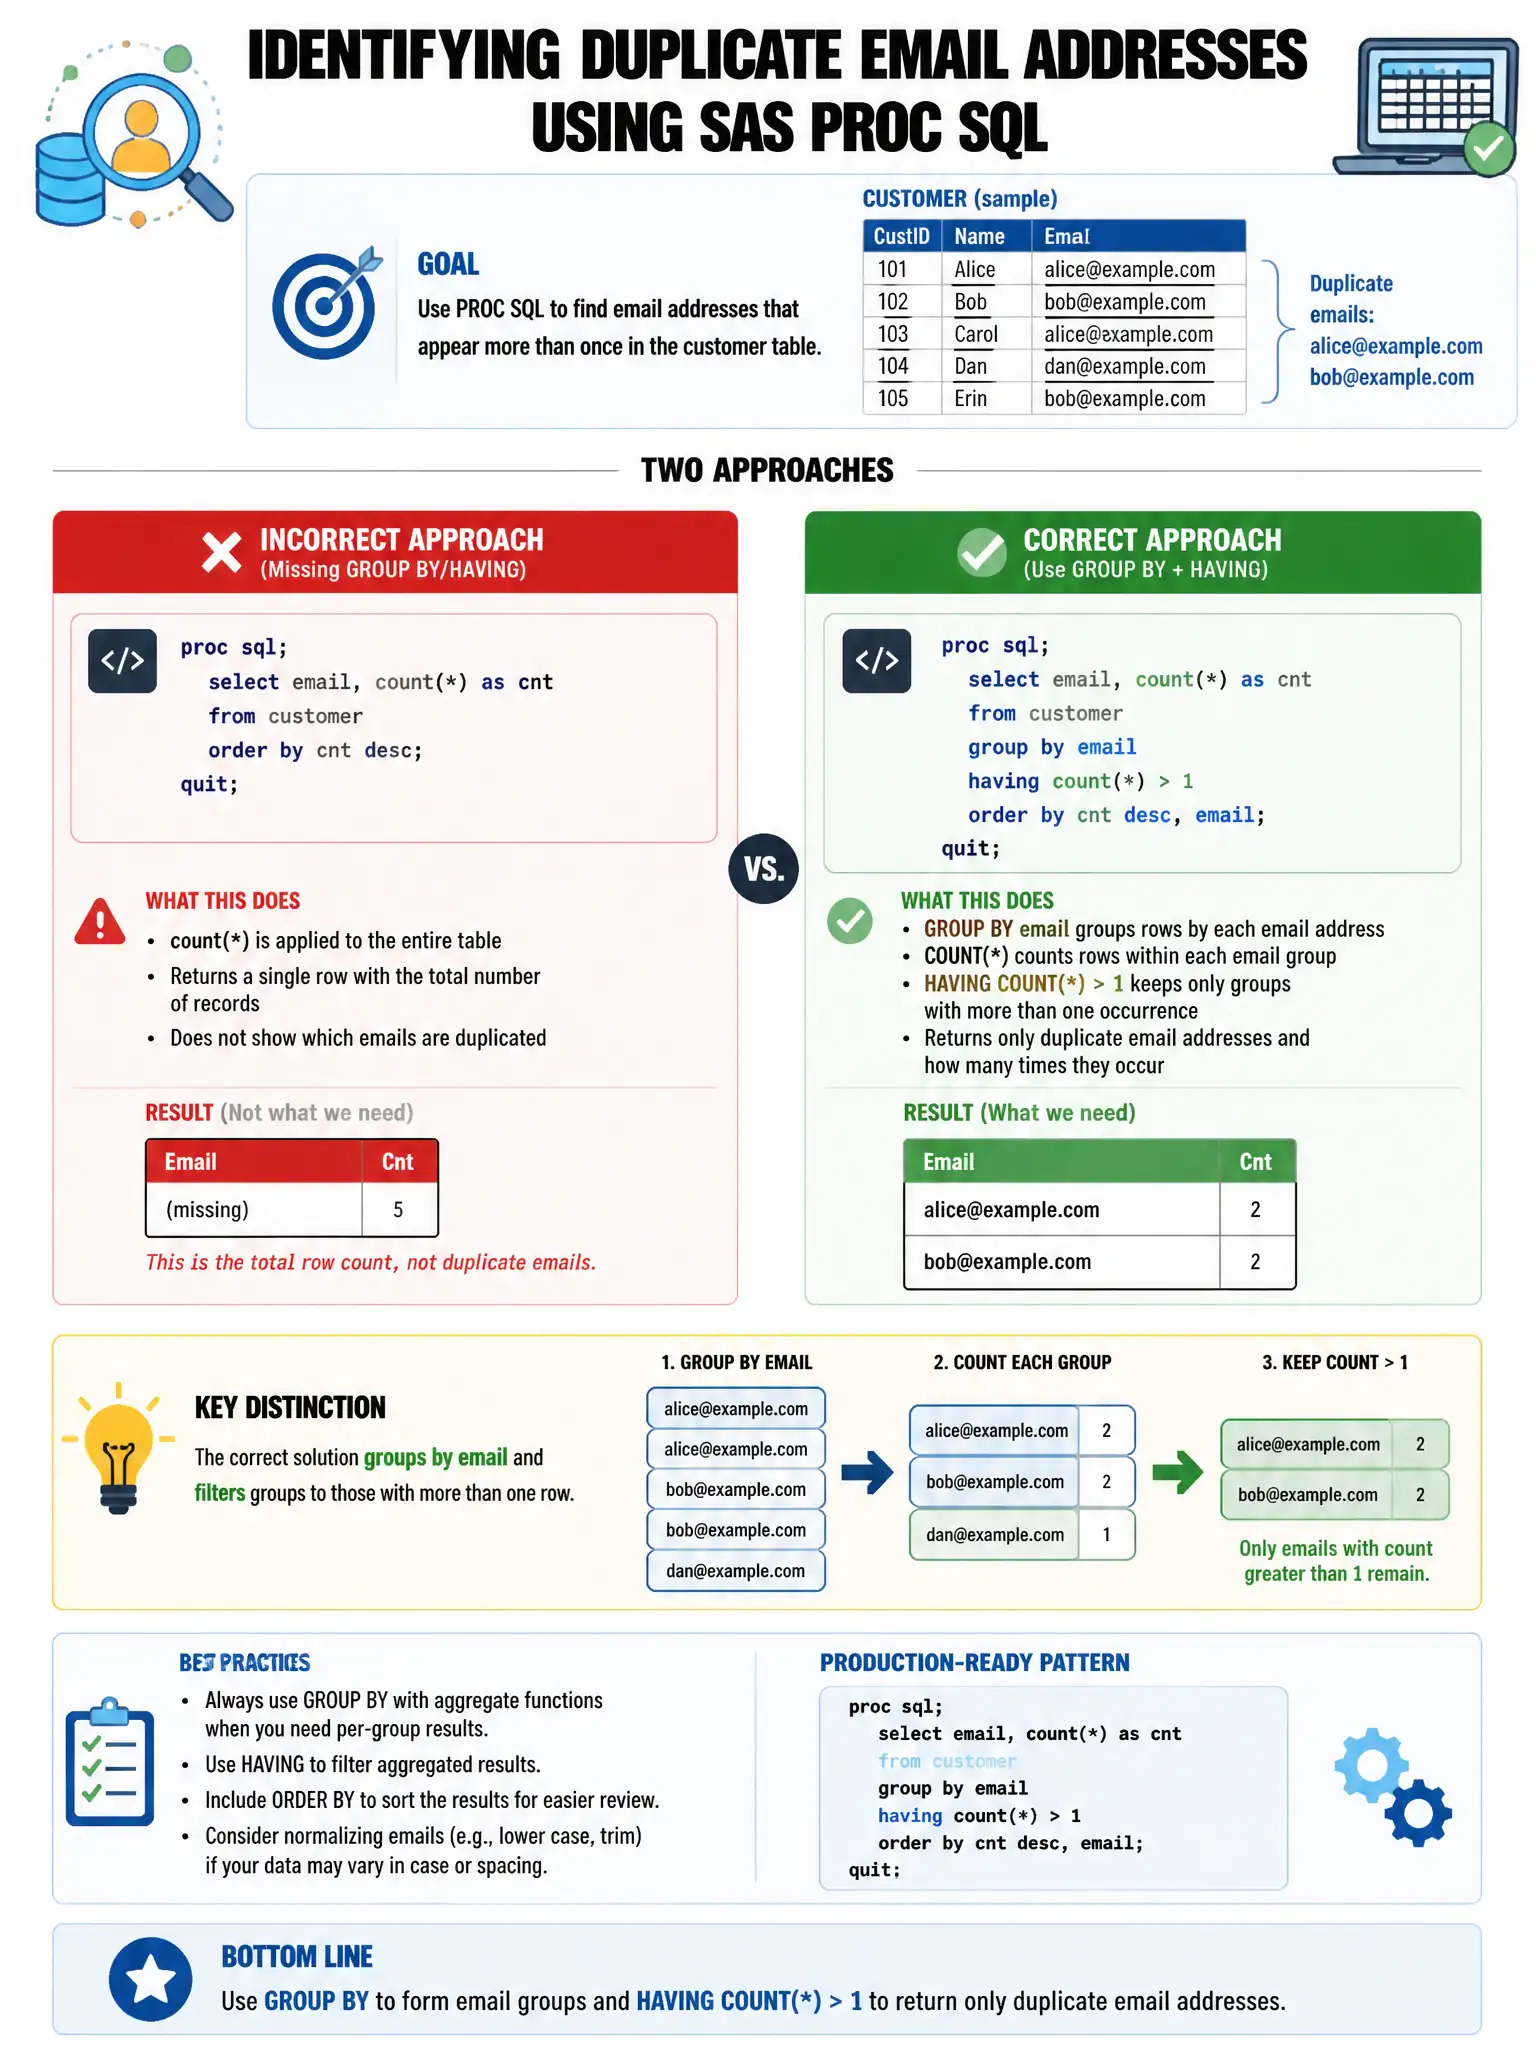
You need to group the rows by email address, then use HAVING COUNT(*) > 1 to keep only the groups that appear more than once. That's how PROC SQL identifies duplicate email addresses.
Full Explanation
The correct query groups by email and uses HAVING COUNT() > 1. GROUP BY email aggregates rows by email address, and HAVING COUNT() > 1 keeps only groups with more than one row, identifying duplicates. The query without GROUP BY that filters HAVING cnt > 1 is wrong because GROUP BY is missing and the alias cnt is not valid in PROC SQL HAVING without GROUP BY. The query using WHERE COUNT(email) > 1 is wrong because WHERE cannot contain aggregate functions. The query using ORDER BY email and HAVING COUNT(*) > 1 is wrong because HAVING without GROUP BY is invalid.