
Within a single ensemble retriever configuration for Ridgeline's clinic policy library, what can be combined to improve overall retrieval quality?
Select an answer to reveal the explanation.
Short Explanation
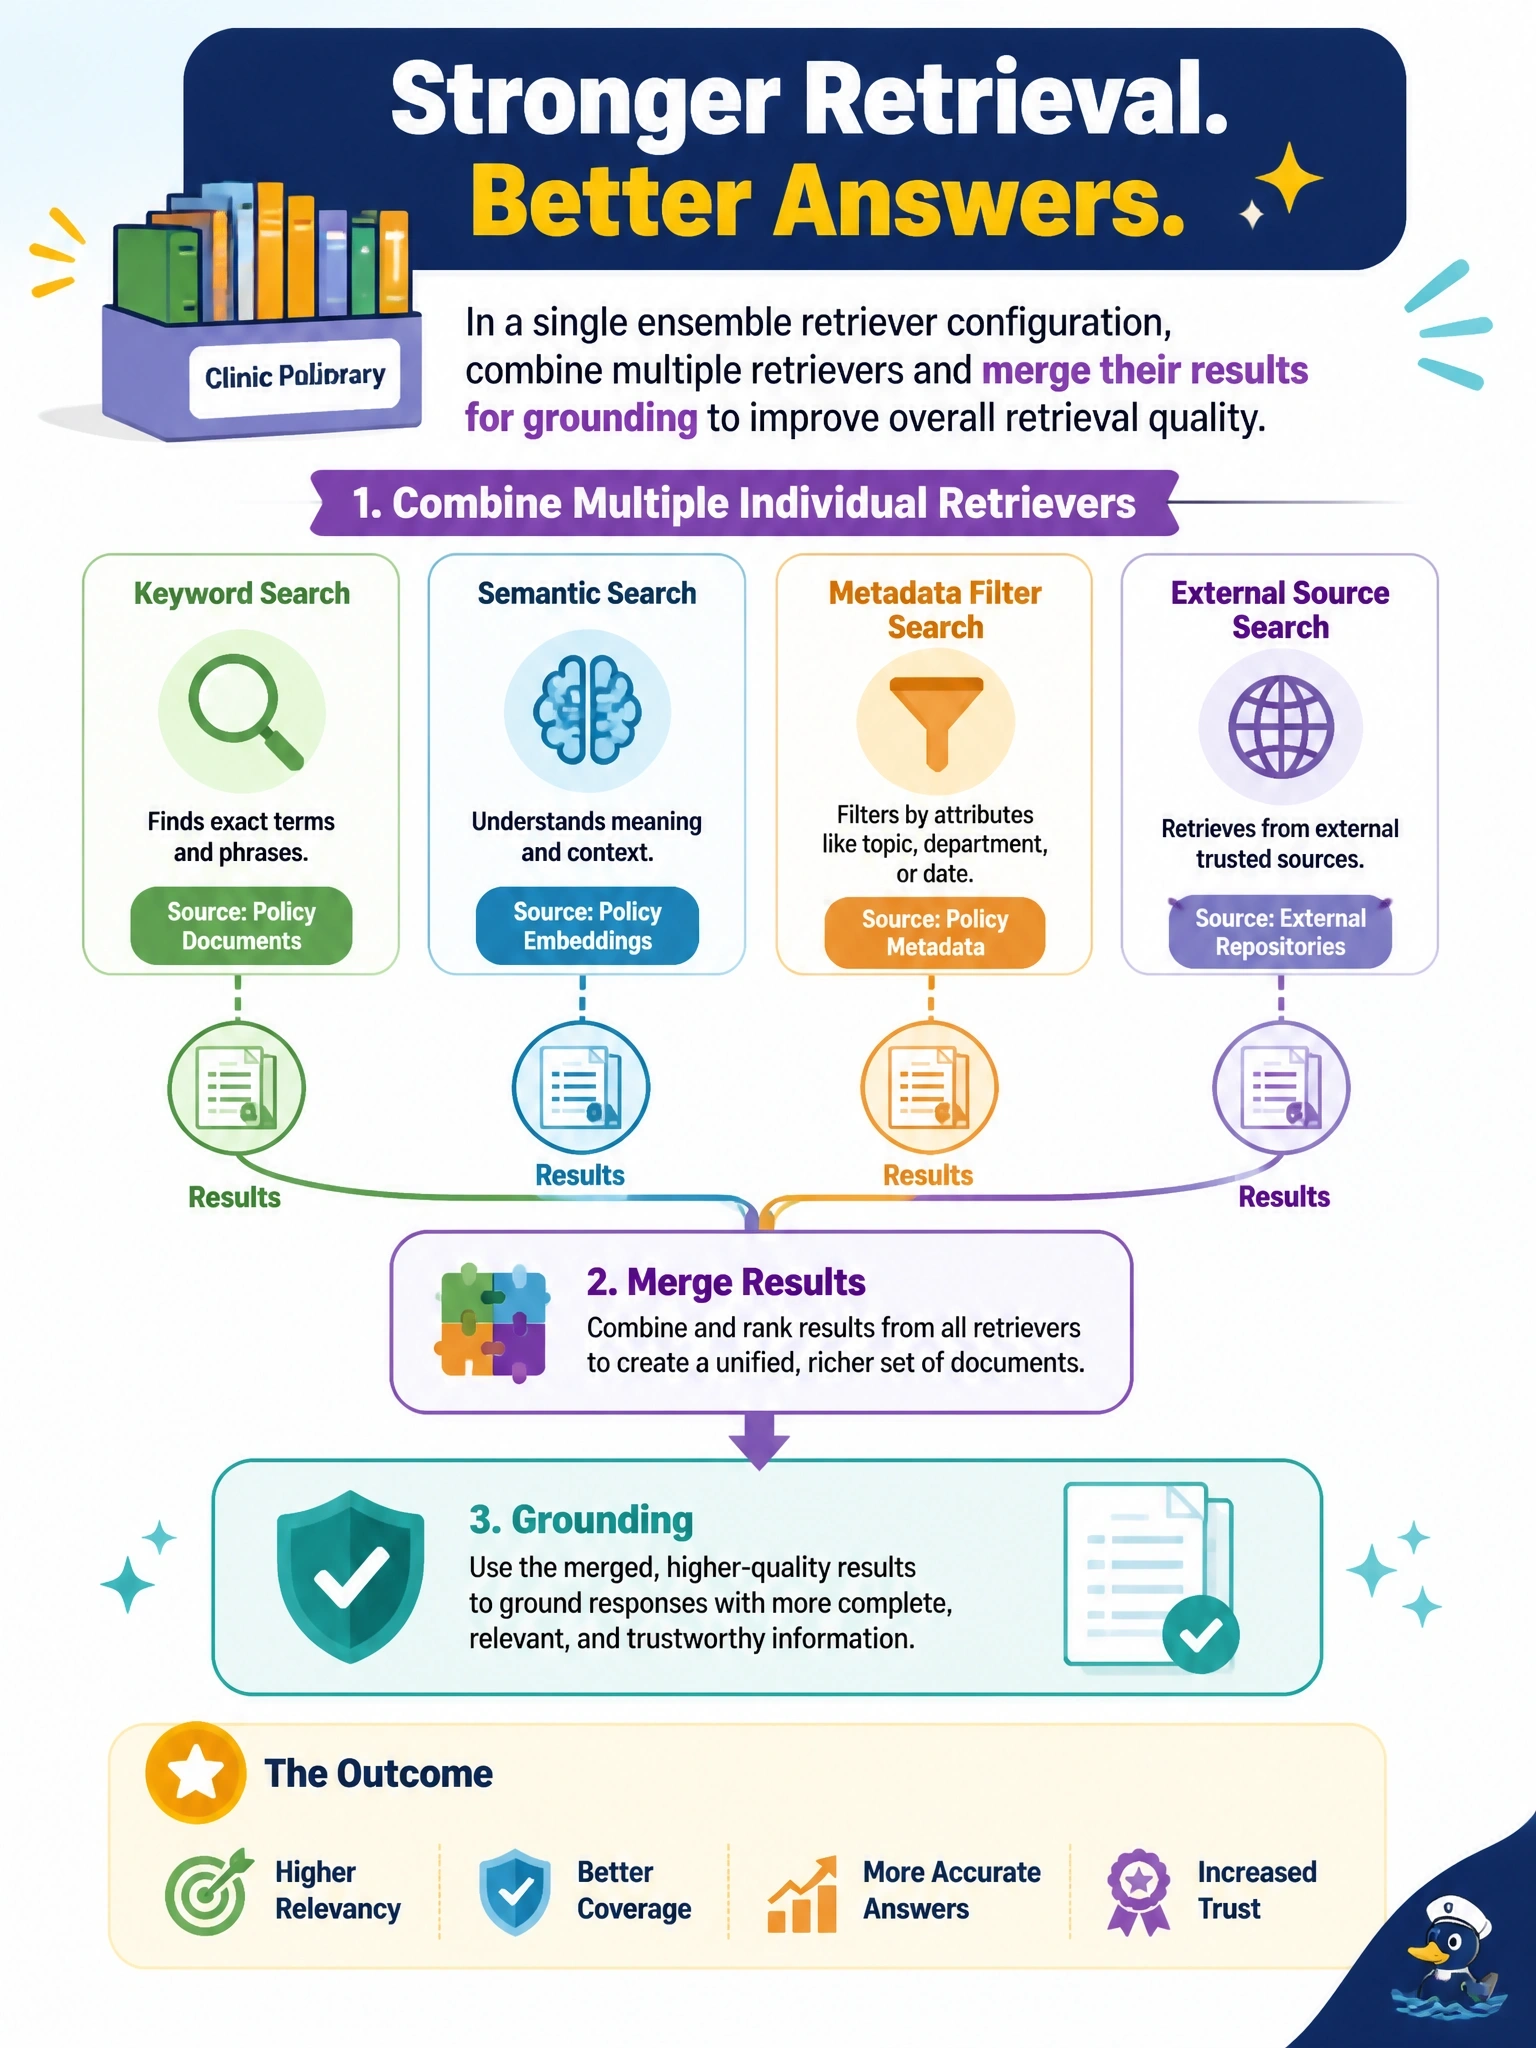
An ensemble retriever is a team of individual retrievers working the same problem from different angles, then pooling their best finds — not a way to blend unrelated things like owner records or agent types.
Full Explanation
An ensemble retriever's defining feature is combining multiple individual retrievers — which might differ by data source, by search type, or both — and merging their results into one relevant set for grounding. This directly improves quality on content like a policy library where some questions need exact-term matching and others need semantic matching, or where content is split across multiple related sources. Merging pet owners' private records into a shared profile is a data-privacy violation with nothing to do with retriever configuration, and Agentforce's design (including Trust Layer protections) works against exactly that kind of inappropriate data mixing. Running multiple agent types simultaneously on one conversation isn't how agent architecture works — a conversation is handled by one agent (of one type) at a time, with topics and actions determining behavior within that single agent. Masking rules in the Einstein Trust Layer are a data-protection mechanism, not a retrieval-quality technique, and there's no concept of applying them 'in a random order' as part of ensemble retrieval. The exam-relevant fact: ensemble retrieval is about combining retrievers, not about combining unrelated concepts like records, agent types, or masking rules.