
During setup, a Ridgeline admin notices a 12-page post-surgical discharge PDF is broken into many smaller pieces before it becomes searchable in Data 360. What is this process called, and why does it matter?
Select an answer to reveal the explanation.
Short Explanation
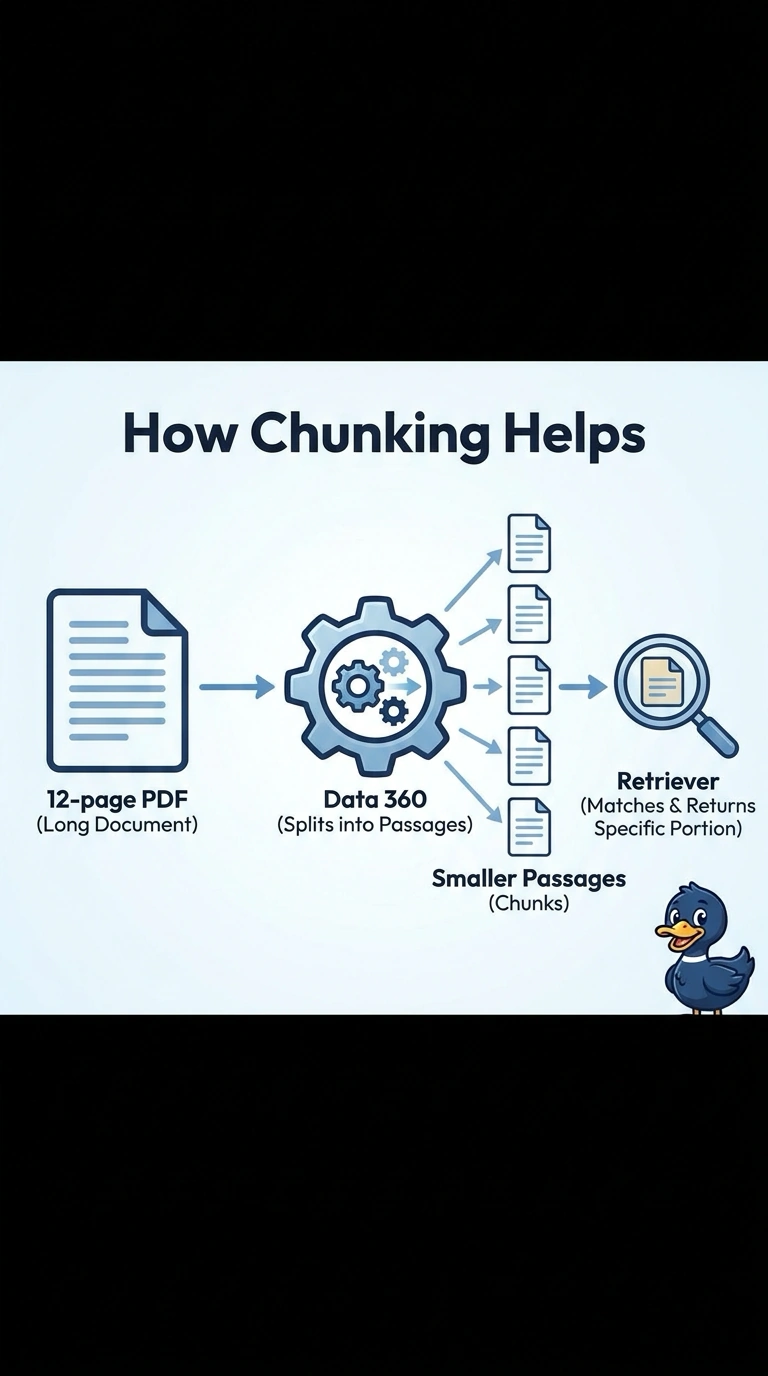
Nobody wants to hand an LLM an entire 12-page PDF just to answer 'when can Bella swim again' — chunking slices the document into bite-sized passages so the retriever can hand back exactly the paragraph that matters.
Full Explanation
Chunking breaks a long unstructured document into smaller, semantically coherent passages before indexing. This matters because retrieval works by matching a query against chunks, not whole documents — if the whole 12-page discharge sheet were treated as one unit, the agent would either receive far too much irrelevant text or fail to surface the one paragraph about incision care. Masking is a distinct Einstein Trust Layer function that redacts sensitive data like an owner's phone number before a prompt reaches the LLM — it has nothing to do with document segmentation. Activation refers to making a prompt template usable by an agent, an unrelated lifecycle step for templates rather than documents. Deduplication would address repeated content across files, which is a real hygiene concern for a document library but is not what this splitting step is called or primarily for. For the exam, remember chunking is the step that makes long unstructured content retrievable at the right granularity, feeding directly into the indexing step that follows it.