
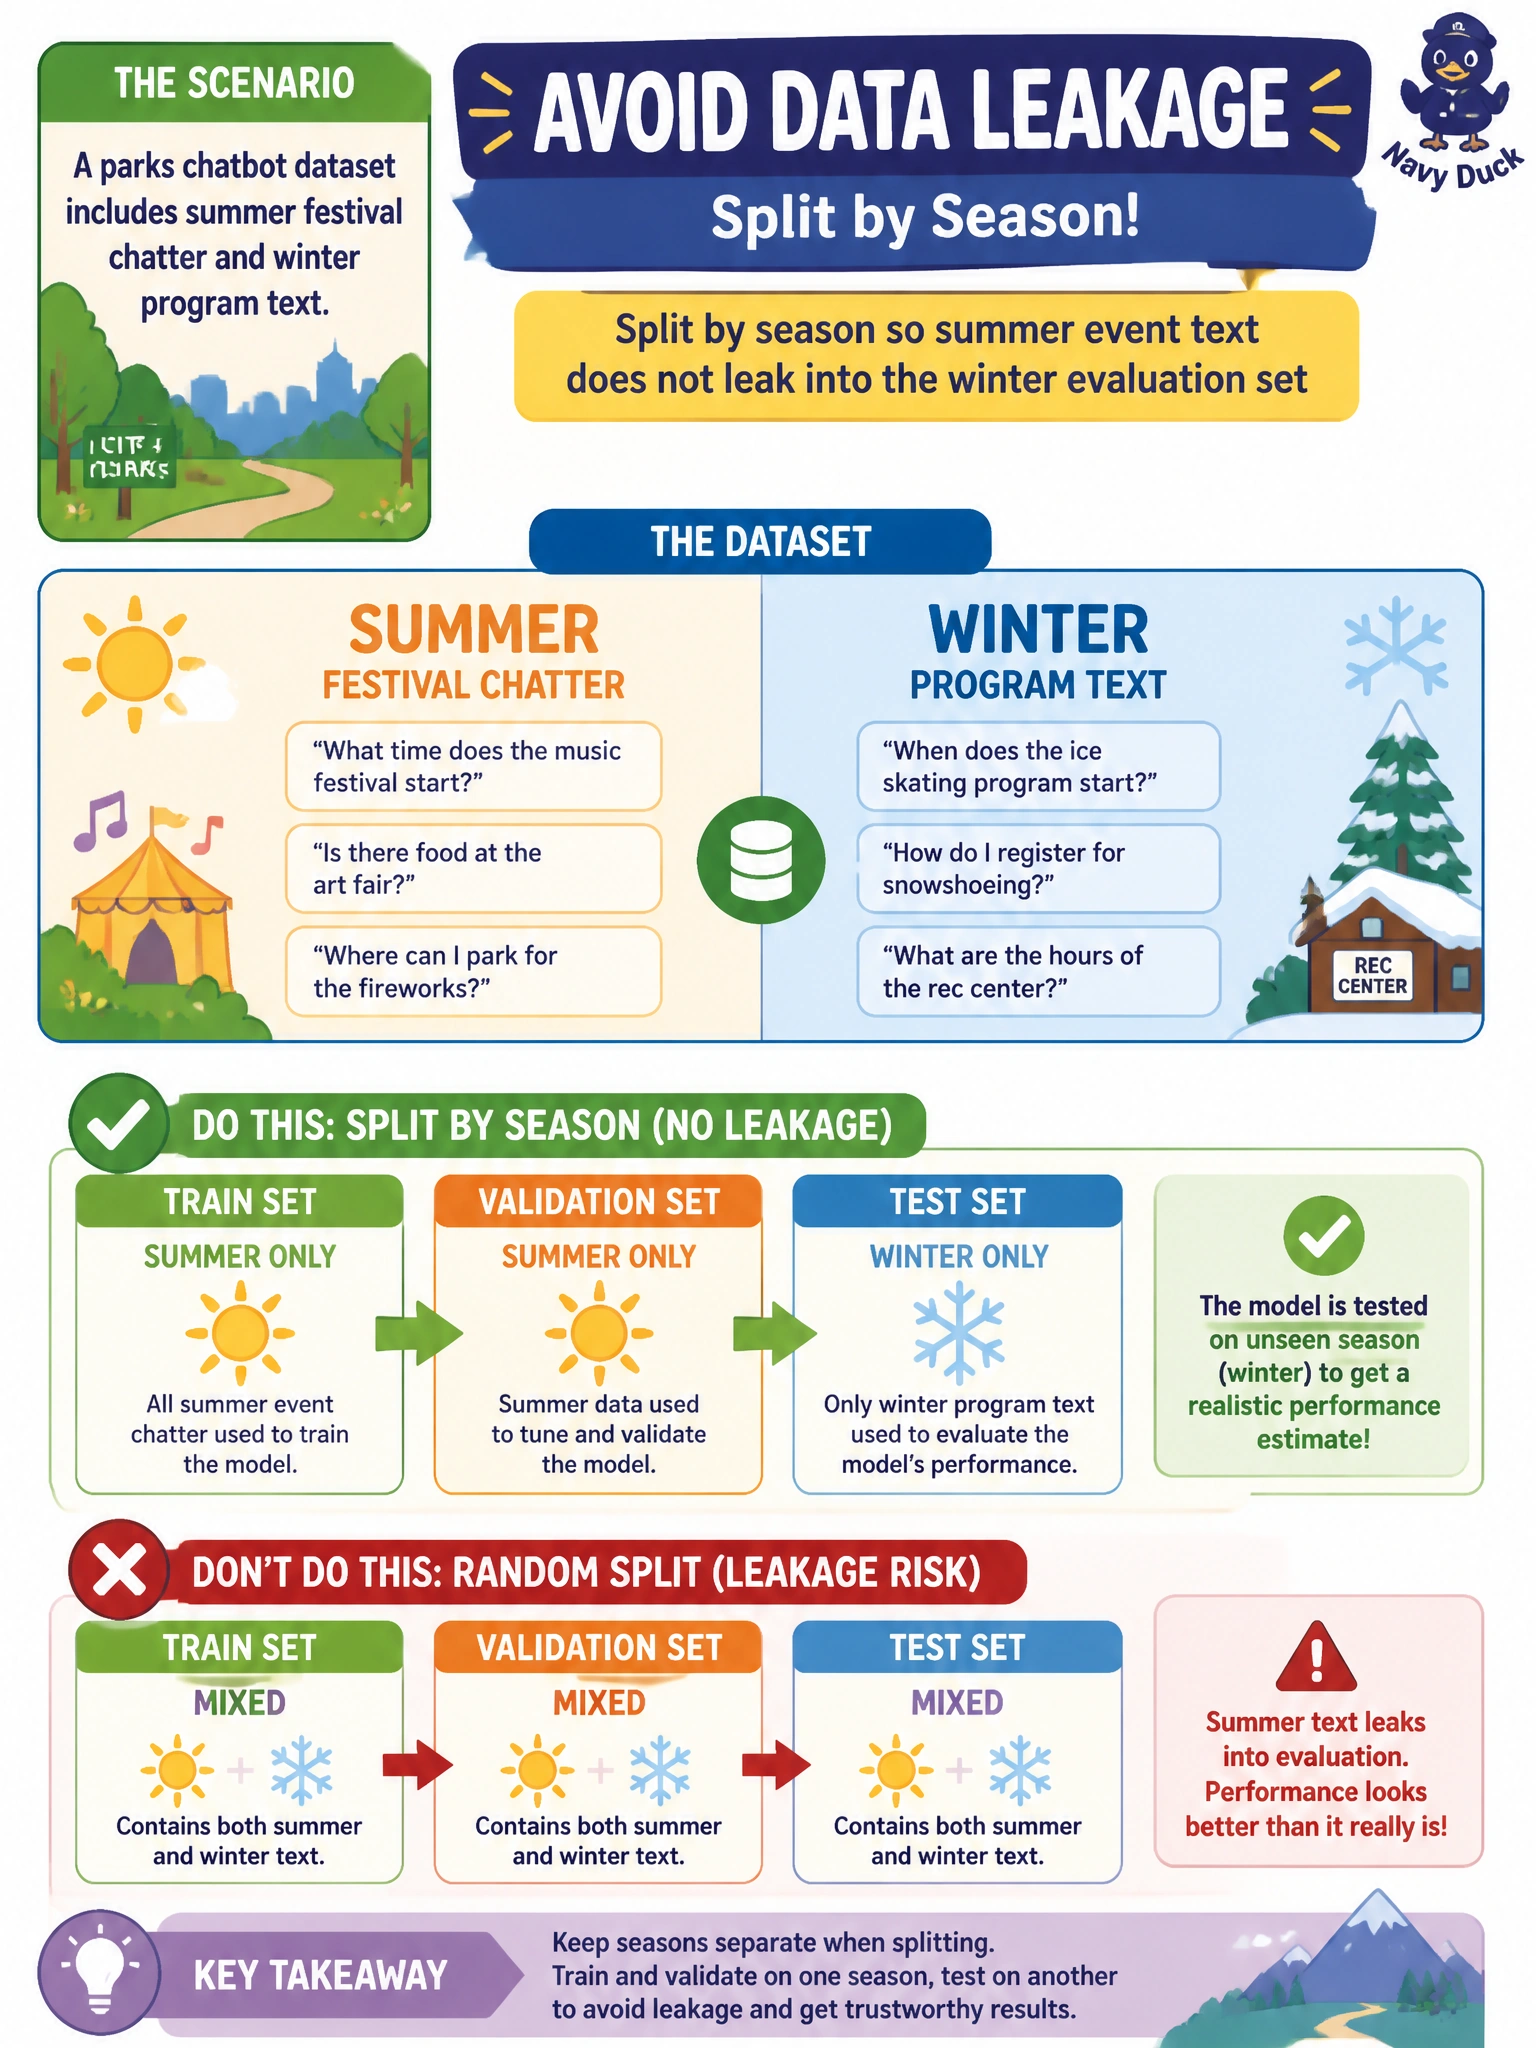
A parks chatbot dataset includes summer festival chatter and winter program text. How should the team split train, validation, and test to avoid leakage?
Select an answer to reveal the explanation.
Short Explanation
Don’t grade the winter exam with summer cheat sheets still in the desk. Split parks chat by season so festival talk doesn’t leak into the winter eval.
Full Explanation
To avoid leakage in a parks chatbot dataset that mixes summer festival chatter and winter program text, the team should split train, validation, and test by season so summer event text does not leak into the winter evaluation set. Seasonal topical overlap would otherwise let the model memorize festival phrases in training and look artificially strong on a 'winter' test that still contains summer threads. Civic-aware splitting respects real distribution shifts residents experience across seasons. Putting identical summer threads in both train and test maximizes reported accuracy via memorization and invalidates evaluation. Shuffling sentences so every season's phrases appear in all splits randomly spreads leakage everywhere and prevents honest seasonal generalization tests. Using only summer data for every split because festivals are more popular biases the model toward summer and provides no winter evaluation signal at all. Exam caveat: season-based splits are one leakage control; also prevent near-duplicate threads and shared template messages from crossing splits even within a season. Operational check: assign each thread a season tag, enforce disjoint seasons (or disjoint time windows) across splits, search for duplicate IDs across partitions, and report winter metrics only on winter-held data.