
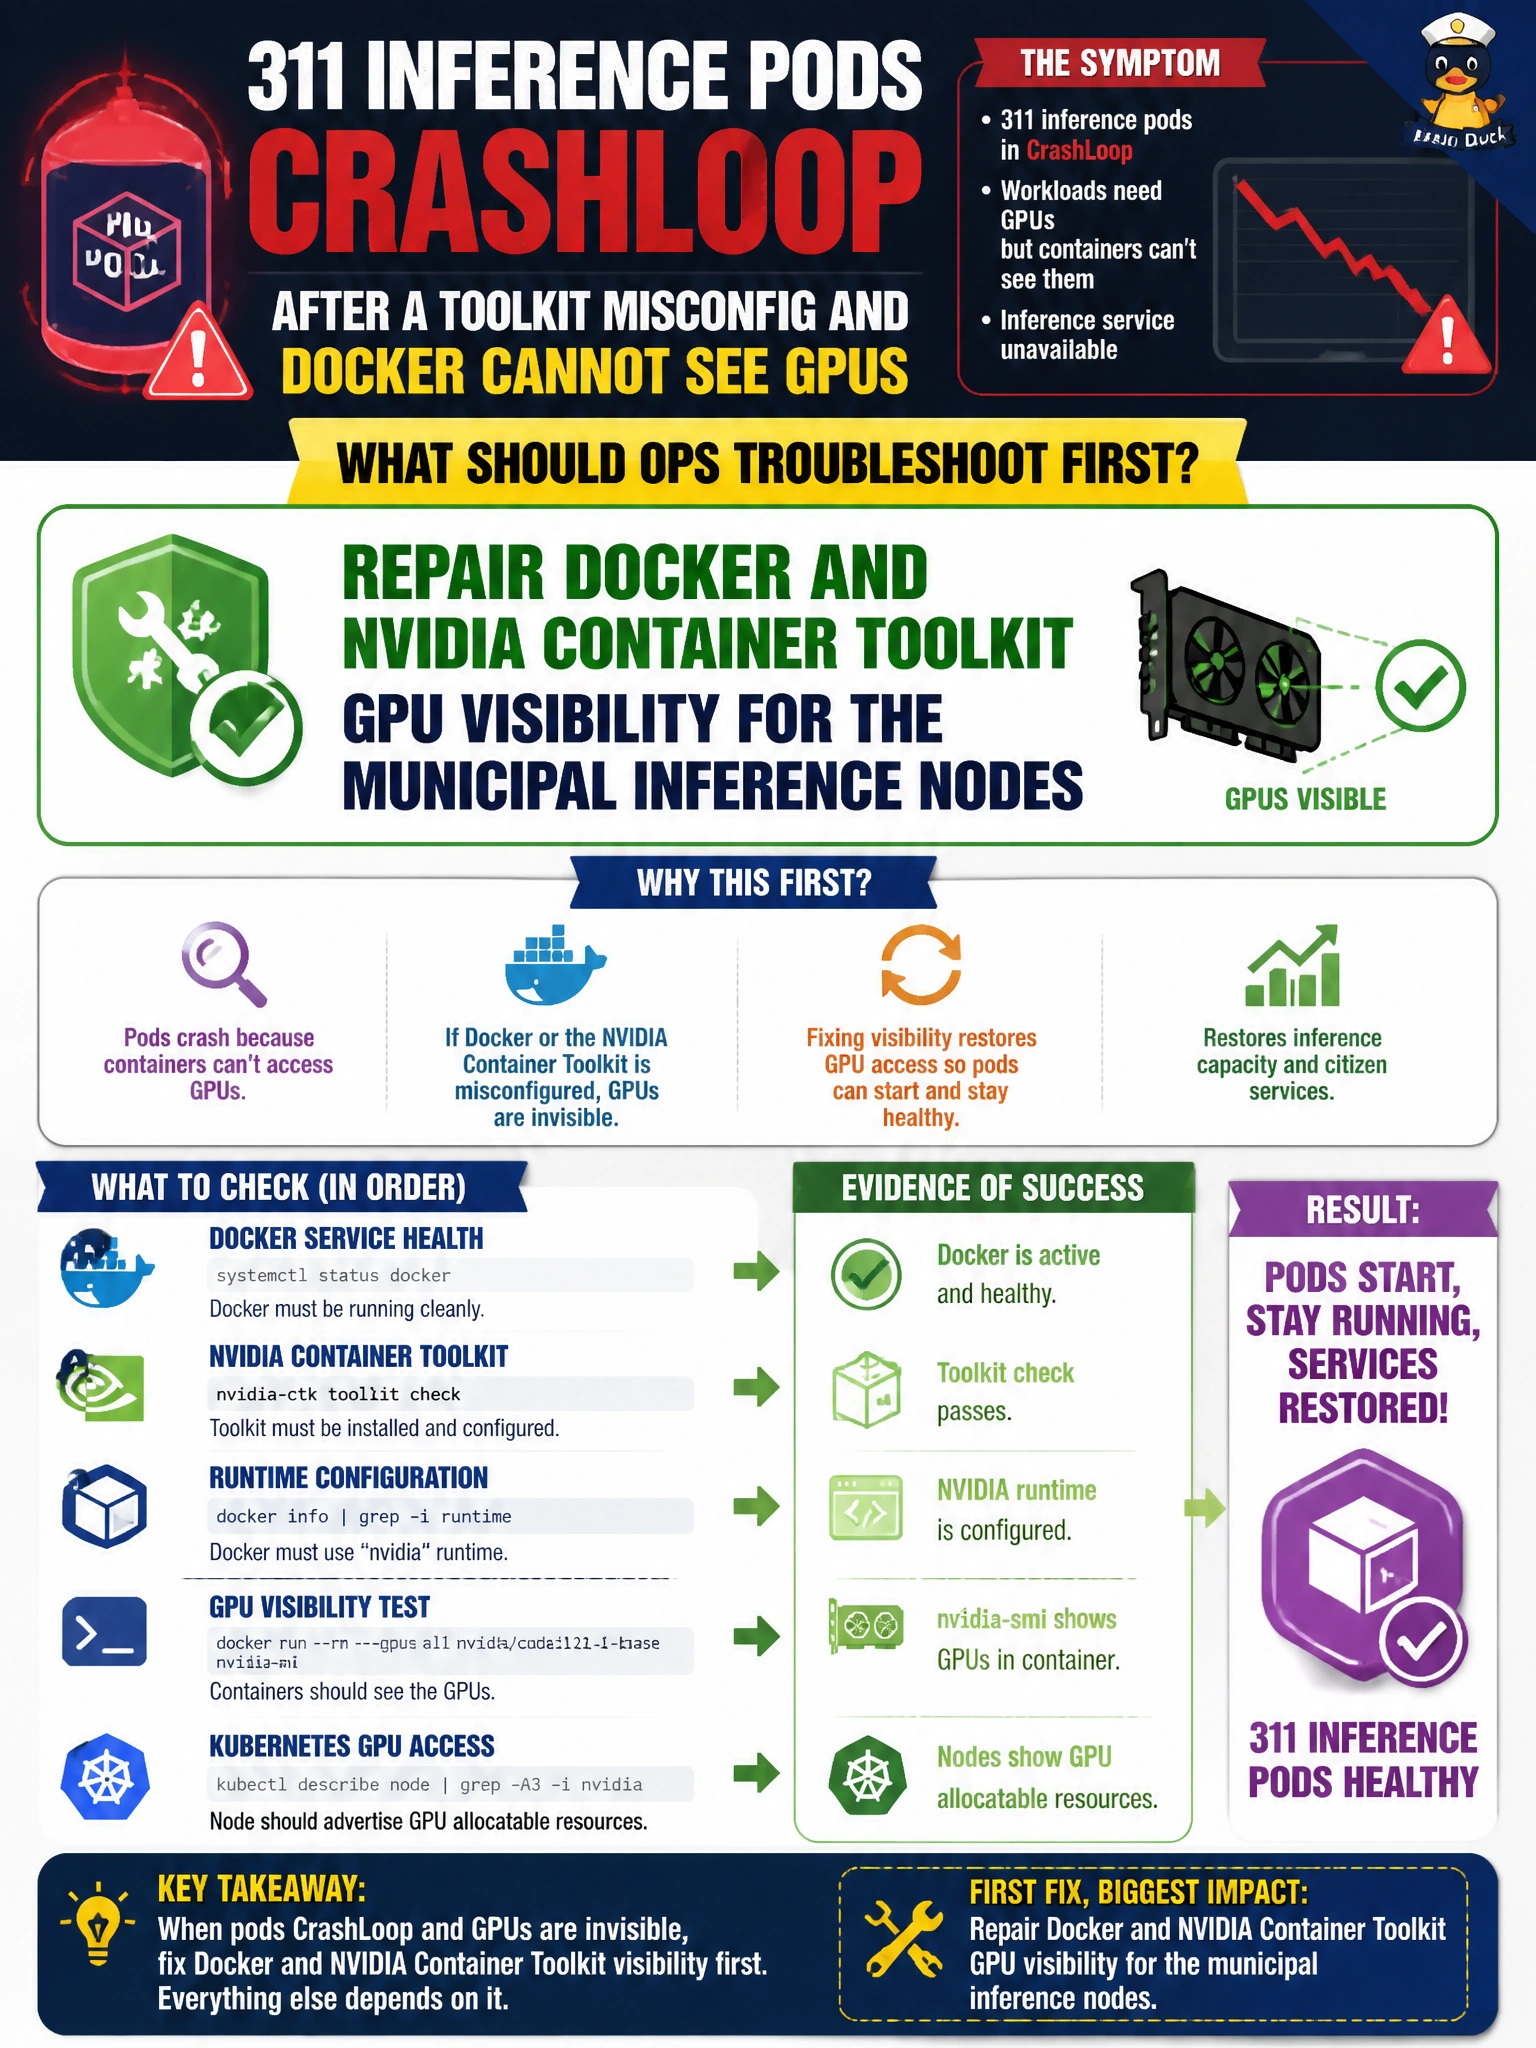
311 inference pods CrashLoop after a toolkit misconfig and Docker cannot see GPUs. What should ops troubleshoot first?
Select an answer to reveal the explanation.
Short Explanation
When 311 pods CrashLoop and Docker goes blind to GPUs, fix the toolkit/runtime visibility first—like clearing fogged glasses before rewriting the map. Yanking the API server or motherboards is overkill.
Full Explanation
When 311 inference pods CrashLoop and Docker cannot see GPUs after a toolkit misconfiguration, the first municipal triage is repairing Docker and NVIDIA Container Toolkit GPU visibility on the inference nodes. CrashLoops in this pattern usually mean the container runtime never injected device nodes, CDI specs, or the nvidia runtime, so the process starts, fails CUDA init, and Kubernetes restarts it. Restoring toolkit/runtime configuration reconnects nvidia-smi inside the container path to the host driver without demolishing the control plane.
Deleting the Kubernetes API server fails by concept: it destroys cluster control to "clear GPU state," which is unrelated to node-local runtime visibility and causes a citywide outage. Disabling all GPUs citywide fails because it turns a node misconfig into a service blackout and does not repair the toolkit. Replacing every motherboard before checking runtime config fails the troubleshooting order: hardware swap is unjustified when the symptom is "Docker cannot see GPUs" after a known toolkit change.
Exam caveat: GPU CrashLoops have many causes (requests/limits, device plugin, MIG, drivers), but the stem explicitly points at toolkit misconfig and Docker blindness—answer the stem, do not leap to rack replacement. Also distinguish host nvidia-smi working while containers fail (classic toolkit/runtime path) from host driver failure (broader outage).
Operational check: on an affected node, confirm host driver health, validate NVIDIA Container Toolkit packages and Docker runtime/daemon.json (or CDI) settings, restart Docker/kubelet as required by site runbooks, then docker run --gpus all (or equivalent) a CUDA sample. Only after GPU visibility returns should you roll the 311 deployment and watch CrashLoop counters clear.