
Water-utility InfiniBand nodes show unexplained resets. What should operators correlate?
Select an answer to reveal the explanation.
Short Explanation
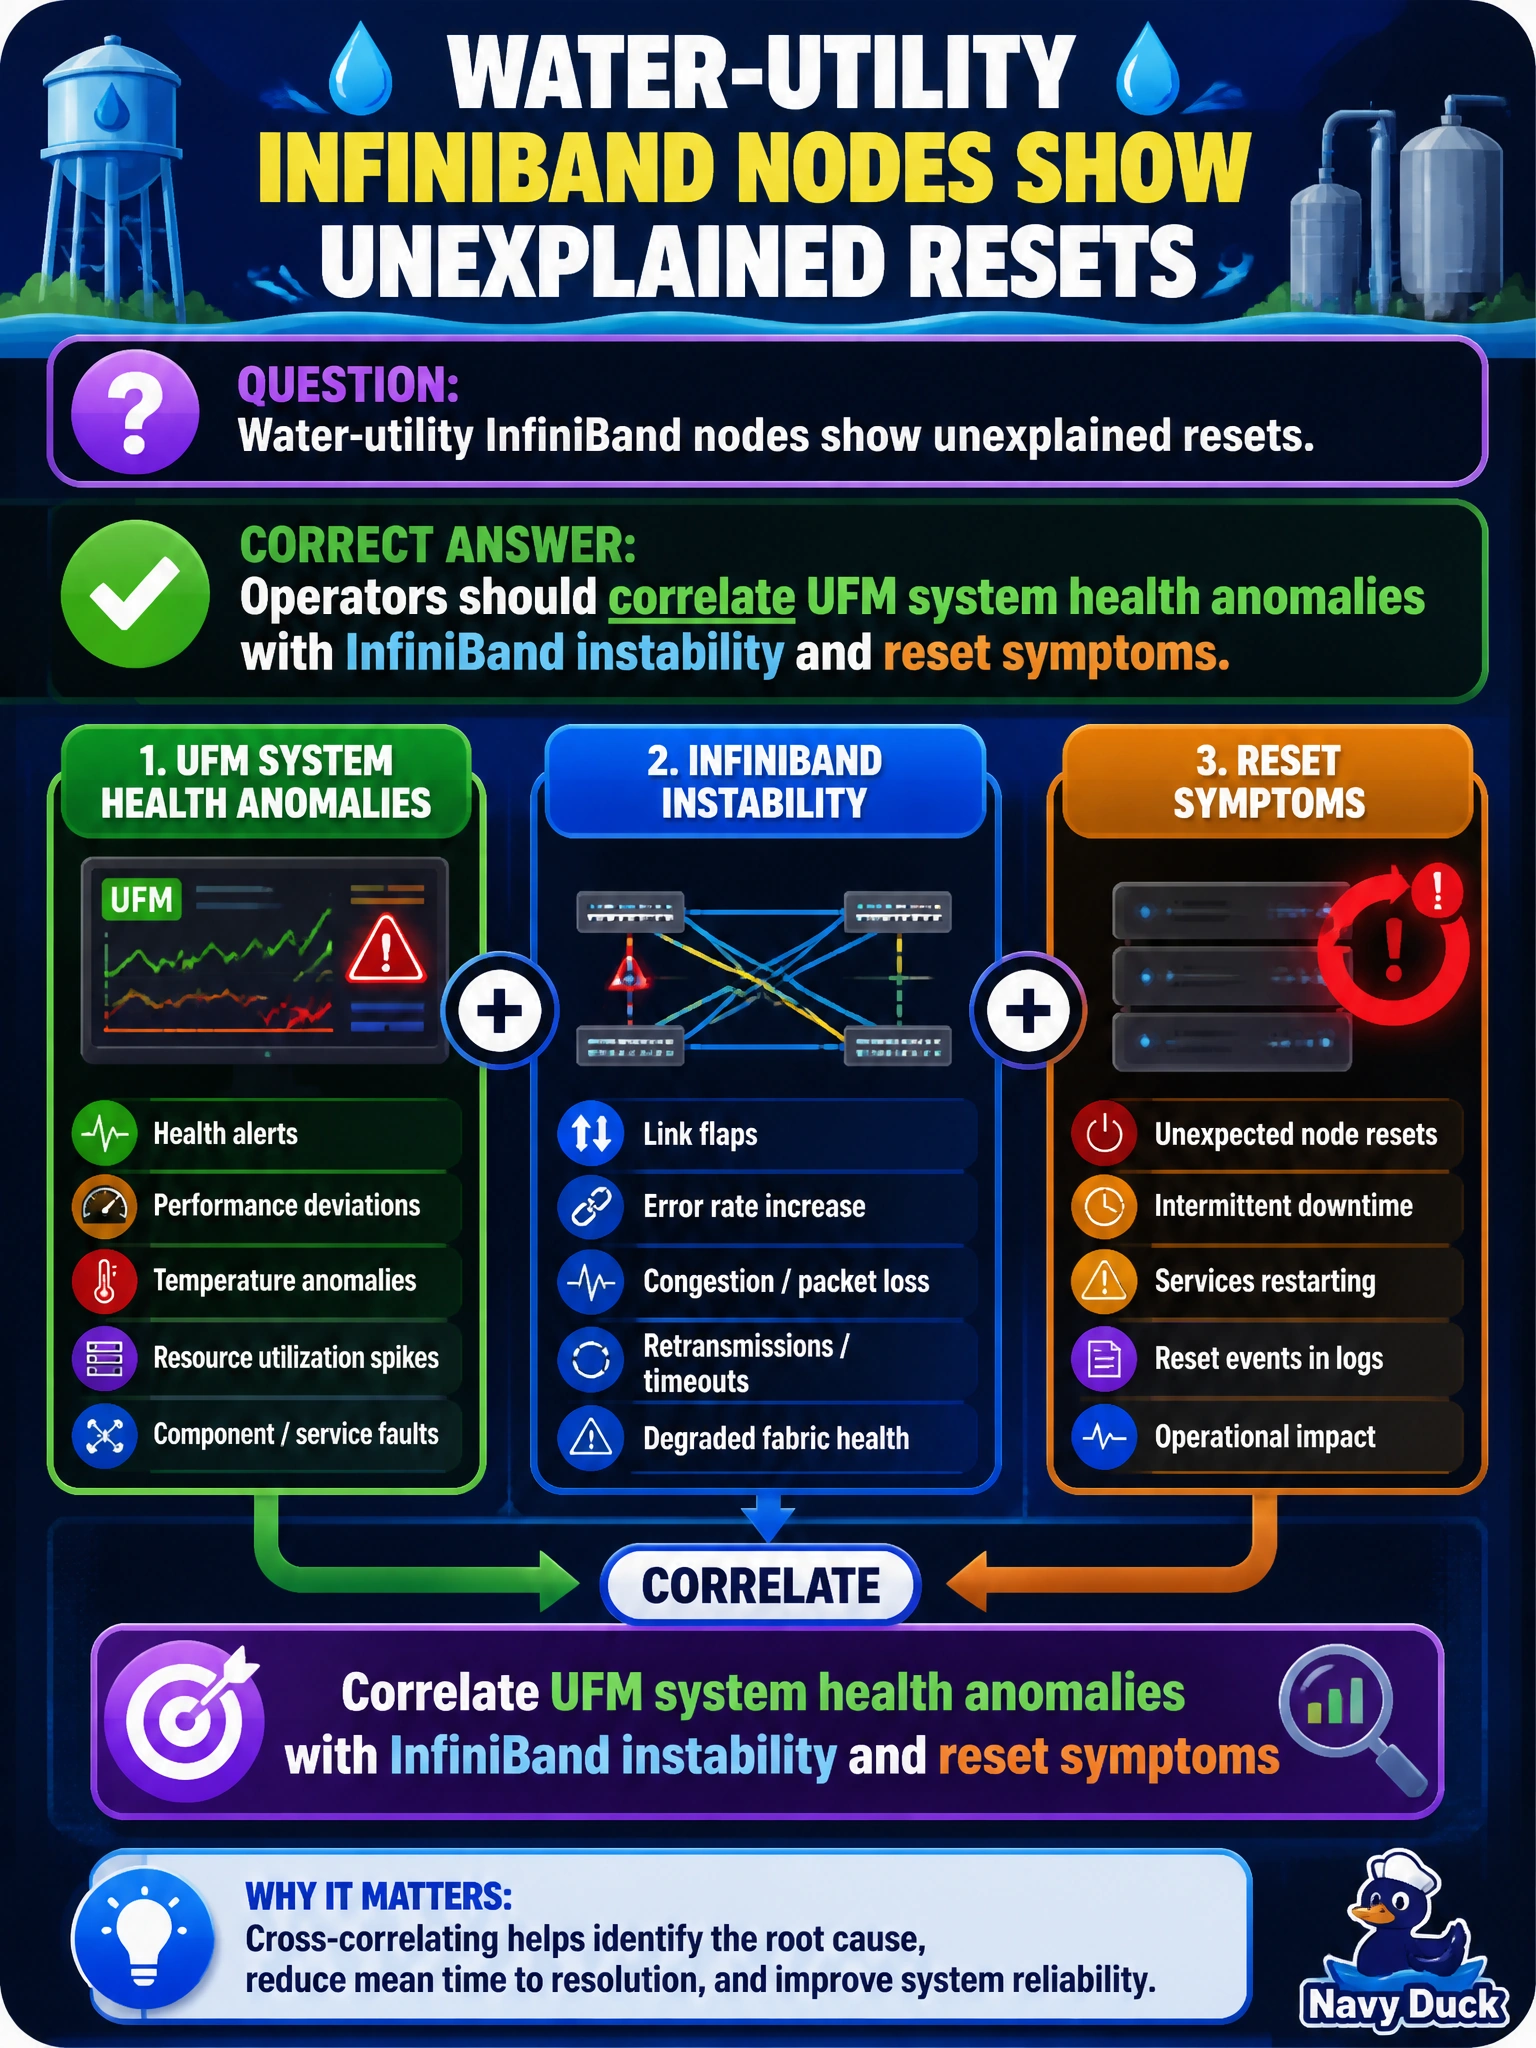
Unexplained IB resets usually leave fingerprints somewhere. Correlate UFM system health anomalies with water-utility InfiniBand instability instead of guessing in the dark.
Full Explanation
Water-utility InfiniBand nodes showing unexplained resets should be correlated with UFM system health anomalies tied to InfiniBand instability and reset symptoms. Fabric health events often precede or accompany node resets; correlating those timelines gives municipal operators a causal hypothesis instead of correlating InfiniBand partition membership updates with MPI scheduler queue depth patterns.
Why the other options fail by concept: UFM congestion telemetry trends with Ethernet edge switch buffer utilization are, at best, an indirect proxy for network load; they do not surface InfiniBand fabric events or anomalies the way UFM system health does, so they cannot establish the fabric-side cause of the resets. Correlating InfiniBand partition membership updates with MPI scheduler queue depth patterns treats an unrelated control-plane and scheduler signal as the experiment instead of first correlating UFM system health anomalies with the reset timeline; watching for alignment between those unrelated metrics still wastes cycles if they were never the cause of the resets. Matching HCA link flap counters with regular data center cooling cycle maintenance schedules is, at best, an environmental correlation; it does not surface InfiniBand fabric health anomalies the way UFM system health does, so it cannot establish the fabric-side cause of the resets.
Exam caveat: correlation still requires care—application faults and fabric faults can both reset jobs or links. Prefer multi-signal evidence (UFM health, port counters, host logs) and confirm that resets align with specific health anomalies on the paths those water-utility nodes use.
Operational check: for unexplained IB resets, pull UFM system health around each reset timestamp, note matching anomalies, stop correlating InfiniBand partition membership updates with MPI scheduler queue depth patterns until health data is reviewed, and open a fabric or SM ticket when anomalies align with the reset pattern.