
InfiniBand jobs stall in a municipal AI factory and control-plane health is suspect. What should operators use?
Select an answer to reveal the explanation.
Short Explanation
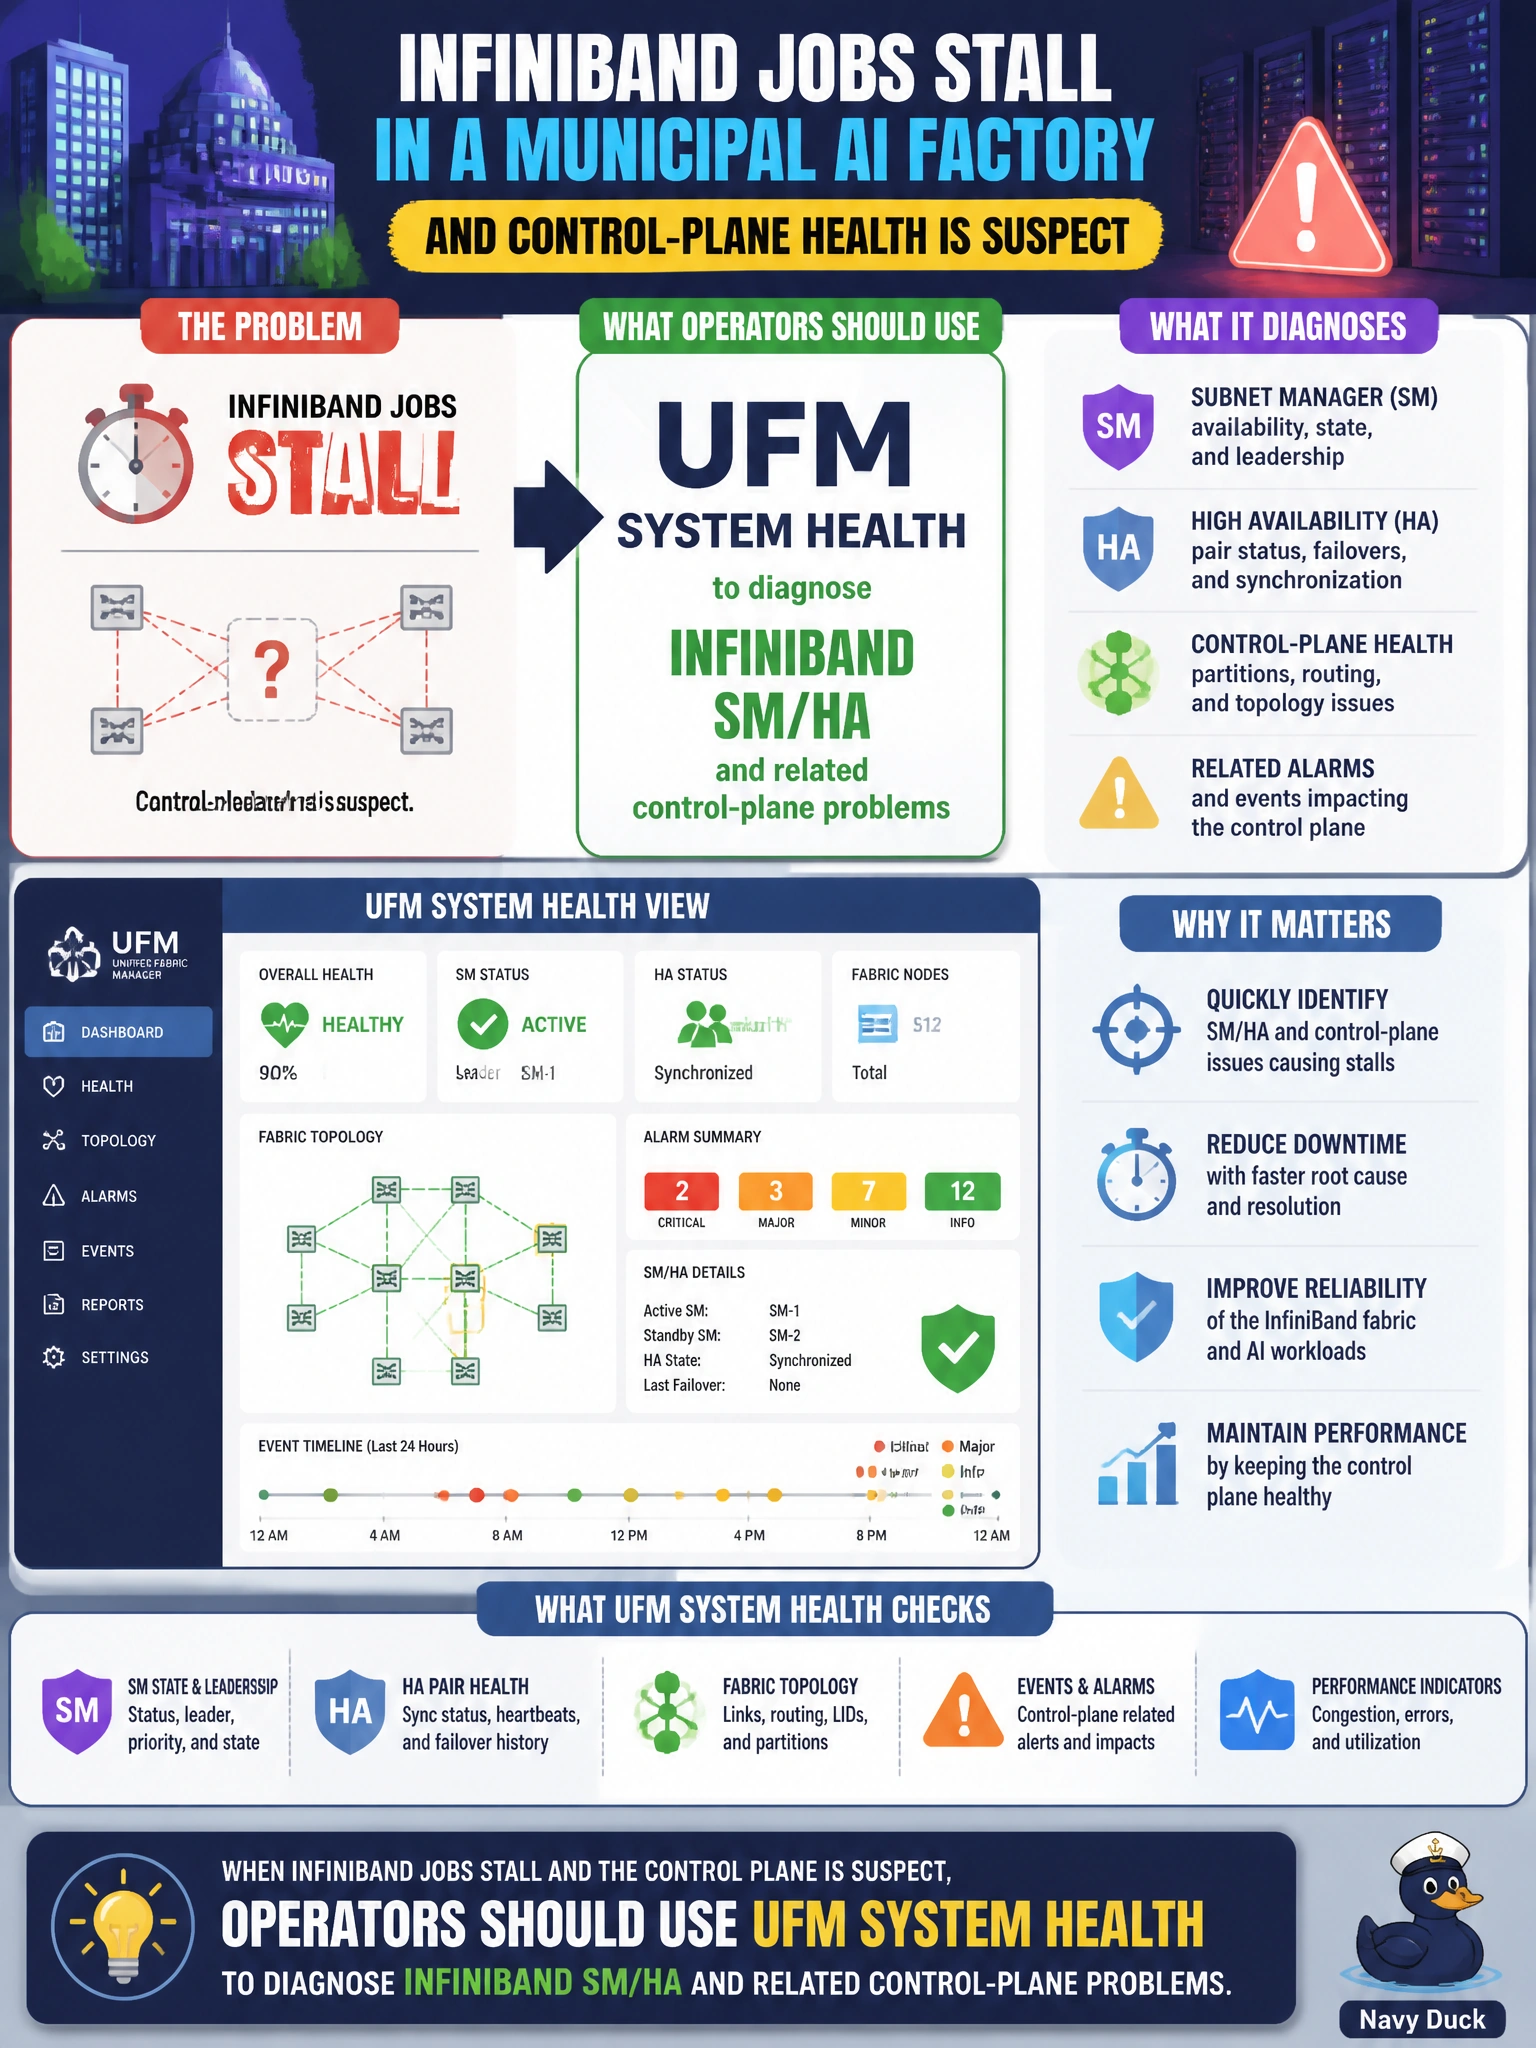
Stalled IB jobs with a sick control plane need a fabric doctor, not a console wipe. Use UFM system health to diagnose InfiniBand SM/HA problems in the municipal AI factory. UFM telemetry snapshots for link congestion and port counters only show data-plane traffic, not SM/HA control-plane health, so they won't fix a sick control plane.
Full Explanation
When InfiniBand jobs stall in a municipal AI factory and control-plane health is suspect, operators should use UFM system health to diagnose InfiniBand subnet manager (SM)/high-availability and related control-plane problems. Link lights alone do not explain SM failover issues, partition problems, or fabric service degradation that stop jobs even when cables look fine.
Why the other options fail by concept: UFM telemetry snapshots to review InfiniBand link congestion and port traffic counters fail because they only capture data-plane metrics like link utilization and port counters, which do not reveal subnet manager health, HA state, or control-plane service degradation; a stall caused by a struggling subnet manager will persist even if telemetry shows clean links, so you'll misdiagnose the problem. A narrow correlation of UFM alert logs with InfiniBand subnet manager trap messages fails as the first move because it jumps straight to a specific log-matching exercise before confirming overall UFM system health; operators need the broader health picture first to know which service is actually degraded before correlating individual log sources. Refreshing the InfiniBand partition configuration to reset SM failover state fails because it is a configuration change made without first diagnosing what is actually wrong; resetting failover state blind can mask or even worsen an underlying control-plane problem instead of revealing it through UFM system health.
Exam caveat: UFM system health points at control-plane and fabric-service domains; it does not replace host-level RDMA benchmarks once SM/HA is confirmed healthy. Distinguish SM problems from pure data-plane congestion so you do not “fix” the wrong layer.
Operational check: on IB job stalls with control-plane suspicion, open UFM system health first, inspect SM/HA and related service status, capture the health state in the incident ticket, and only proceed to host ibstat or bandwidth tools after control-plane health is understood.