
A county clinic correlates AI job failures with Spectrum leaf events. What should operators map first?
Select an answer to reveal the explanation.
Short Explanation
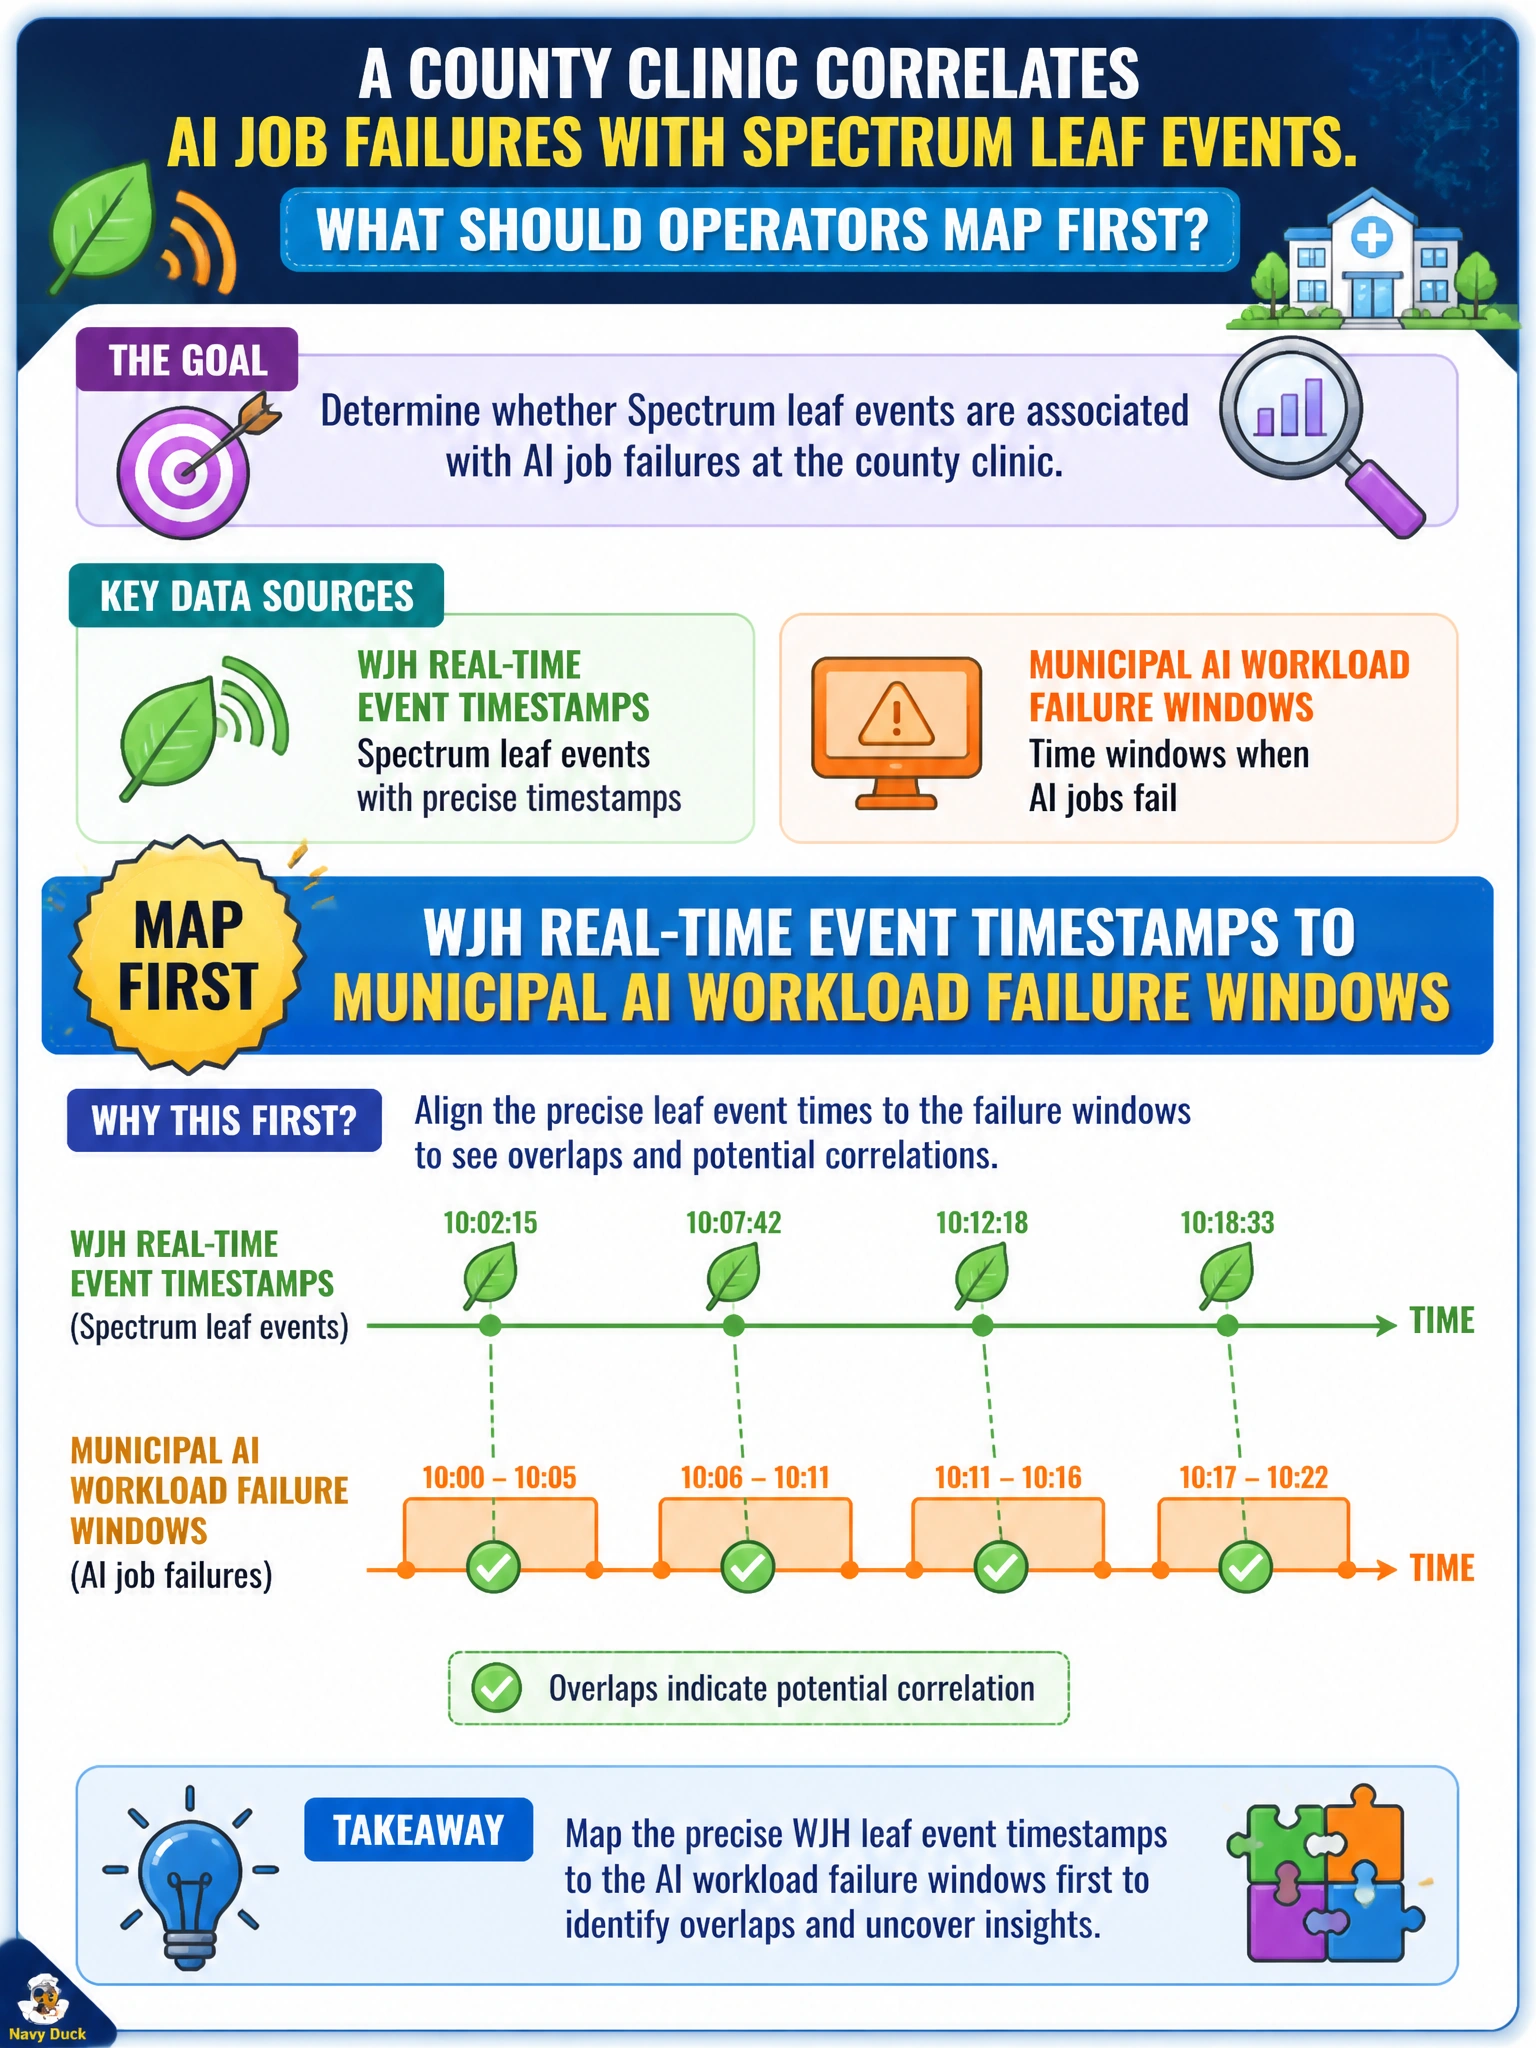
Checkpoint timestamps and aggregated throughput windows blur exactly when a job died. Line up WJH's real-time event timestamps with the failure window so you'll know whether the fabric caused the crash.
Full Explanation
County clinic AI job failures that coincide with Spectrum leaf events require a shared timeline before any remediation. What You See Happening (WJH) on Spectrum exposes real-time fabric events with precise timestamps; operators must map those timestamps onto the municipal AI workload failure windows so leaf congestion, discards, or link events line up with training or inference crashes. Without that correlation, Spectrum and the clinic scheduler remain two unrelated logs and root cause stays guesswork.
Why the other options fail by concept: WJH leaf buffer alert timestamps mapped to municipal AI workload checkpoint windows line up with periodic save points rather than crash moments, so checkpoint alignment cannot isolate the exact failure timestamp of a clinic AI job. WJH Spectrum port counter snapshots mapped to AI job launch time windows capture static port states when jobs start, not the live failure timeline, so they cannot reveal when or why a job actually crashed. WJH ECN marking rate averages mapped to municipal AI throughput windows aggregate congestion into broad throughput trends, erasing the precise event timestamps needed to tie a specific job failure to a Spectrum leaf. WJH timestamp correlation must come first to establish the causal link.
Exam caveat: WJH correlation proves temporal alignment, not automatic guilt—clock skew between the fabric and the AI orchestrator must be accounted for, and multiple concurrent leaf events may need category filters before assigning blame. Also, not every GPU failure is network-induced; use correlation as a hypothesis gate, not as a sole verdict.
Operational check: after a clinic job failure cluster, export WJH events for the Spectrum leafs serving those nodes, overlay them on the job-failure timeline within a tight window (seconds to minutes), confirm matching discard or congestion categories, then open a targeted ticket with leaf, port, and time rather than a blanket GPU reboot.