
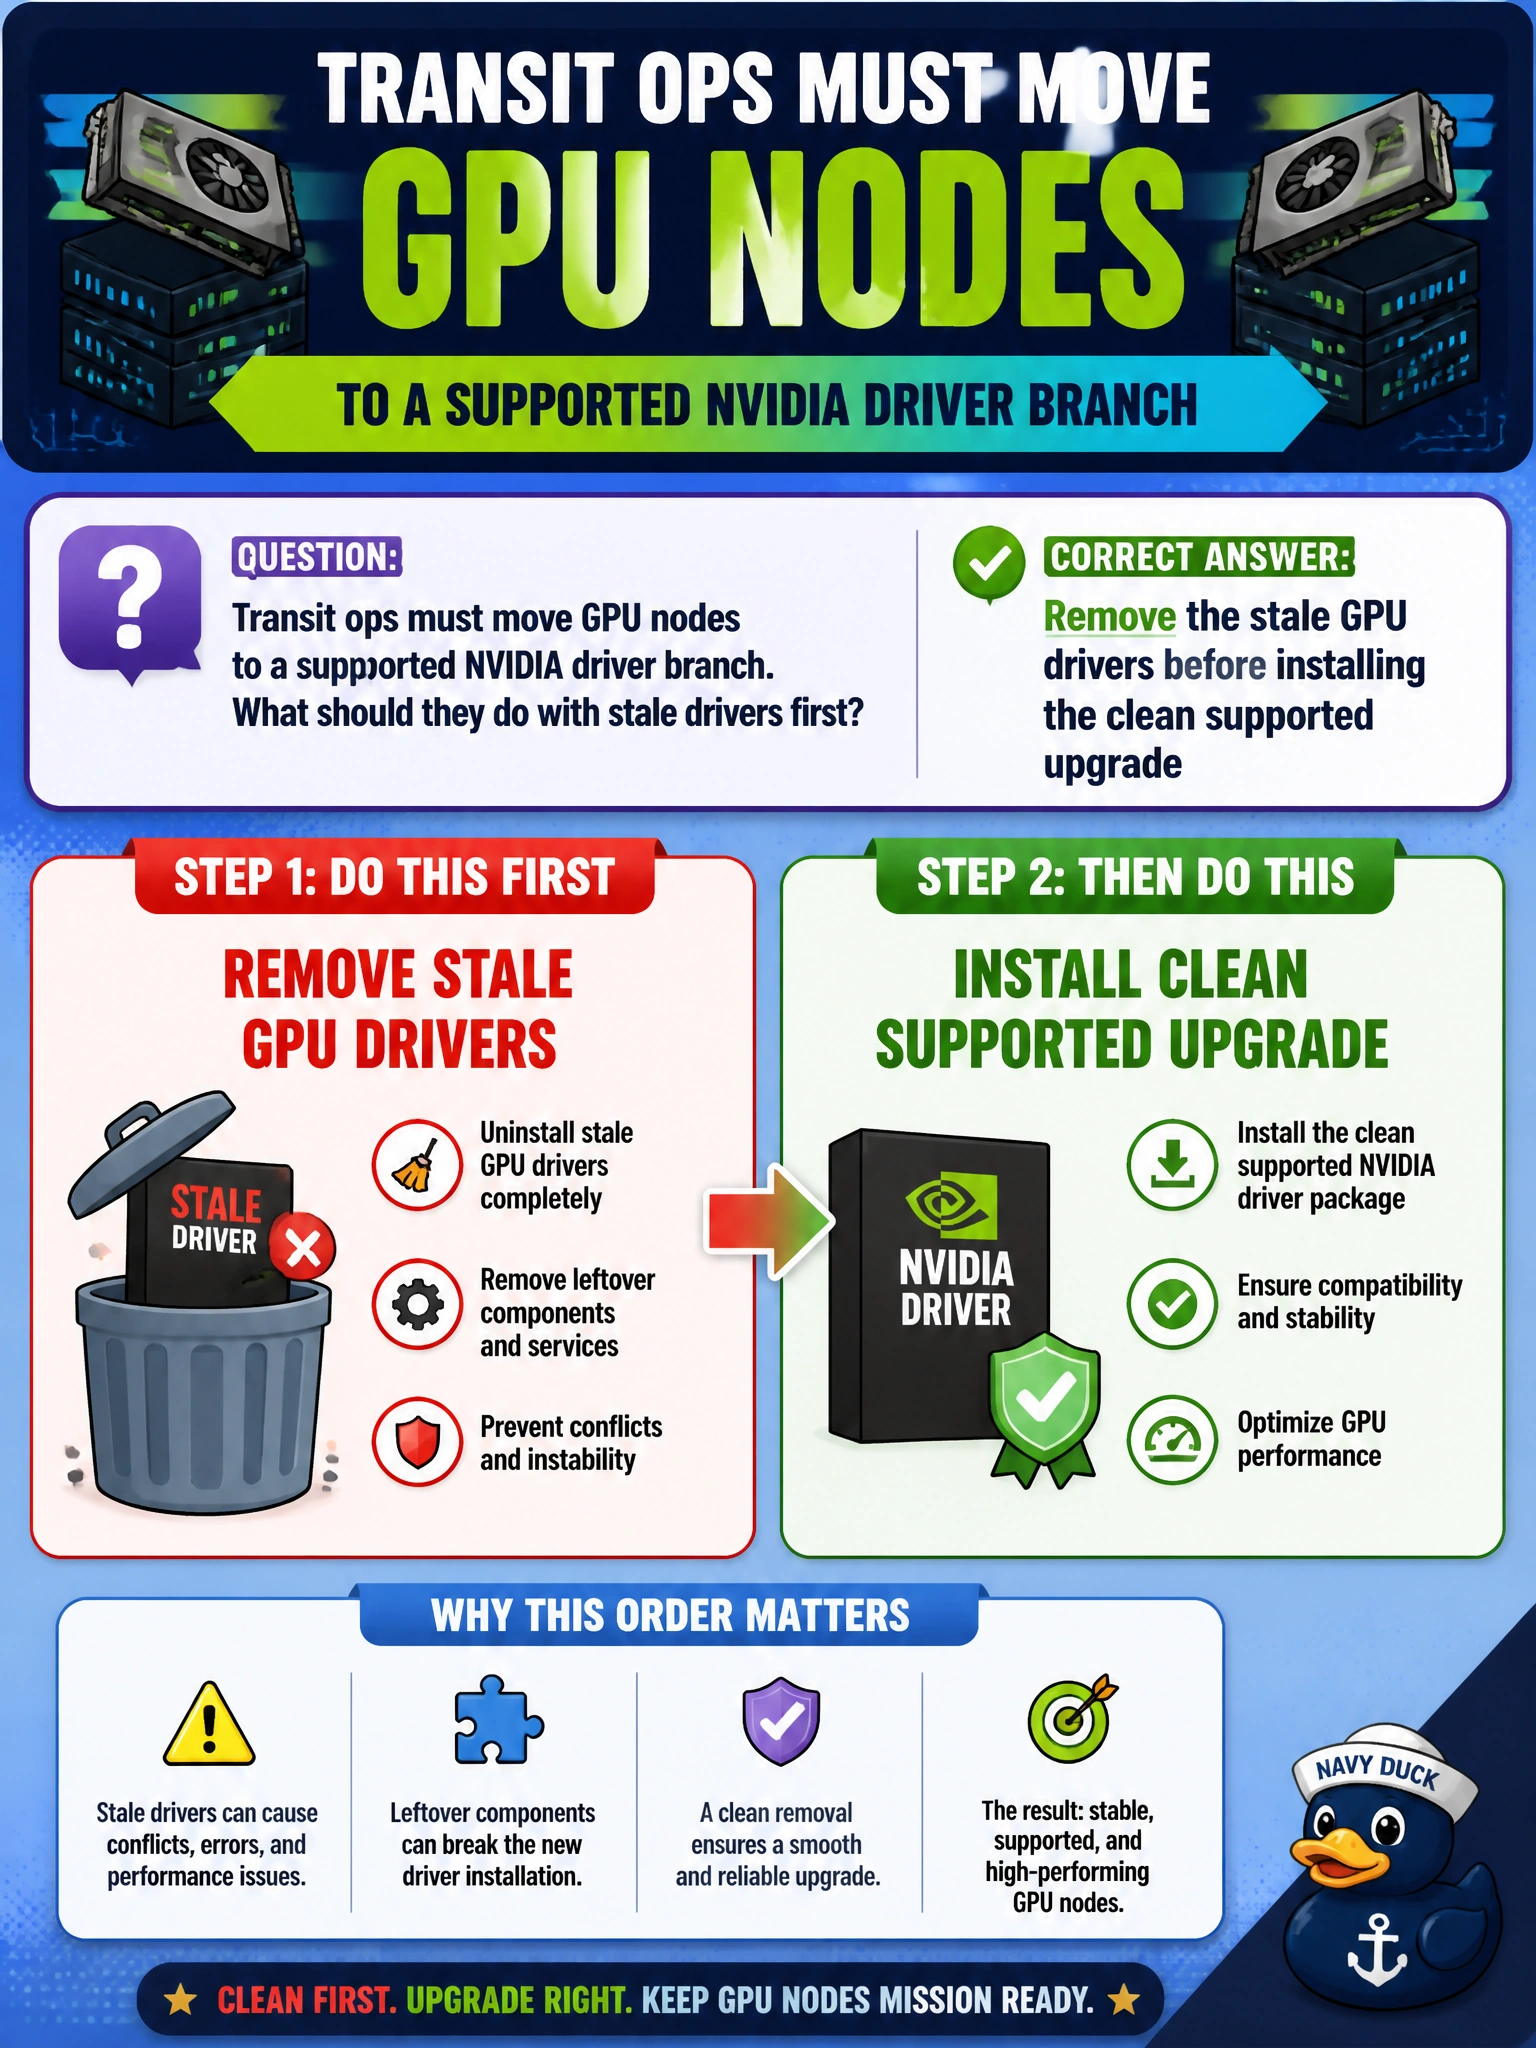
Transit ops must move GPU nodes to a supported NVIDIA driver branch. What should they do with stale drivers first?
Select an answer to reveal the explanation.
Short Explanation
Yank the old GPU drivers before the clean upgrade—like clearing yesterday’s maps before loading the new route book. Stacking mess on mess just prolongs the outage.
Full Explanation
Transit ops moving GPU nodes to a supported NVIDIA driver branch should remove stale GPU drivers before installing the clean upgrade. Residual packages, DKMS artifacts, and loaded conflicting modules are a common cause of failed or partially broken upgrades; cleanup creates a known baseline for the supported branch on municipal training and inference nodes. Document removed package versions in the change record so transit change control can prove the node started clean.
Layering the new branch over broken packages without cleanup invites symbol conflicts and opaque failures that waste the maintenance window. Deleting only documentation while leaving conflicting modules loaded does not clear the runtime or packaging conflict. Renaming old .ko files with a .bak suffix and rebooting forever is an unsupported hack that skips proper package removal and module management.
Exam caveat: upgrade hygiene is remove-stale-then-install-clean—not layering, doc-only deletes, or manual .ko renames.
Operational check: drain the node, uninstall/remove old NVIDIA driver packages and modules per procedure, install the supported branch, reboot, and confirm nvidia-smi before reintroducing the node to Slurm.