
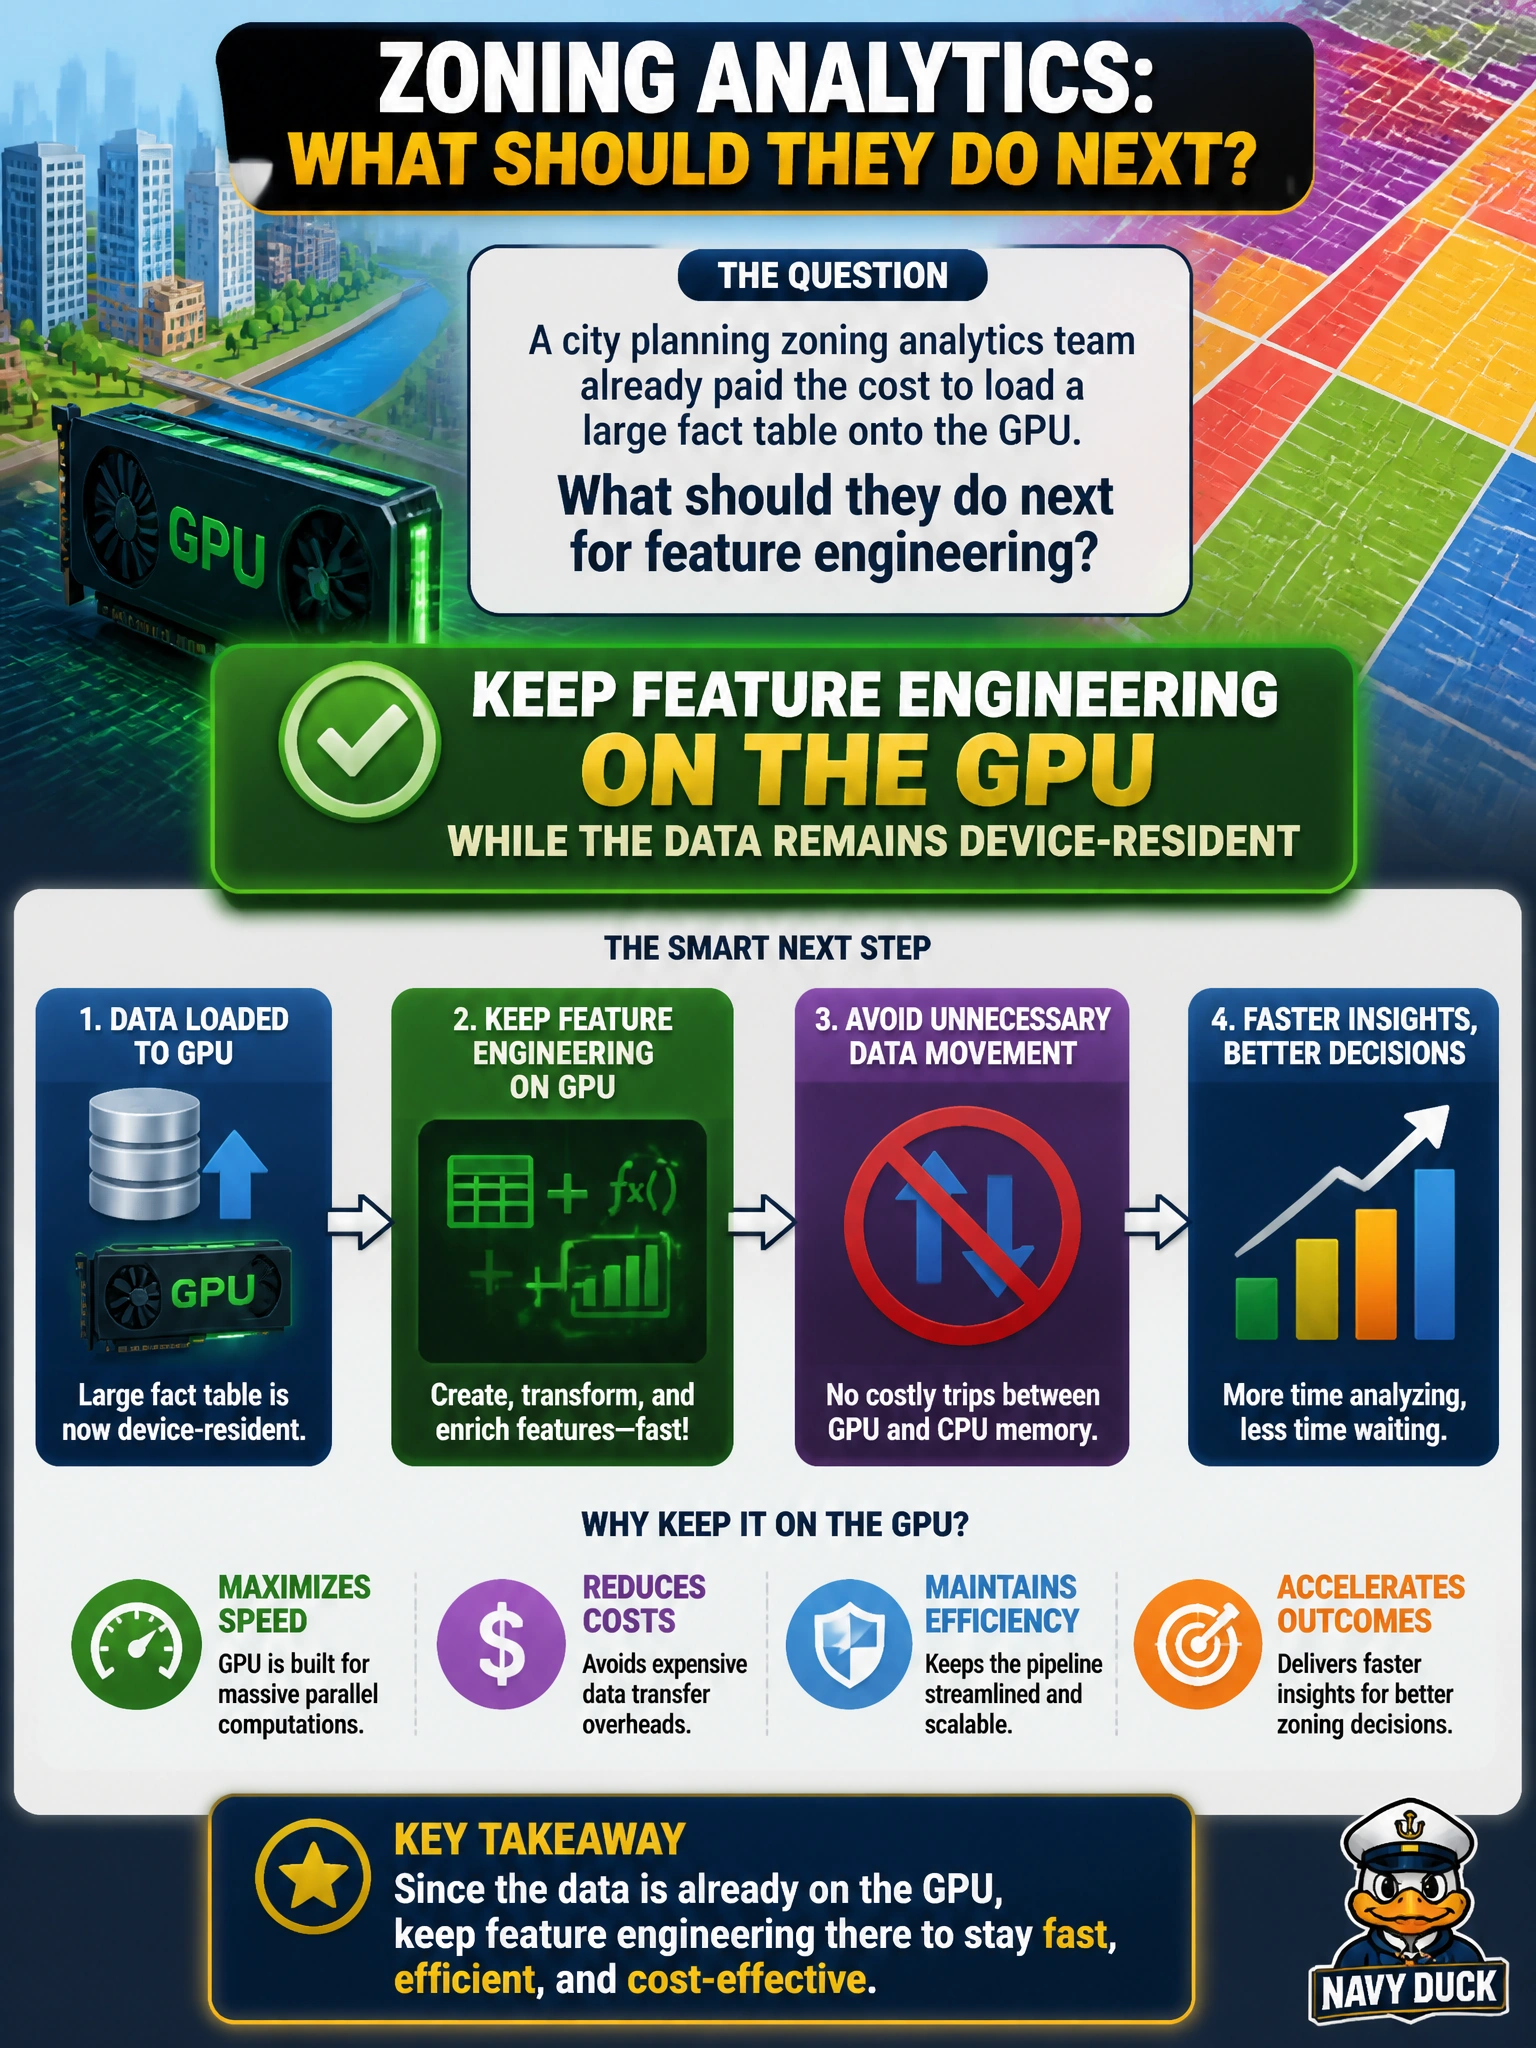
A city planning zoning analytics team already paid the cost to load a large fact table onto the GPU. What should they do next for feature engineering?
Select an answer to reveal the explanation.
Short Explanation
You already hauled the couch upstairs—do the work upstairs. Once zoning facts live on the GPU, engineer features there instead of dragging everything back to CPU. CSV round-trips each column undo the transfer you just paid for.
Full Explanation
Once a city planning zoning team has paid the cost to load a large fact table onto the GPU, feature engineering should continue on device while that data remains resident. Amortizing the upload across multiple feature steps is how accelerated pipelines win; bouncing back to CPU immediately wastes the transfer already paid. Domain 5 frames GPU residency as something to exploit across successive transforms.
Immediately copying the entire table back to CPU before any feature work discards the residency advantage and reintroduces transfer delay before value is extracted. Exporting to CSV after every column and re-ingesting for the next feature multiplies I/O and type-coercion cost absurdly. Deleting device memory and restarting from empty notebooks each feature forces repeated uploads and destroys continuity of the feature set.
Exam caveat: After an expensive GPU load, keep feature work on device. Distractors that bounce to CPU, CSV-per-column, or wipe device memory fail the residency principle.
Operational check: Load zoning facts once, run the feature-engineering sequence in cuDF (or equivalent) on GPU, validate feature digests on device, then gather only the needed feature matrix for modeling or export.