
An engineering team is preparing to train a massive, multi-billion parameter model whose weights and activation states exceed the physical VRAM capacity of a single GPU. Which distributed training techniques should they employ to overcome these memory limitations? (Select all that apply)
Select all correct answers, then click Submit.
Short Explanation
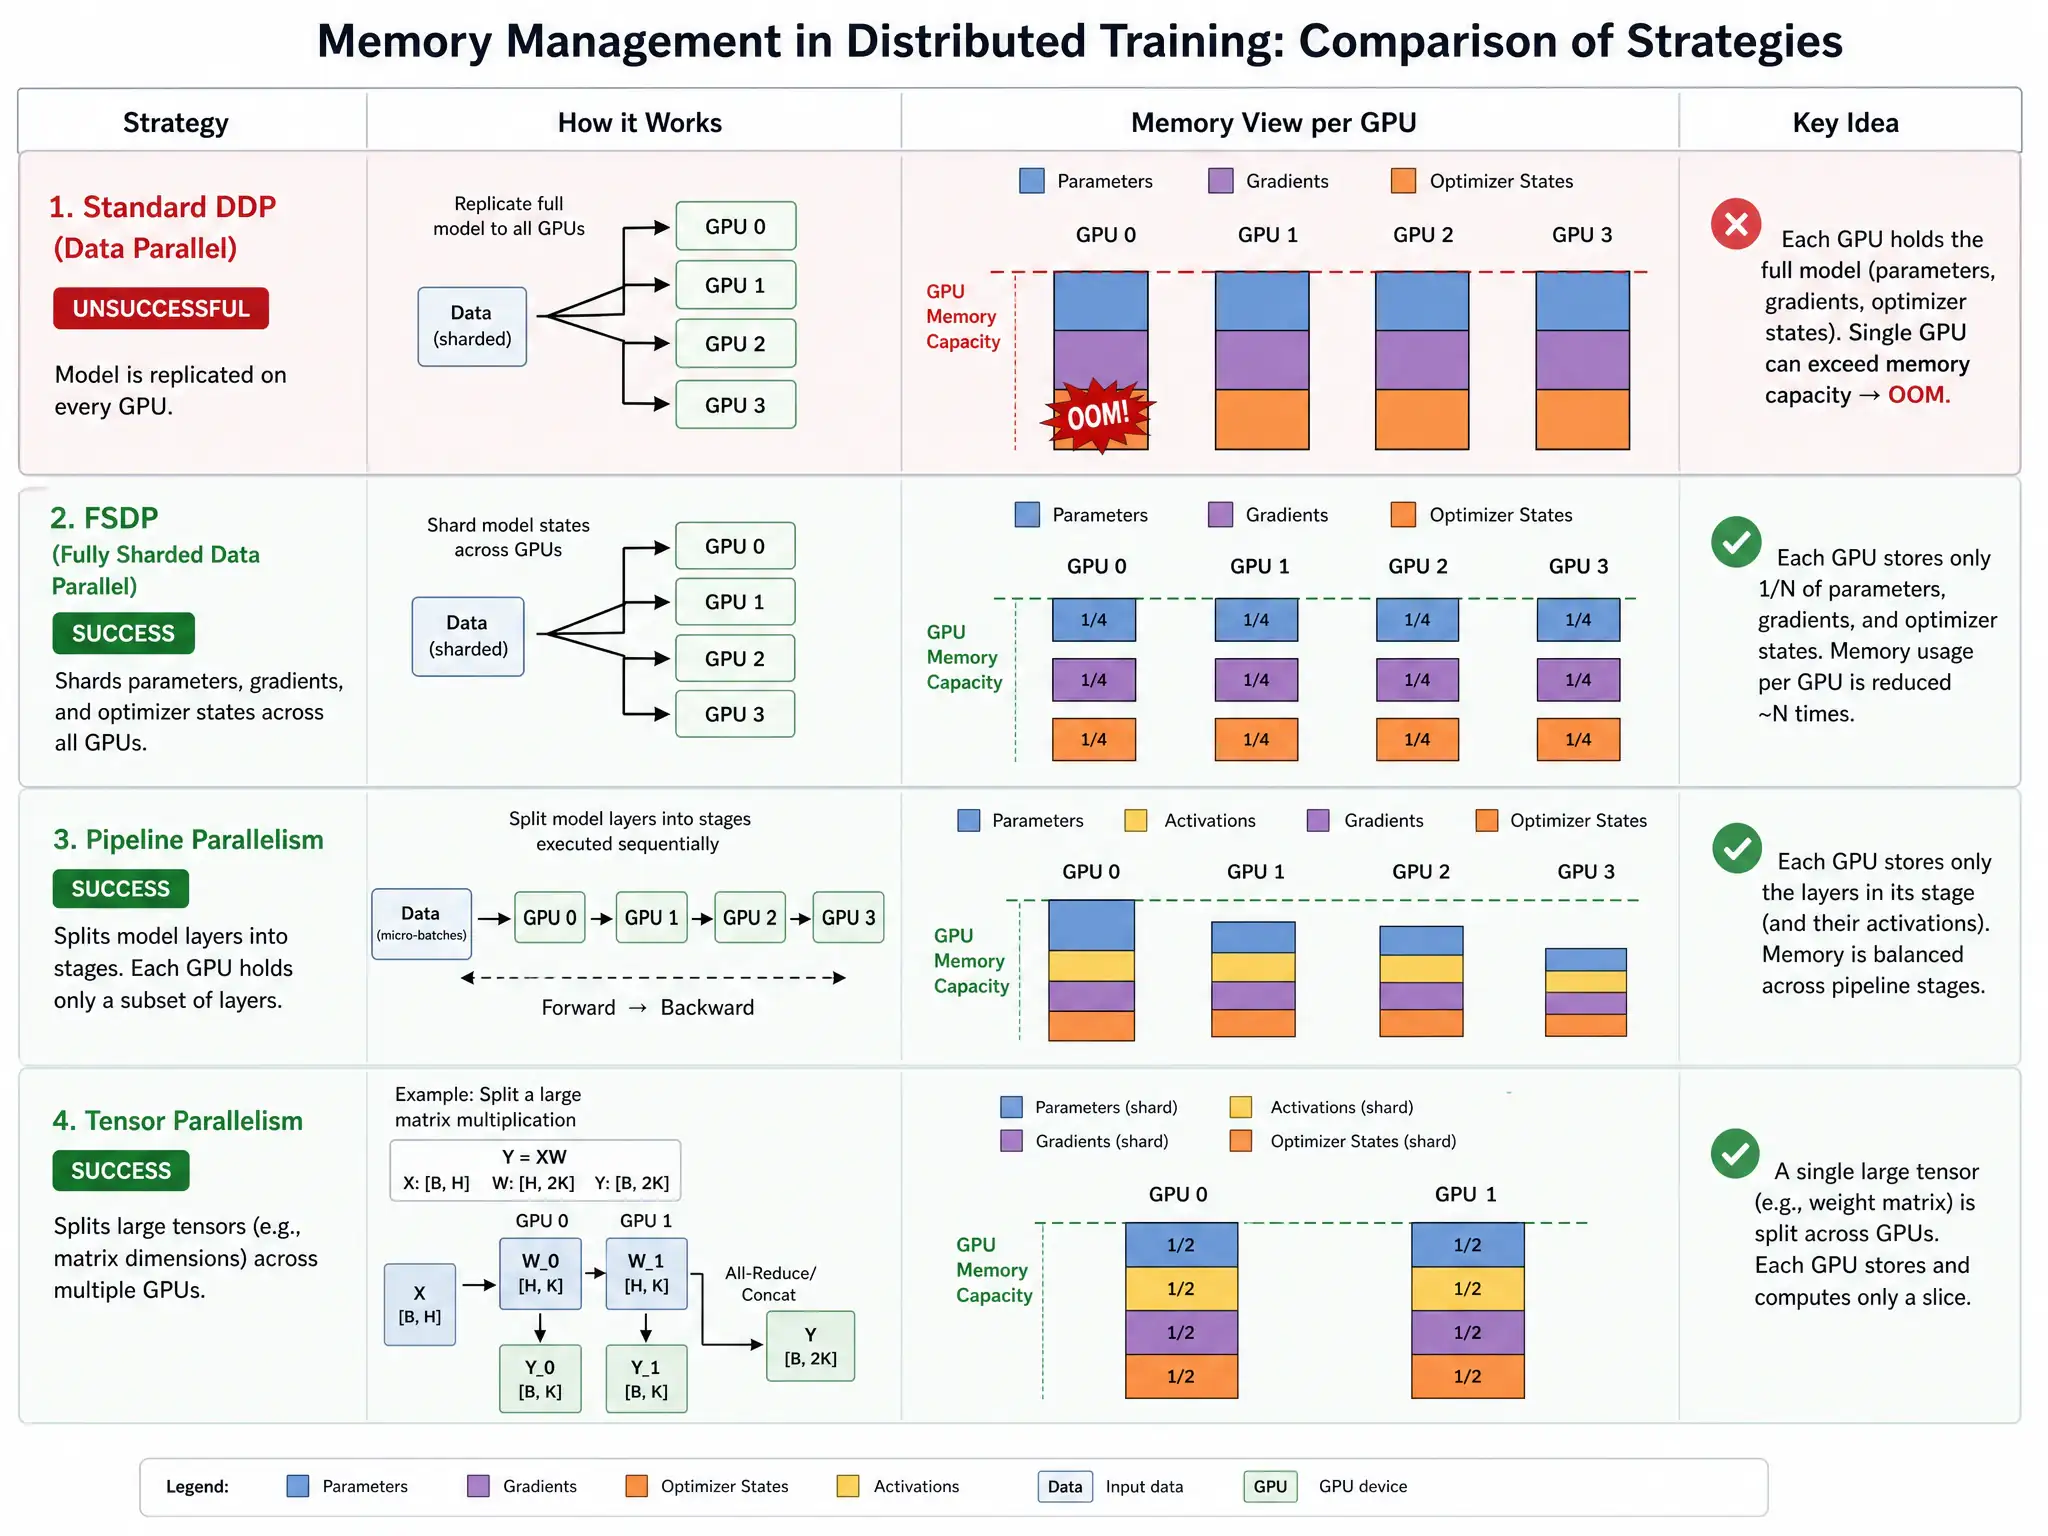
When your model is too big for one GPU, you can't just copy it to every GPU. You need to shard the model with FSDP or DeepSpeed ZeRO, or split it with pipeline and tensor parallelism so each GPU only holds part of the work.
Full Explanation
When weights and activation states exceed a single GPU's VRAM, distributed training strategies must bypass simple replication. - Fully Sharded Data Parallel (FSDP): FSDP shards the model parameters, gradients, and optimizer states across all data-parallel ranks. This dramatically reduces the memory footprint per GPU, allowing models that would otherwise cause OOM errors to be trained by gathering weights dynamically during the forward and backward passes. - DeepSpeed ZeRO: The Zero Redundancy Optimizer (ZeRO) eliminates memory redundancies in data-parallel training by partitioning optimizer states, gradients, and model parameters across GPUs (ZeRO Stage 1, 2, and 3, respectively) rather than replicating them. - Pipeline parallelism: This strategy splits the model layers chronologically/sequentially across different GPUs or nodes. For example, if a model has 80 layers, one node handles layers 1-20, another handles 21-40, and so on. This divides the memory requirements of both parameters and activation states. - Model/Tensor parallelism: This strategy parallelizes the intra-layer computations, such as the large matrix multiplications inside a Transformer's multi-head attention block, across multiple GPUs, dividing the memory required for weights and activations within a single layer.
The incorrect approaches are: - Standard Distributed Data Parallel (DDP) which replicates the entire model on each individual GPU is incorrect because standard DDP requires every participating GPU to load a complete replica of the model, optimizer states, and gradients. Therefore, if the model exceeds the memory of a single GPU, DDP cannot be used because it will immediately trigger OOM errors. - Standard data-parallel training coupled with an increase in local batch sizes is incorrect because increasing the batch size in a basic data-parallel configuration increases memory usage because more activation data must be stored during the forward pass. This worsens, rather than solves, the memory constraint.