
Which of the following statements accurately contrasts the computational operations and data processing workflows between the AI model training phase and the inference phase?
Select an answer to reveal the explanation.
Short Explanation
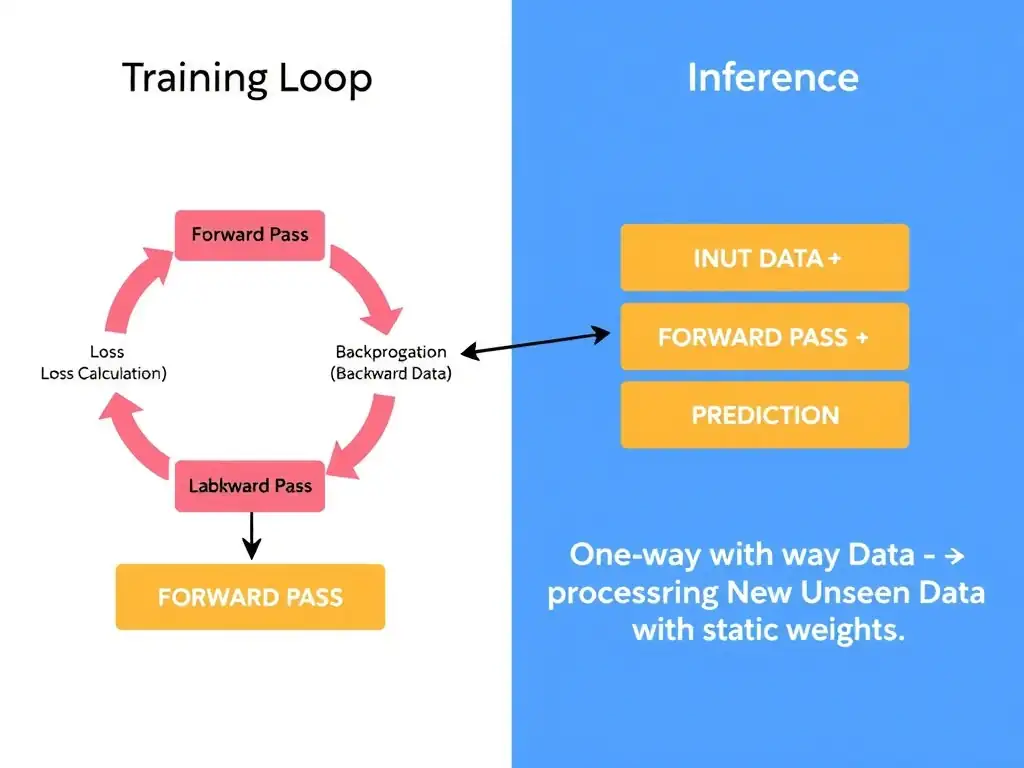
Think of training as studying for a massive exam. You run a forward pass, check the loss, then use backpropagation to update weights over and over. Inference is exam day: you run one forward pass on new data and get a prediction without updating weights.
Full Explanation
The lifecycle of a machine learning model has two distinct computational phases: training and inference. The correct statement is the one saying training involves iterative forward and backward passes, including backpropagation, over large historical datasets to adjust weights, while inference executes a single forward pass on new data to make predictions without updating weights. Training is where the model learns input-output relationships. It feeds a massive labeled historical dataset through the model. Each iteration includes a forward pass, loss computation, and a backward pass to calculate gradients and update internal weights with an optimizer. This repeats over many epochs and demands immense compute, high memory bandwidth, and fast inter-GPU communication. Inference is deployment on new, unseen data. Input goes through one forward pass to produce output. No backward pass occurs, and weights remain fixed. Without backpropagation, inference needs much less memory and compute per query, so it can run on smaller hardware or edge devices while minimizing response latency. The statement saying training uses low-latency single-batch live user data and inference uses high-throughput iterative batch historical archives is wrong because it reverses those roles. The statement saying training uses only a forward pass without changing weights and inference uses backpropagation to update parameters is wrong because it reverses the math. The statement saying training is restricted to general-purpose CPUs for precision and inference must use specialized GPUs for speed is wrong because training is usually GPU-accelerated for its intense compute, while inference can sometimes run on CPUs when latency requirements are lenient. Exam caveat: expect questions to test these differences.