
An organization is deploying a cluster of microservices for natural language processing and wants to maximize GPU and memory utilization. Why does deploying these models in containers yield higher resource efficiency than deploying them inside traditional virtual machines?
Select an answer to reveal the explanation.
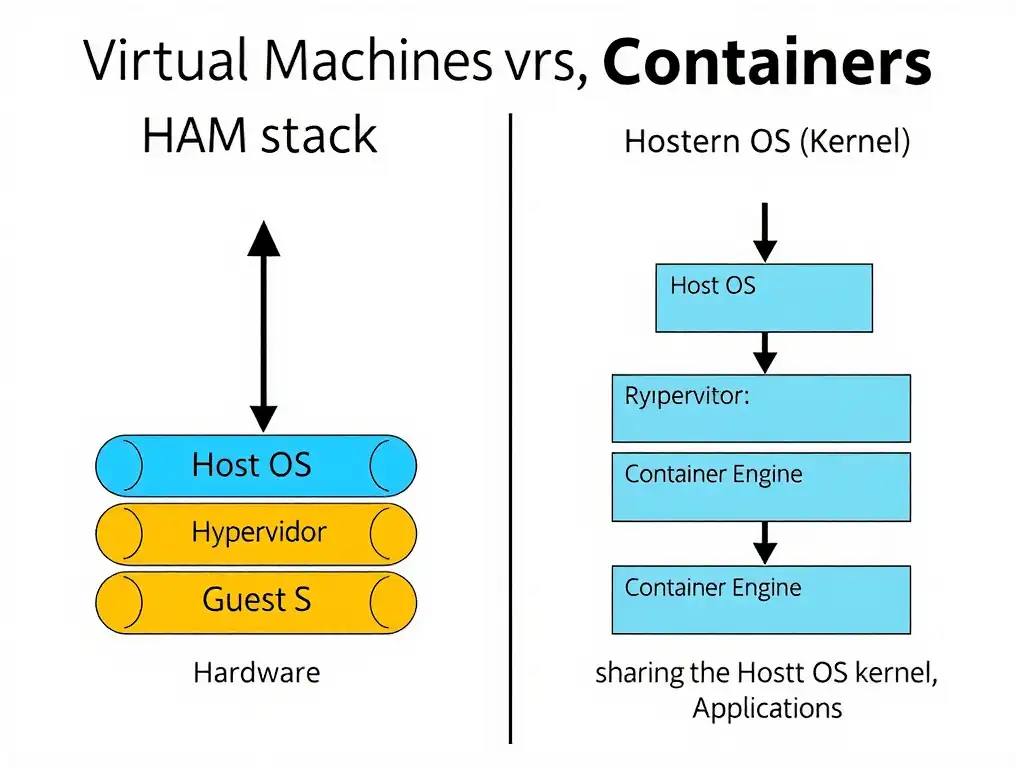
Short Explanation
Think of virtual machines as separate houses and containers as apartments sharing the host kernel. You get more NLP microservices on the same GPU server because you're not wasting RAM and CPU on a full guest OS for each one. Trust me, that shared-kernel efficiency is what maximizes utilization.
Full Explanation
Virtual machines and containers provide virtualization at different layers of the software stack. Virtual machines virtualize the underlying physical hardware. Each virtual machine includes a complete copy of a guest operating system, a virtual copy of the hardware, and the application itself. Running multiple virtual machines on a host requires running multiple independent operating systems, which introduces significant overhead in terms of CPU, memory, and storage footprints. Conversely, containers virtualize the operating system. They run directly on the host operating system's kernel, typically Linux, and share its resources. Container engines, such as Docker or containerd, isolate namespaces and control groups (cgroups), ensuring that applications run in their own environments without the overhead of booting a full guest operating system. This shared-kernel architecture dramatically reduces boot time and memory footprint of each instance, freeing critical system memory (RAM) and processor cycles for memory-intensive artificial-intelligence and machine-learning models. The correct explanation is that containers share the underlying host operating system kernel, avoiding the overhead of running a full guest operating system for each instance. The option claiming that containers run dedicated hypervisors that dynamically compress large-language-model weight parameters at the hardware layer is incorrect because containers do not feature hardware-level or runtime weight compression of models; model compression, such as quantization or pruning, is done at the software framework level, for example PyTorch or TensorRT. The option claiming that containers bypass the network stack entirely to optimize local GPU memory caching during inference is incorrect because containers still use standard networking protocols, though virtualized and namespaced, and do not bypass the network stack to optimize GPU memory caching. The option claiming that containers utilize hardware-enforced CPU partitioning to guarantee isolated GPU cores for every service is incorrect because GPU virtualization and isolation, such as NVIDIA MIG or vGPU, are handled by GPU drivers and hypervisors or container runtimes, not by hardware-enforced CPU partitioning inside the container itself.