
During distributed multi-node AI model training, how does NVIDIA GPUDirect RDMA optimize data transfers and reduce latency when GPUs on different servers exchange gradient updates?
Select an answer to reveal the explanation.
Short Explanation
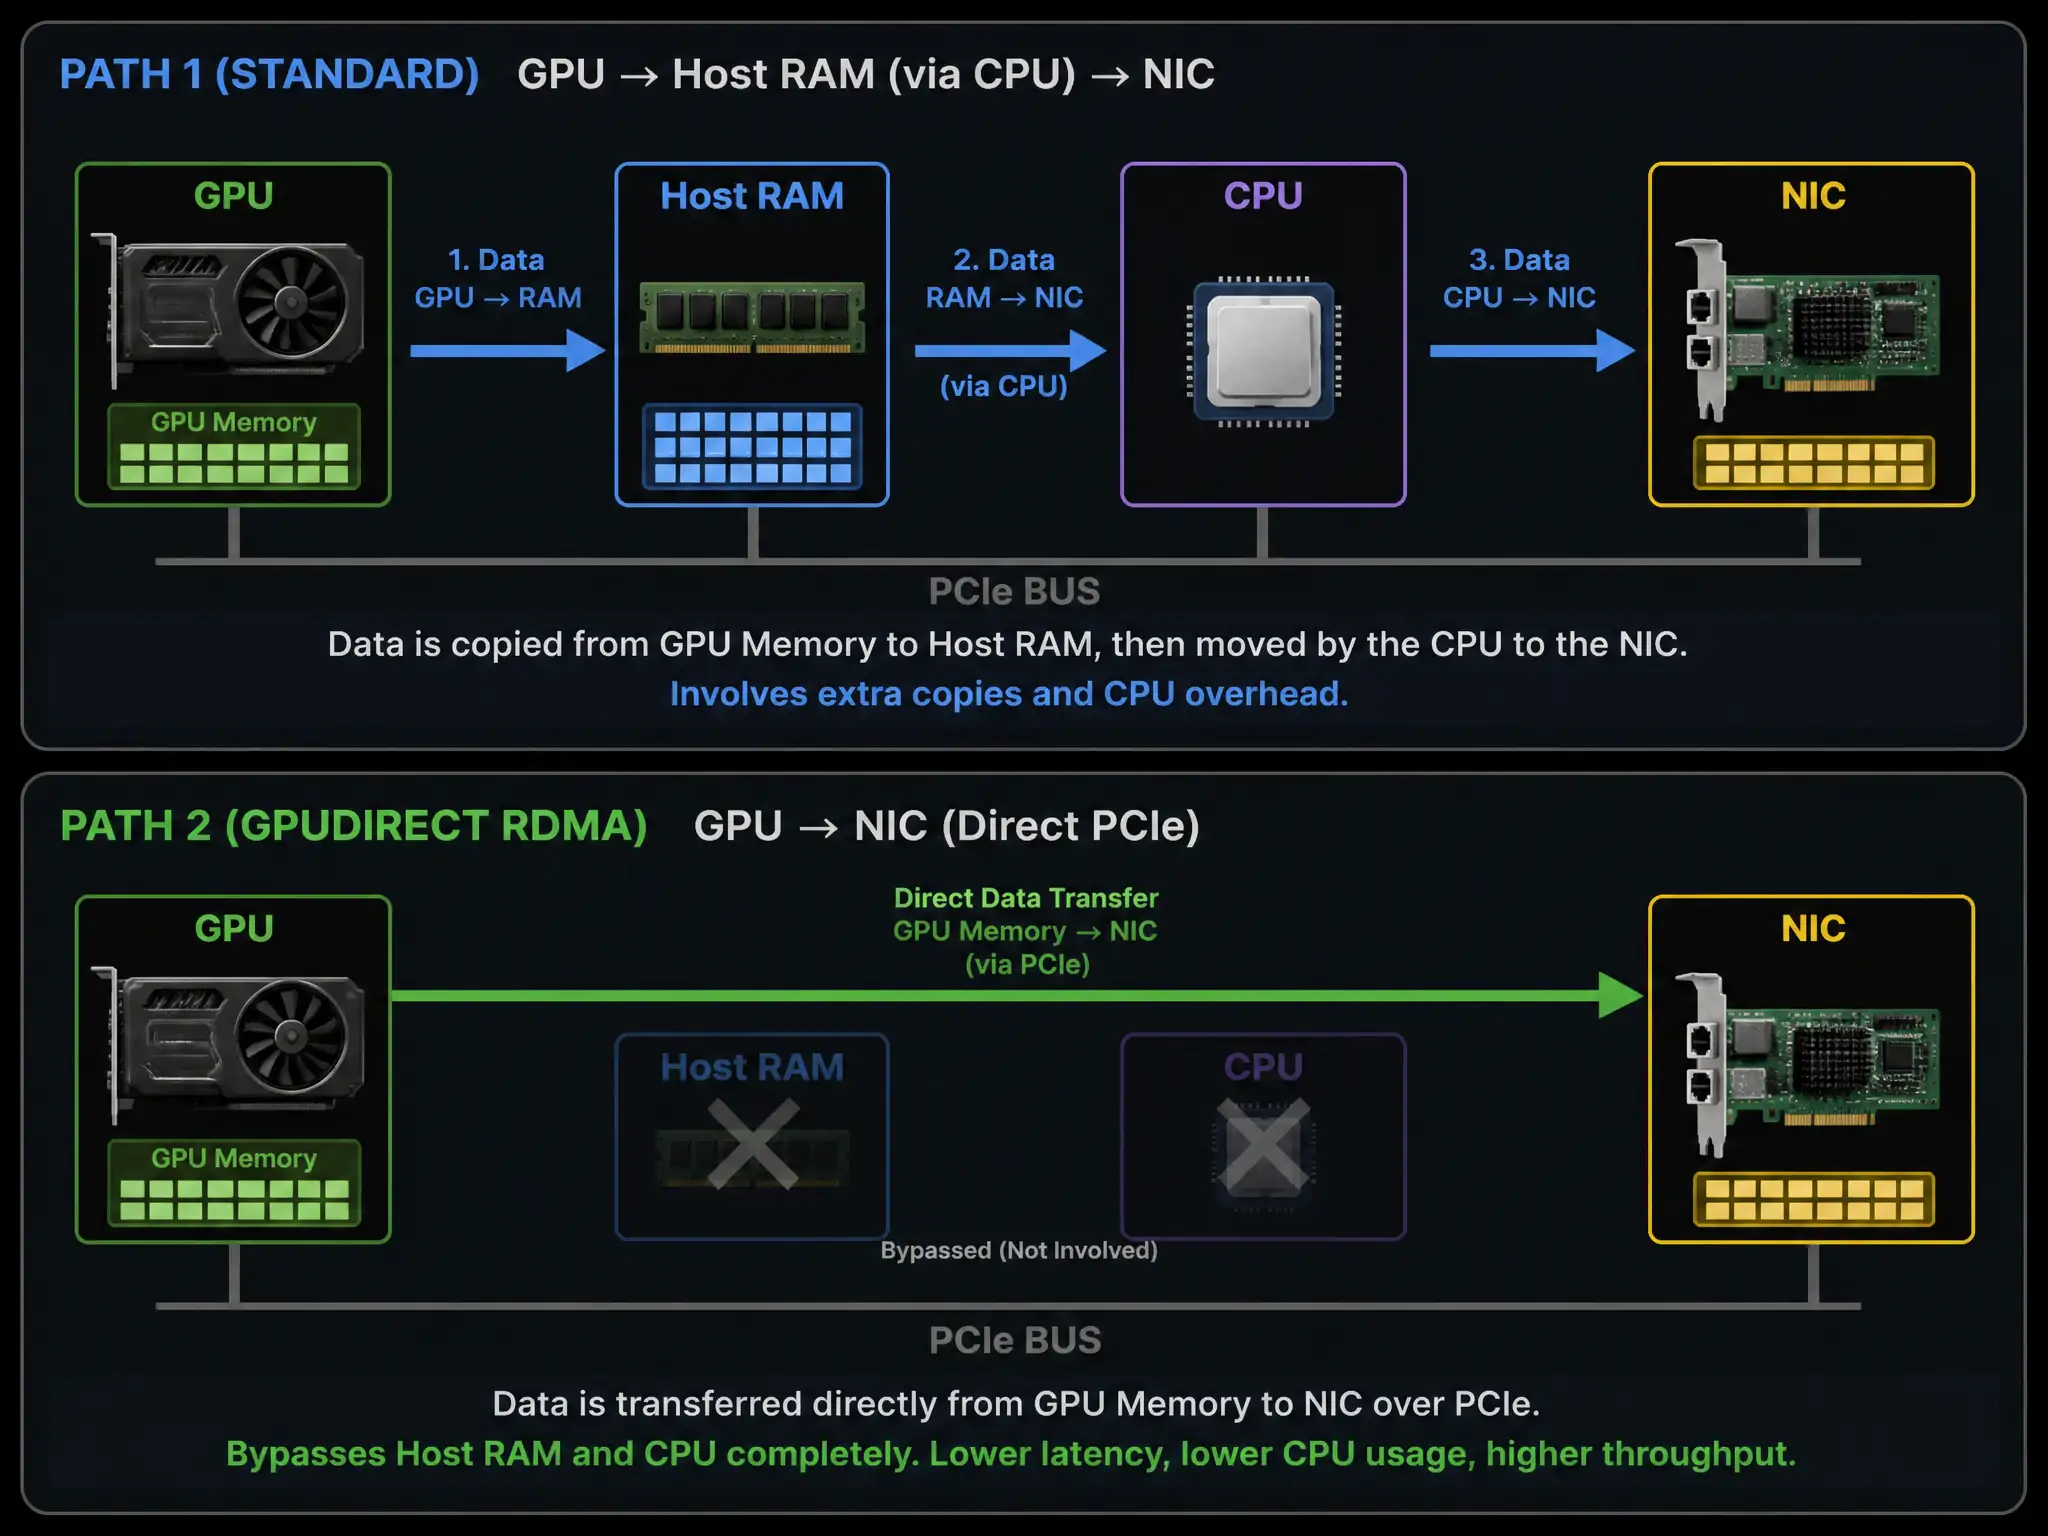
When you're training across servers, your GPUs need to exchange gradients fast. GPUDirect RDMA gives you a direct PCIe path from GPU memory to the NIC, so the data skips the host CPU and system RAM. That cuts latency and speeds up training.
Full Explanation
GPUDirect RDMA (Remote Direct Memory Access) significantly accelerates multi-node distributed deep learning workloads, such as those using MPI or NCCL. Normally, transferring data from a GPU on one node to a GPU on another node requires copying the data to host system memory, invoking the host CPU to manage the network protocol stack, sending the data over the network, and reversing the copy operations at the destination. This path introduces severe latency and memory bus congestion. The correct approach is establishing a direct PCIe path between GPU memory and the network interface card, bypassing the host CPU and system RAM. This allows a third-party PCI Express device, such as a Mellanox InfiniBand or RoCE HCA, to directly access the memory address space of an NVIDIA GPU. That eliminates intermediate system memory buffer copies and CPU overhead, enabling direct GPU-to-GPU data transfers across the network. The switch-memory caching approach is incorrect because network switches do not cache model gradients. The hardware compression approach is incorrect because GPUDirect RDMA does not natively compress data; it optimizes the physical transport path. The multi-link parameter splitting approach is incorrect because link aggregation and parameter partitioning are functions of routing protocols and model parallel frameworks, such as Megatron-LM, not GPUDirect RDMA.