
A cluster of high-density AI servers running massive transformer model training is experiencing thermal throttling. The existing hot/cold aisle containment and air handling units are running at peak capacity, but GPU junction temperatures are approaching critical levels. How can the engineering team best resolve this thermal bottleneck to sustain continuous maximum compute density?
Select an answer to reveal the explanation.
Short Explanation
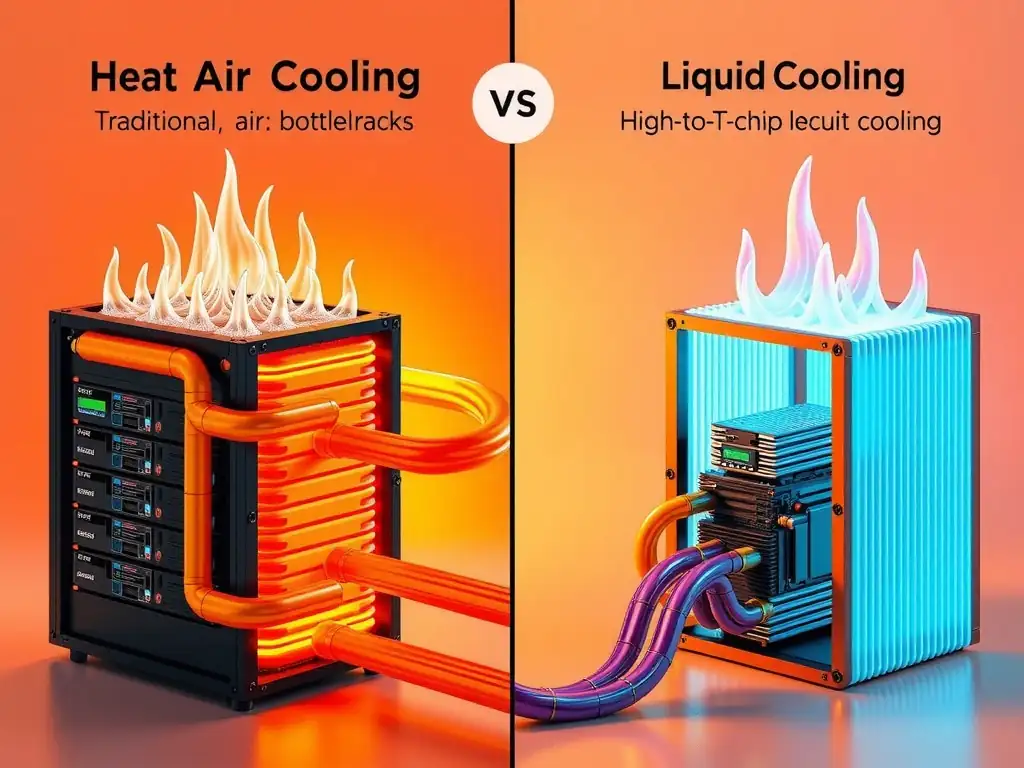
Here's the deal: deep learning training racks can pull enough power that air cooling hits a wall. You need direct-to-chip or immersion liquid cooling to move heat away from the silicon fast and keep maximum compute density running. Cranking fans or shifting workloads just dodges the thermal bottleneck instead of solving it.
Full Explanation
In modern data centers hosting high-performance AI workloads, thermal management is a critical operational constraint. High-density GPU accelerators, such as those used for training large deep learning models, generate thermal design power, or TDP, levels that exceed the dissipation capabilities of traditional air-based cooling systems. Air cooling relies on convective heat transfer, which becomes highly inefficient as power densities exceed 30 to 50 kW per rack. When GPUs operate continuously at peak capacity, thermal resistance between the silicon junction and the ambient air leads to heat accumulation. This causes the hardware to engage in thermal throttling—reducing clock speeds to protect the components—or trigger thermal shutdown, disrupting workloads and potentially causing permanent hardware degradation. Liquid cooling, either through direct-to-chip cold plate technology or immersion cooling, offers a significantly higher heat transfer coefficient and thermal conductivity compared to air. Water or specialized dielectric fluids can absorb and transport heat far more rapidly. By target-cooling the most heat-intensive racks, operators can manage temperatures at the source. This enables the infrastructure to support higher compute densities, including racks exceeding 100 kW, while maintaining optimal GPU operating temperatures and maximizing FLOPS performance. Reviewing the incorrect approaches: dynamically distributing training batch sizes across all lower-density, standard CPU compute nodes fails because deep learning training requires tight interconnects and high-speed GPU clusters; spreading the workload decreases communication efficiency and violates the architectural requirements of large-scale distributed training. Configuring workload schedulers to only execute deep learning jobs during low-ambient nighttime hours does not address the peak thermal output of active training runs and introduces unacceptable idle times for expensive hardware assets. Maximizing internal server fan speeds and lowering the data center ambient temperature setpoint is insufficient once the physical limits of air heat capacity are reached. Furthermore, high-RPM fans consume massive amounts of parasitic power, also called parasitic load, and do not resolve localized hotspot issues in high-density configurations.