
An infrastructure architect is designing the storage subsystem for an enterprise AI initiative that requires training deep learning models on petabytes of unstructured text, audio, and video files. The files reside in multiple distinct repositories, and the GPU cluster must access them with high parallel bandwidth. Which of the following architectural approaches will most effectively handle this high-capacity, distributed data ingestion? (Choose two)
Select all correct answers, then click Submit.
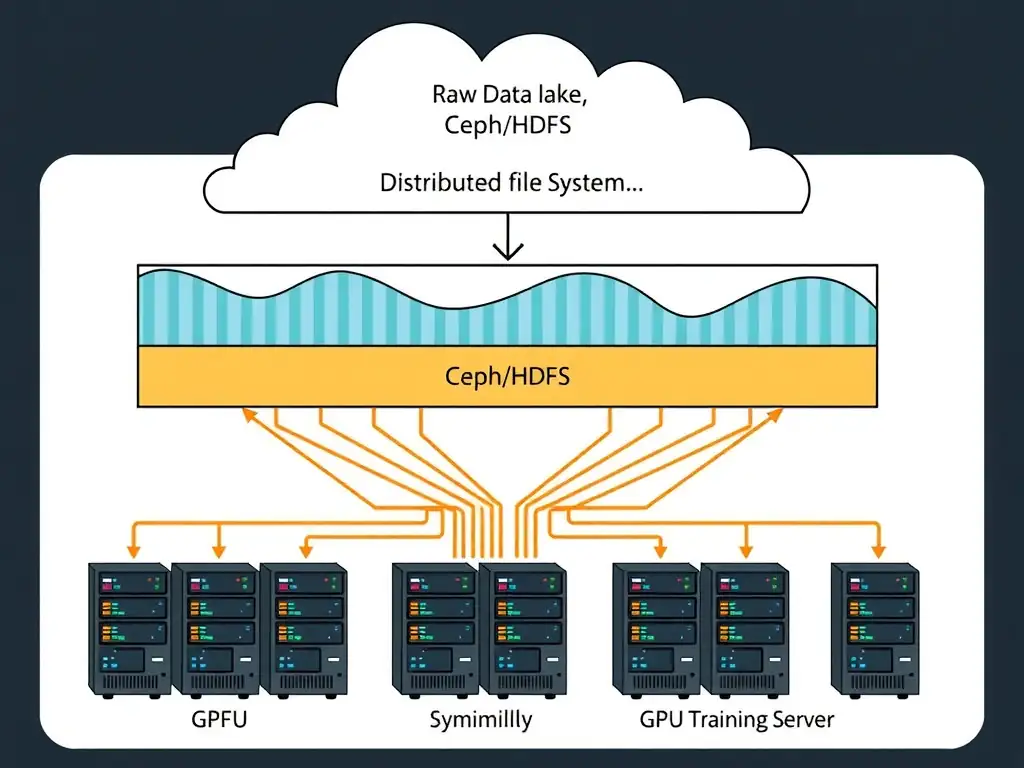
Short Explanation
If you're training models on petabytes of data, you can't store it on one local drive or route it through one compute node; that starves GPUs. Deploy a distributed file system like Ceph, Hadoop HDFS, or Lustre so the cluster reads in parallel, and use a data lake to keep raw text, audio, and video in native formats at scale. That keeps your GPUs fed.
Full Explanation
Large-scale AI initiatives require storage architectures that can scale both capacity and I/O performance dynamically. Training deep learning models involves streaming large datasets across many GPU-equipped compute nodes concurrently, requiring high parallel read throughput.
- Distributed file systems such as Ceph, Hadoop HDFS, or Lustre: A distributed file system distributes data across multiple physical storage servers while presenting a unified namespace. This allows parallel access to data, where multiple compute nodes can read parts of the dataset simultaneously from different storage targets. This prevents network and disk bottlenecking, which is critical when scaling deep learning workloads across multiple GPU nodes.
- Data lake architecture: A data lake is a centralized repository that allows you to store structured, semi-structured, and unstructured data at scale in its raw, native format. Since AI workloads require diverse data types such as images, videos, text, and sensor logs that are processed using different pipelines, a data lake provides the flexibility to ingest and store raw data without predefined schemas. Data can then be processed or filtered on demand by different training or inference frameworks.
The alternative storage approaches are sub-optimal:
- Consolidating all storage into a single monolithic, local hardware drive attached to a master controller node is incorrect because it introduces a severe performance bottleneck and a single point of failure. It lacks the horizontal scalability required for petabyte-scale workloads.
- Restricting read/write operations to a single compute node to avoid networking bottlenecks is incorrect because it eliminates the ability to perform distributed, multi-node training, such as data-parallel training across multiple DGX nodes.
- Applying aggressive compression algorithms to all raw files, requiring models to decompress data on the fly during training is incorrect because while compression saves storage space, performing on-the-fly decompression during training introduces significant CPU processing overhead. This CPU bottleneck can slow down data pipelines and leave GPUs underutilized.
Therefore, the distributed file system approach and the data lake architecture are the correct architectural choices.