
A financial institution wants to detect credit card fraud using a dataset of 50 million historical transactions. Since fraud is extremely rare, the dataset is heavily skewed. The engineering team has access to an enterprise GPU cluster. How should they combine dataset preprocessing and GPU acceleration to train an accurate classifier in a reasonable time frame?
Select an answer to reveal the explanation.
Short Explanation
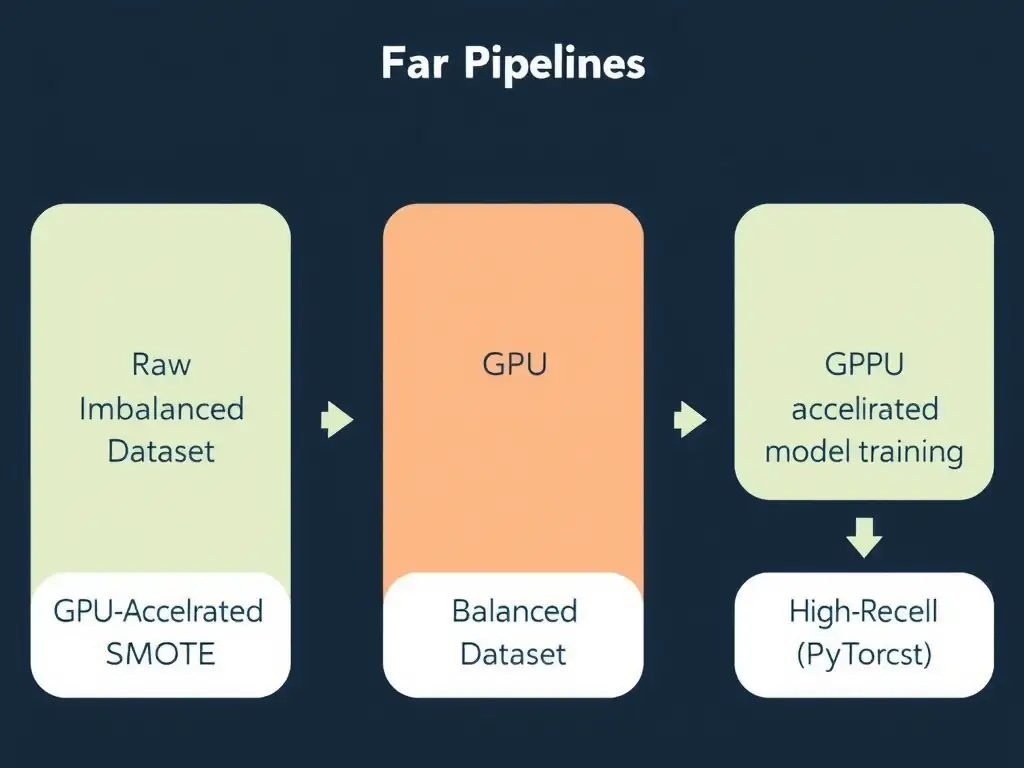
You've got a needle-in-a-haystack fraud problem, so you need to balance the rare fraud class before training. With 50 million transactions, use a GPU-accelerated SMOTE implementation to generate synthetic fraud samples fast, then train on the balanced data. That fixes the bias and uses the GPU cluster to finish in a reasonable time.
Full Explanation
To successfully train a machine learning model on large, imbalanced datasets (such as 50 million financial transactions with rare fraud instances), two main challenges must be addressed: training bias due to class imbalance, and computational scaling due to data volume. Using Synthetic Minority Over-sampling Technique (SMOTE) addresses the training bias by generating synthetic examples of the minority class (fraud) along the line segments joining k-nearest neighbors of the minority class. However, running SMOTE and training models on millions of records is computationally expensive. Leveraging GPU-accelerated SMOTE (such as the implementation in the RAPIDS cuML library) utilizes parallel GPU threads to calculate nearest neighbors and generate synthetic samples orders of magnitude faster than CPU-based implementations. Following this with a GPU-accelerated classifier (like XGBoost or a Deep Neural Network) ensures the entire pipeline runs efficiently. The downsampling approach is poor because downsampling to match the minority class means discarding 99.9% of your data (e.g., throwing away millions of legitimate transactions), which strips the model of valuable patterns. Training on CPU also fails to leverage the available GPU cluster. The raw-data logistic regression approach does not address the class imbalance, lacks the capacity to model complex non-linear fraud patterns, and runs slowly on a single CPU thread. The raw-data XGBoost approach leverages GPU acceleration to train quickly, but because it doesn't address the severe class imbalance, the resulting model will still have very low sensitivity (recall) for fraud detection, misclassifying most fraud events as legitimate.