
You are preparing a massive, multi-dimensional dataset containing millions of user behavioral logs for a deep learning model. The raw dataset has hundreds of features, making it highly complex and prone to the curse of dimensionality. You want to apply unsupervised data mining techniques to identify natural clusters of user profiles and reduce the feature space without losing critical variance. Which two techniques should you select to achieve these goals? (Select two)
Select all correct answers, then click Submit.
Short Explanation
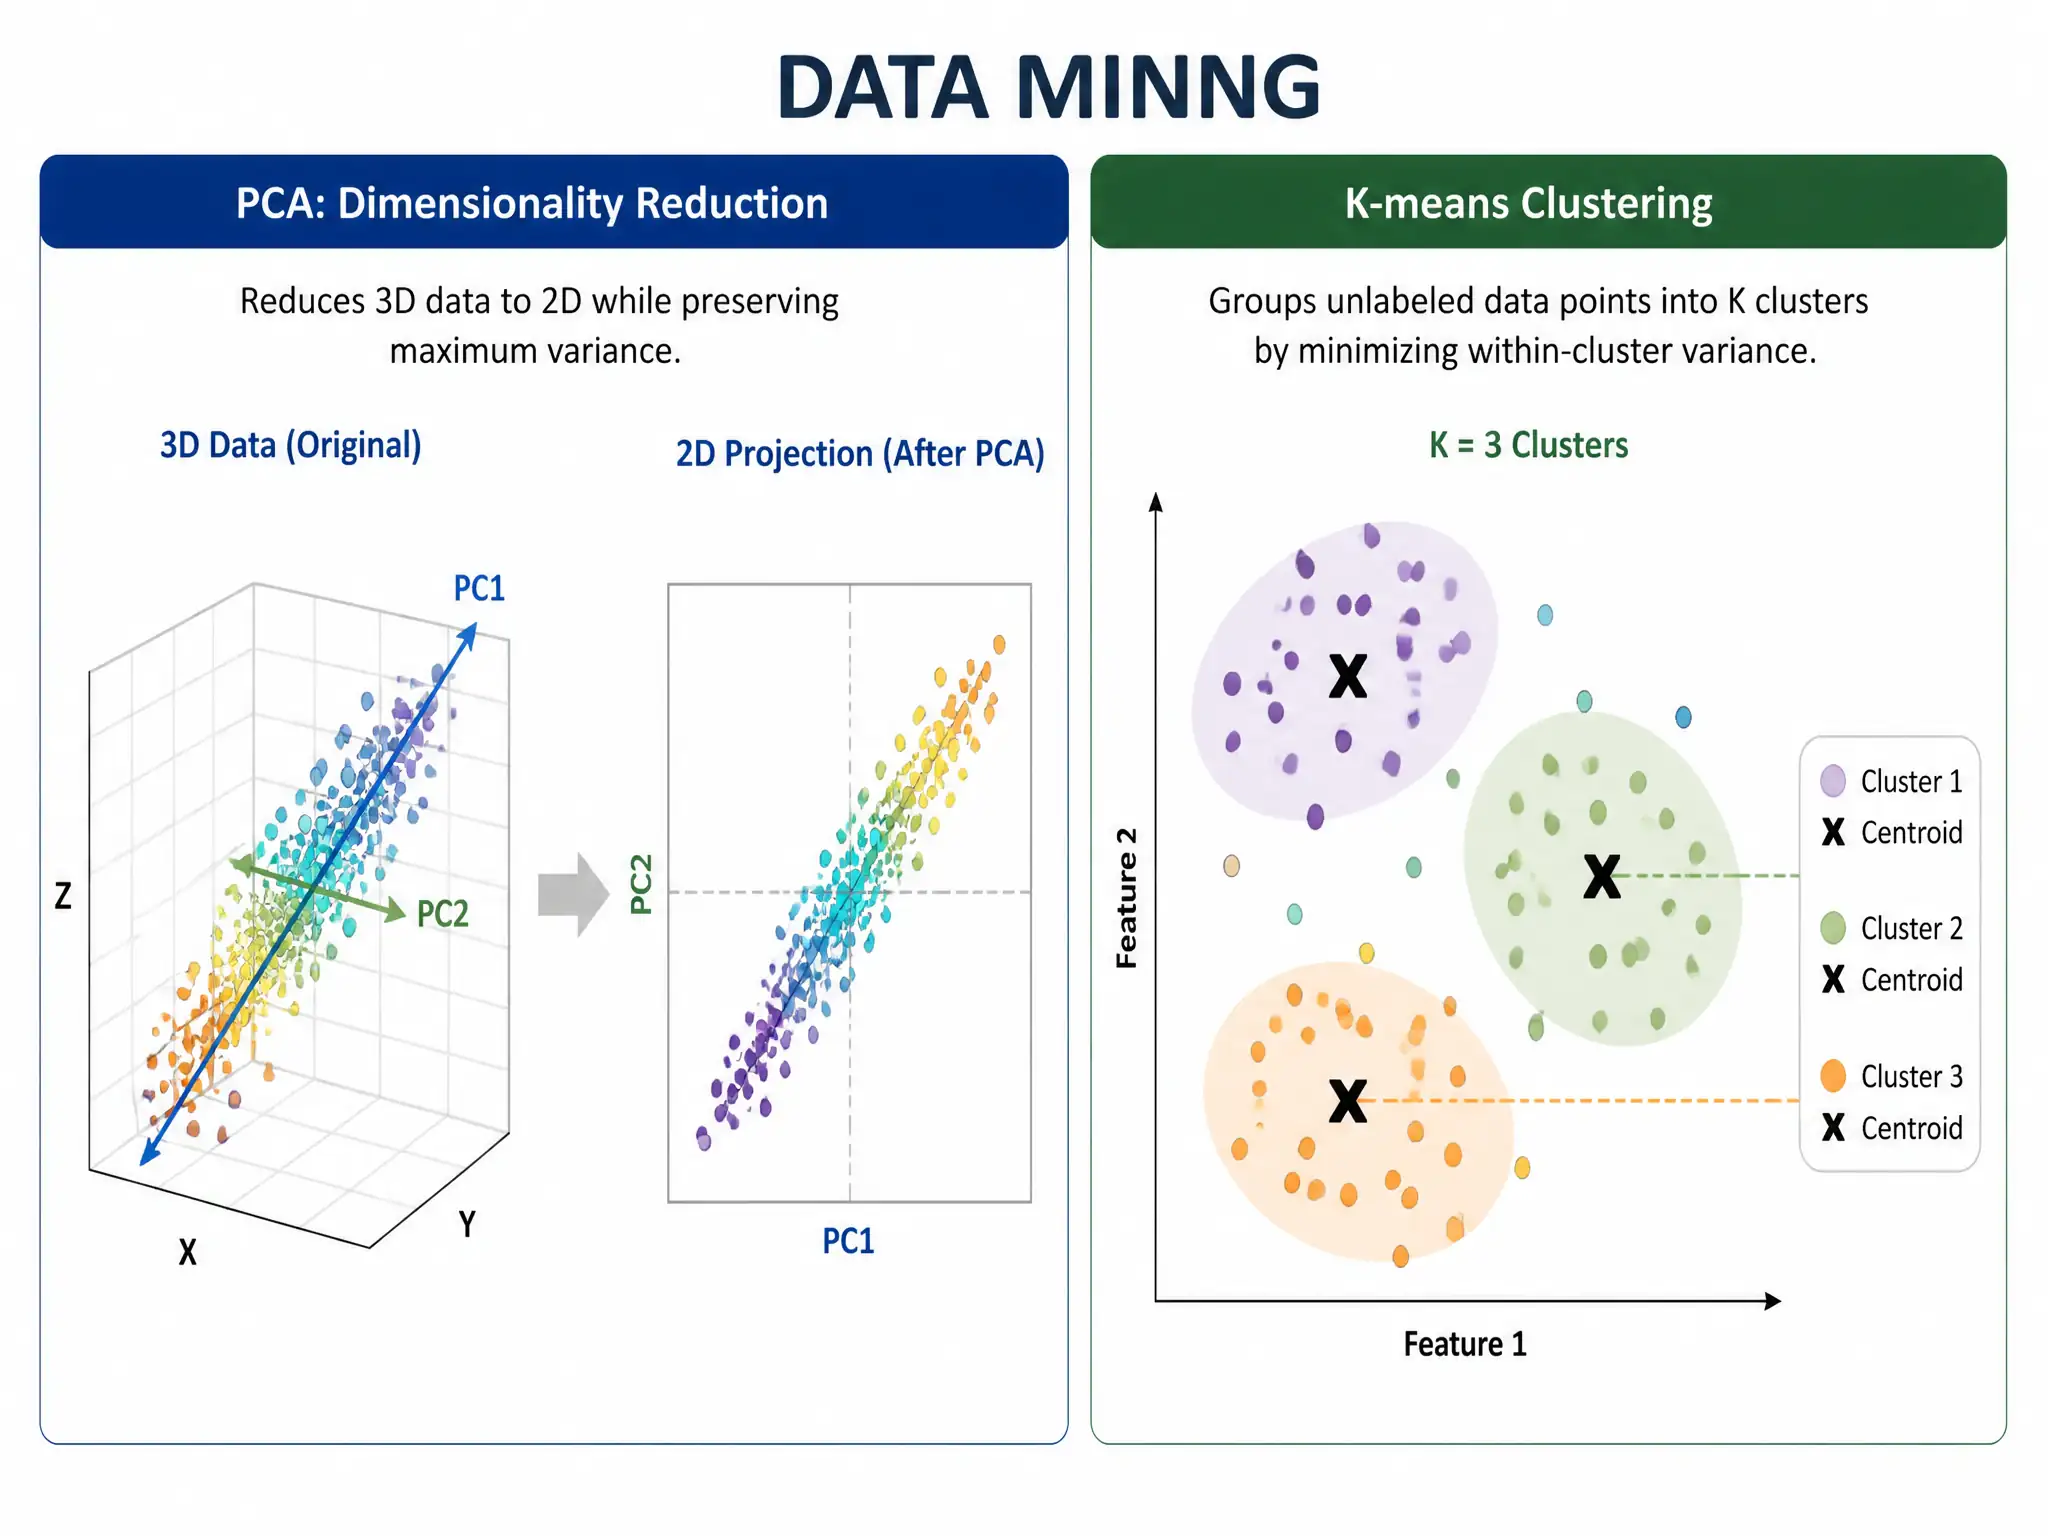
You need PCA to collapse hundreds of correlated features into the components that preserve the most variance. Then use K-means clustering to group similar user logs into natural clusters before training. That cuts dimensionality and reveals structure without memorizing noise.
Full Explanation
Preprocessing high-dimensional, large-scale datasets is a critical phase in machine learning pipelines. Principal Component Analysis (PCA) and K-means clustering are two fundamental unsupervised data mining techniques used to discover underlying patterns. PCA is a dimensionality reduction technique that transforms a set of correlated features into a smaller set of uncorrelated variables called principal components. By projecting the dataset onto the directions of maximum variance, PCA reduces the feature space complexity, addressing the curse of dimensionality, while retaining most of the essential information. K-means clustering is an unsupervised grouping algorithm that partitions data points into a fixed number of clusters based on feature similarity using distance-based metrics. Together, these techniques help identify natural groupings within a dataset and simplify feature sets, facilitating faster and more accurate model training.
The wrong choices are excluded because they do not perform unsupervised preprocessing or cluster discovery. The choice to implement dropout layers across the neural network is wrong because dropout is a regularization technique used during neural network training to prevent overfitting by randomly disabling nodes, but it does not analyze or preprocess raw datasets. The choice to utilize flat files for unstructured log storage is wrong because flat files are a storage format decision, such as comma-separated or raw text, and do not perform data mining or pattern discovery. The choice to intentionally overfit the model to local noise is wrong because overfitting is an undesirable modeling state where a neural network memorizes noise, which degrades generalizability, and it is not a data mining technique. The choice describing a regularization technique used during neural network training to prevent overfitting by randomly disabling nodes is wrong for the same reason: it does not analyze or preprocess raw datasets. The choice describing a storage format decision, like comma-separated or raw text, is wrong because it does not perform data mining or pattern discovery. The choice describing an undesirable modeling state where a neural network memorizes noise is wrong because it degrades generalizability and is not a data mining technique.