
You are deploying a computer vision pipeline that performs real-time object detection on dozens of live video feeds. Because the density of objects and frame rates vary wildly across the different cameras, static mapping of feeds to specific GPUs leads to some GPUs running hot and dropping frames, while others sit mostly idle. Which of the following distribution strategies will achieve the lowest overall latency and maintain balanced resource usage?
Select an answer to reveal the explanation.
Short Explanation
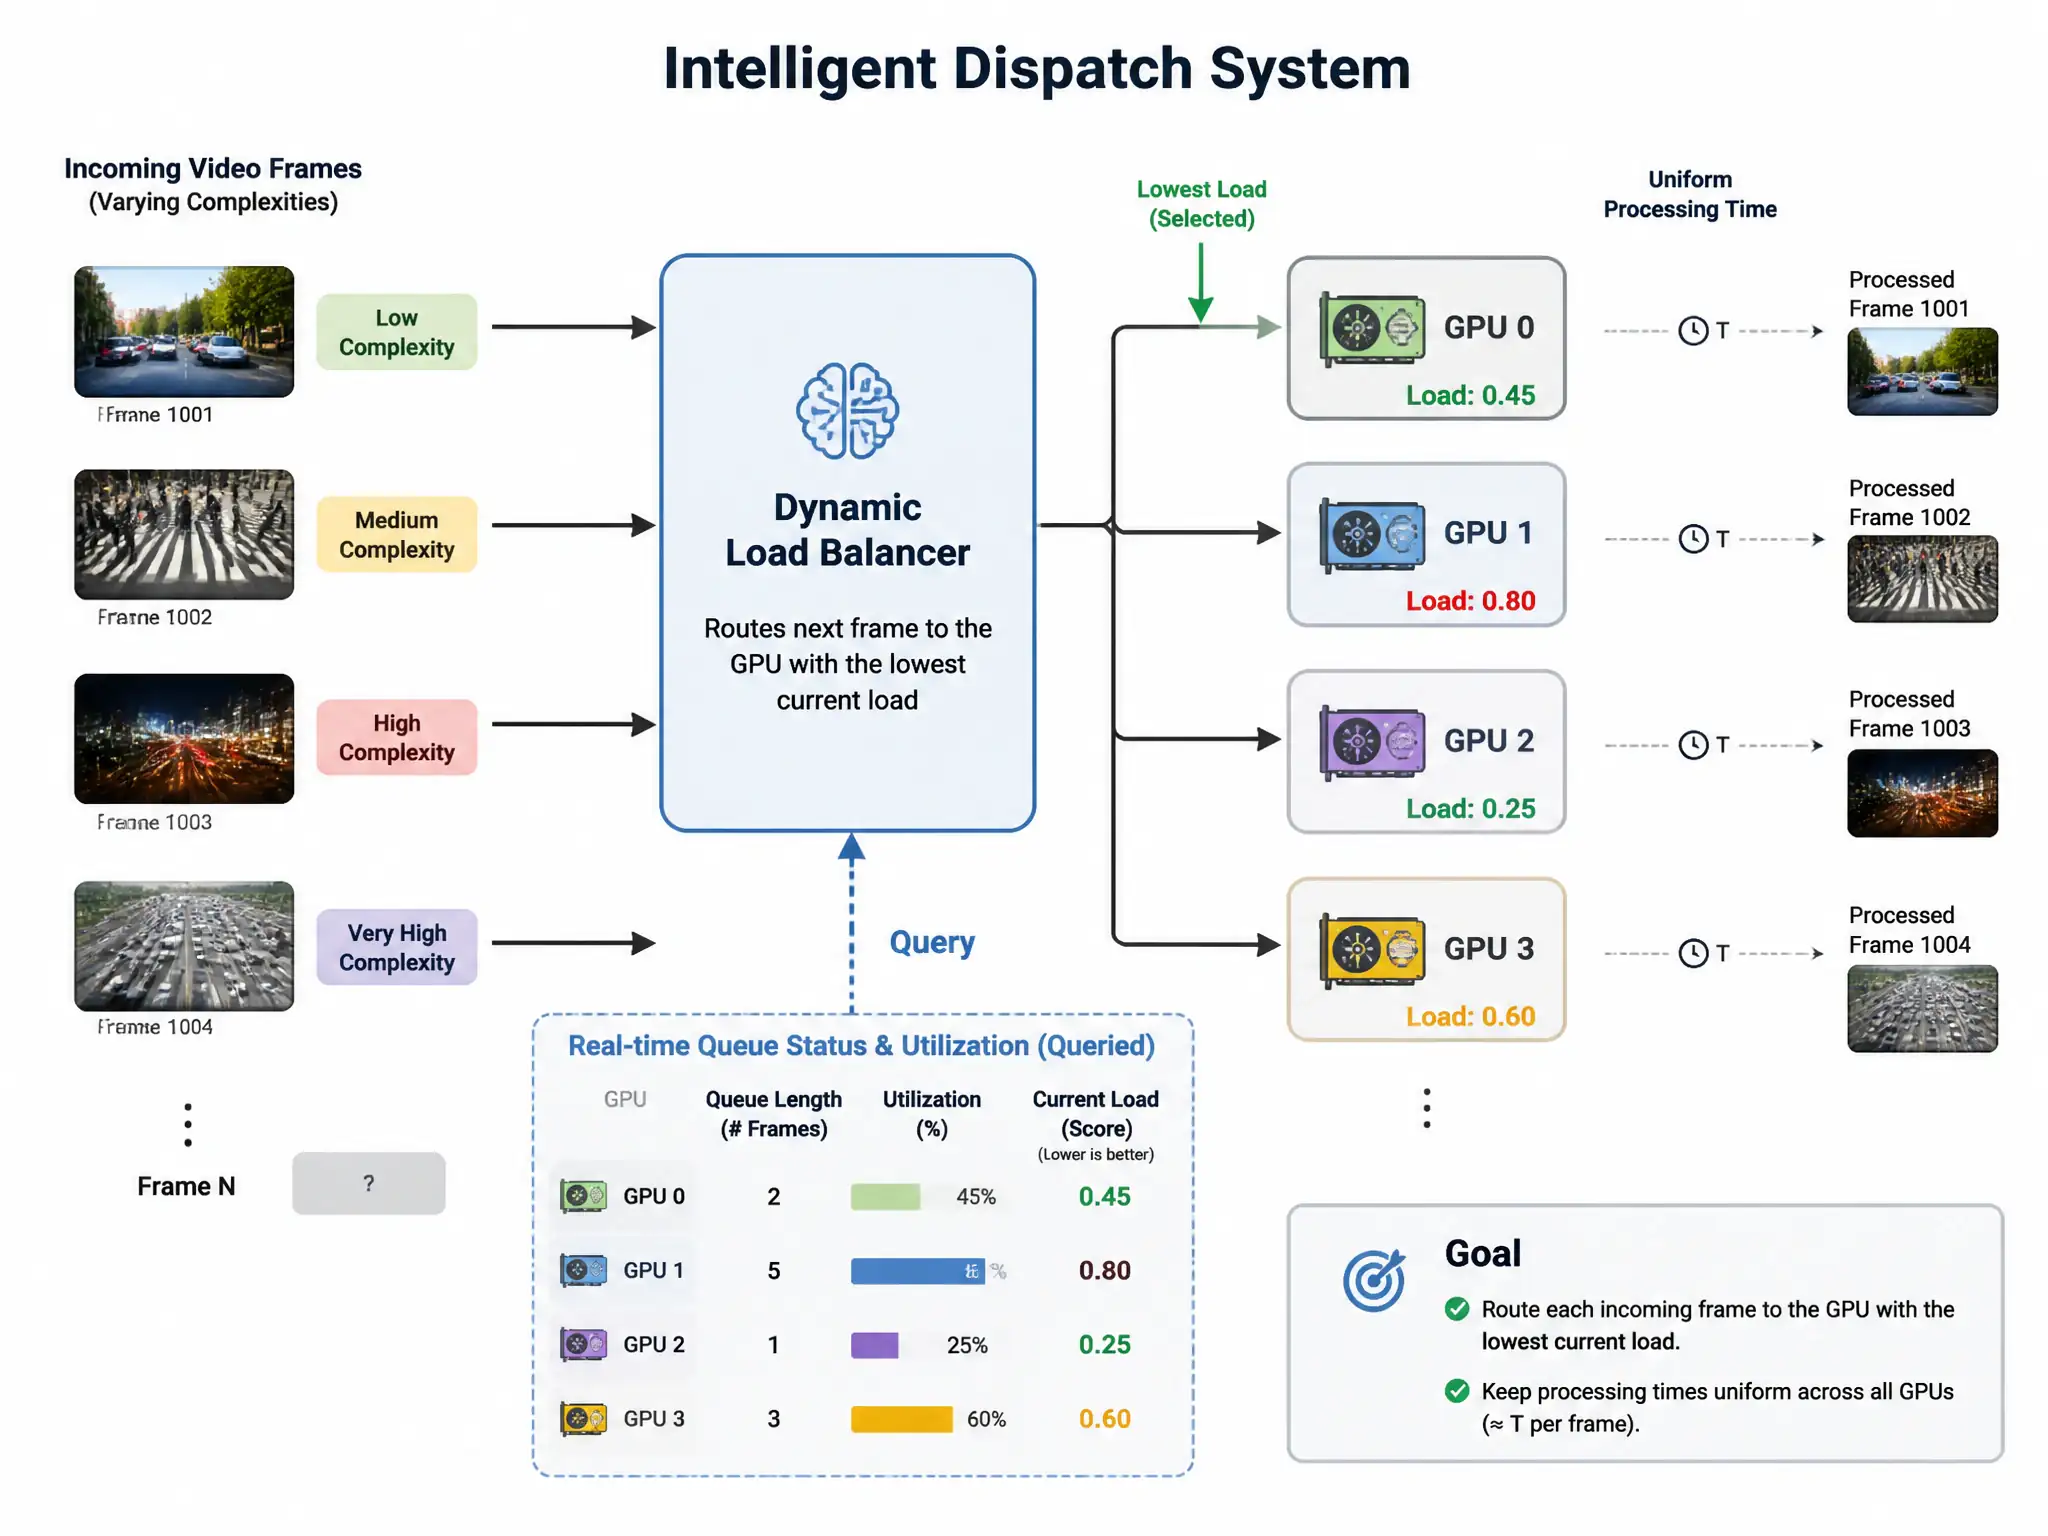
If some GPUs are pegged while others idle, static or blind scheduling is the problem. You need a dynamic load-balancing dispatcher that checks each GPU's queue length and active utilization before sending work, so frames go to the card with breathing room. Keep it dynamic, and your frame drops go away.
Full Explanation
Real-time inference workloads, such as multi-stream video analytics, are highly dynamic and variable. The time required to process a video frame depends heavily on the content, such as the number of objects to detect, and stream configurations. If workloads are assigned statically or using simple round-robin routing, it is common to experience temporary load imbalances where one GPU becomes overloaded while others remain underutilized. Implementing a dynamic load balancer resolves this by monitoring the real-time execution status of the GPU cluster, including current compute utilization and the number of queued inference tasks. It then dynamically schedules new inference requests to the GPU with the lowest load or shortest queue, ensuring consistent processing latency and maximizing overall hardware efficiency. Regarding the incorrect choices: a round-robin scheduler that distributes frames sequentially regardless of queue length operates blindly without regard to active queue lengths or processing times, meaning it can easily steer heavy tasks to an already congested GPU. Routing all frames to a centralized CPU buffer with fixed polling intervals introduces artificial latency and host bus bottlenecks, which degrades real-time responsiveness. Binding high-resolution streams to GPUs based solely on the lowest thermal signature is an indirect and lagging metric that does not reflect real-time queue depth or compute utilization, making it an ineffective way to manage scheduling.