
A bank is building an AI-powered credit card fraud prevention system that must analyze transactions within milliseconds to block fraudulent charges. At the same time, the system needs to retrain its models daily using terabytes of historical transaction records. Which architectural design is best suited to satisfy both requirements?
Select an answer to reveal the explanation.
Short Explanation
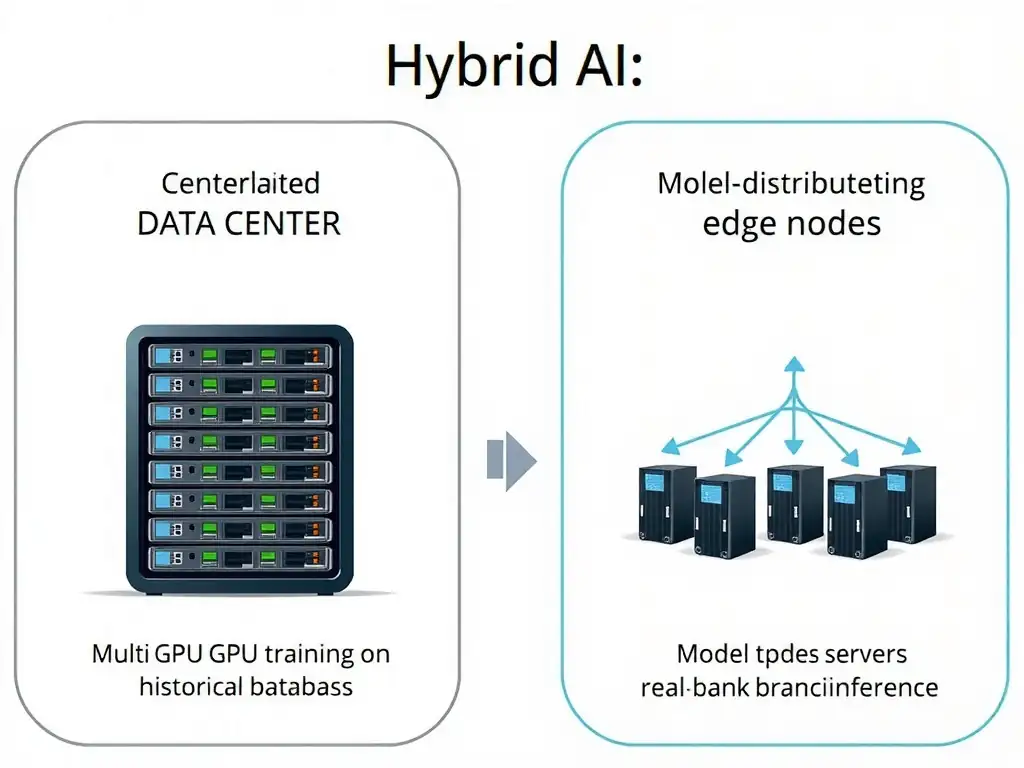
Here's the deal: you can't train a massive fraud detection model on the same tiny device that's supposed to authorize a credit card transaction in under 50 milliseconds. That's like trying to rebuild a car engine while you're driving it down the highway! Use a heavy-duty, multi-GPU cluster back in the datacenter to crunch terabytes of historical data and train the model, then push that lightweight, optimized model out to the edge so it can score swipes instantly without waiting for a long roundtrip network delay.
Full Explanation
Designing enterprise AI systems often involves separating training and inference workloads because they have vastly different compute, memory, and latency profiles. Model training is throughput-bound, requiring huge amounts of memory and floating-point computation to process massive historical datasets. Inference is latency-bound, requiring fast response times to act on live data. In this banking scenario, transaction authorization must occur within milliseconds. Relying on a centralized cluster for both training and inference introduces network latency bottlenecks and resource contention. A single-node GPU server configured to handle both model training and live transaction processing sequentially forces throughput-bound training and latency-bound inference to compete for the same resources, and sequential operation prevents the millisecond response needed for live authorization. An edge-only deployment using low-power ARM microprocessors to handle both continuous retraining and transaction scoring lacks the computational capacity required to retrain deep learning models on terabytes of daily transaction data. A centralized CPU-only server farm that processes batches of transactions uploaded to cloud storage every hour also fails because hourly batch processing cannot meet millisecond authorization, and centralizing both workloads introduces network latency bottlenecks and resource contention. The optimal solution is a hybrid architecture utilizing high-performance multi-GPU server clusters for training, paired with low-latency edge deployment for real-time inference. Centrally located, high-throughput multi-GPU servers train the model on accumulated historical data. Once trained, the optimized model weights are deployed to local edge servers or devices near the transaction endpoints to perform low-latency, real-time inference. This separation ensures that the model can be continuously updated without impacting the strict response times required for transaction processing.