
When designing hardware infrastructure for enterprise AI, system architects must distinguish between the resources needed to build models versus those needed to run them. What is a primary difference in the hardware demands between model training and model inference?
Select an answer to reveal the explanation.
Short Explanation
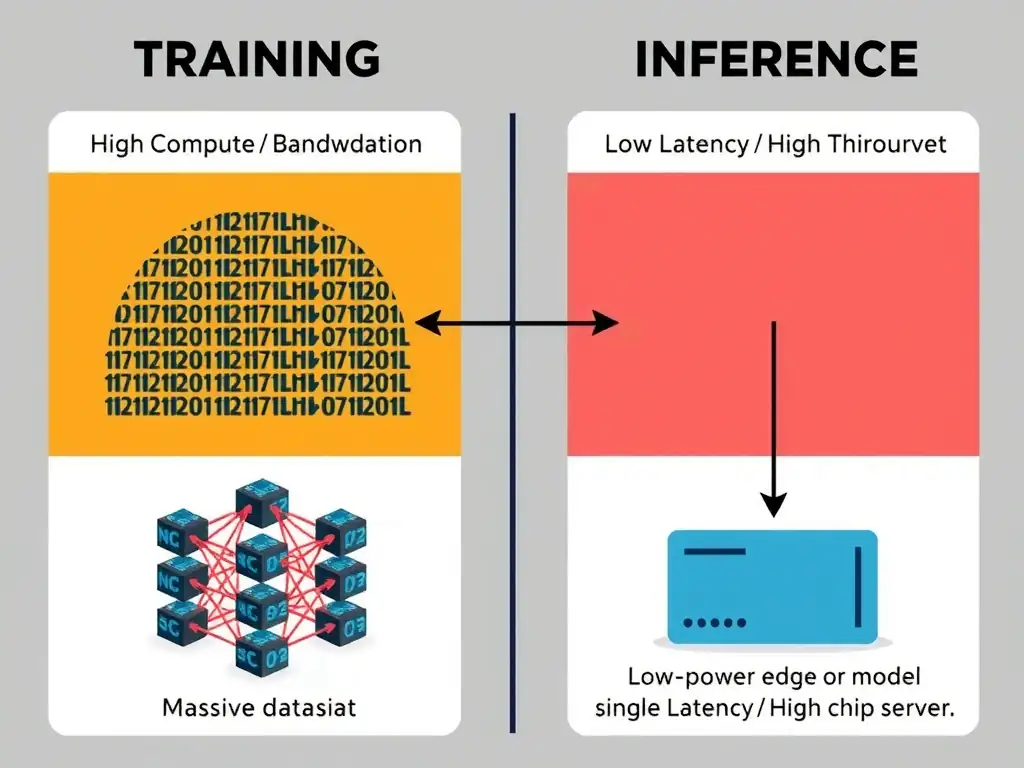
Here's the deal: training is the heavy lifting, using high-power parallel computing to calculate and adjust weights. Inference is the fast service path, where you care about low latency and high throughput for individual queries. Keep this straight: training builds the model, inference runs it.
Full Explanation
The lifecycle of an AI model is divided into two primary execution phases: training and inference. Each phase imposes completely different workloads on hardware infrastructure.
Training is the process of building the model. It involves feeding massive datasets through the neural network, calculating the loss, and performing backpropagation to adjust millions or billions of weights. This is an iterative, mathematically intense process requiring double-precision or half-precision floating-point operations. Training architectures must scale across multiple nodes and GPUs, using high-speed interconnects like NVLink, to handle the massive compute and memory bandwidth required to process batches of data.
Inference is the process of using a trained model to make predictions on new, unseen data. In this phase, the weights are fixed, no backpropagation is performed, and data only flows forward through the network. The primary goals of inference architectures are minimizing response latency, the time it takes to return a prediction, and maximizing throughput, the number of predictions per second for individual queries, often in real-time environments like web services or edge devices. Consequently, inference hardware often utilizes lower-precision data types, like INT8, to speed up execution and reduce power consumption.
The claim that inference demands massive compute power to perform backpropagation, while training requires minimal memory bandwidth, is incorrect because training involves both forward and backward passes across massive batches, requiring significantly more memory bandwidth and compute power than inference.
The claim that training is typically deployed on low-power edge devices, while inference is restricted to large multi-GPU data center clusters, is backwards. Training is rarely done on low-power edge devices due to its massive computational demands, whereas inference is frequently deployed on edge hardware, like mobile phones or smart cameras.
The claim that inference requires distributed multi-node clusters using NVLink, while training is always run on single-socket machines, is also incorrect because distributed training requires high-bandwidth multi-node systems with interconnects like NVLink to synchronize gradients, whereas inference typically runs on single-GPU or CPU nodes.
Understanding this distinction allows architects to allocate expensive multi-GPU clusters for training while using lighter, cost-effective accelerators for inference deployment.