
An enterprise team is designing an end-to-end pipeline to run on their cloud GPU cluster. The workflow needs to accelerate data preprocessing and classic machine learning training on GPUs, serve multiple deep learning models in production with dynamic batching and performance monitoring, and automate the underlying Kubernetes/Slurm infrastructure provisioning. Which combination of NVIDIA solutions meets all these requirements?
Select an answer to reveal the explanation.
Short Explanation
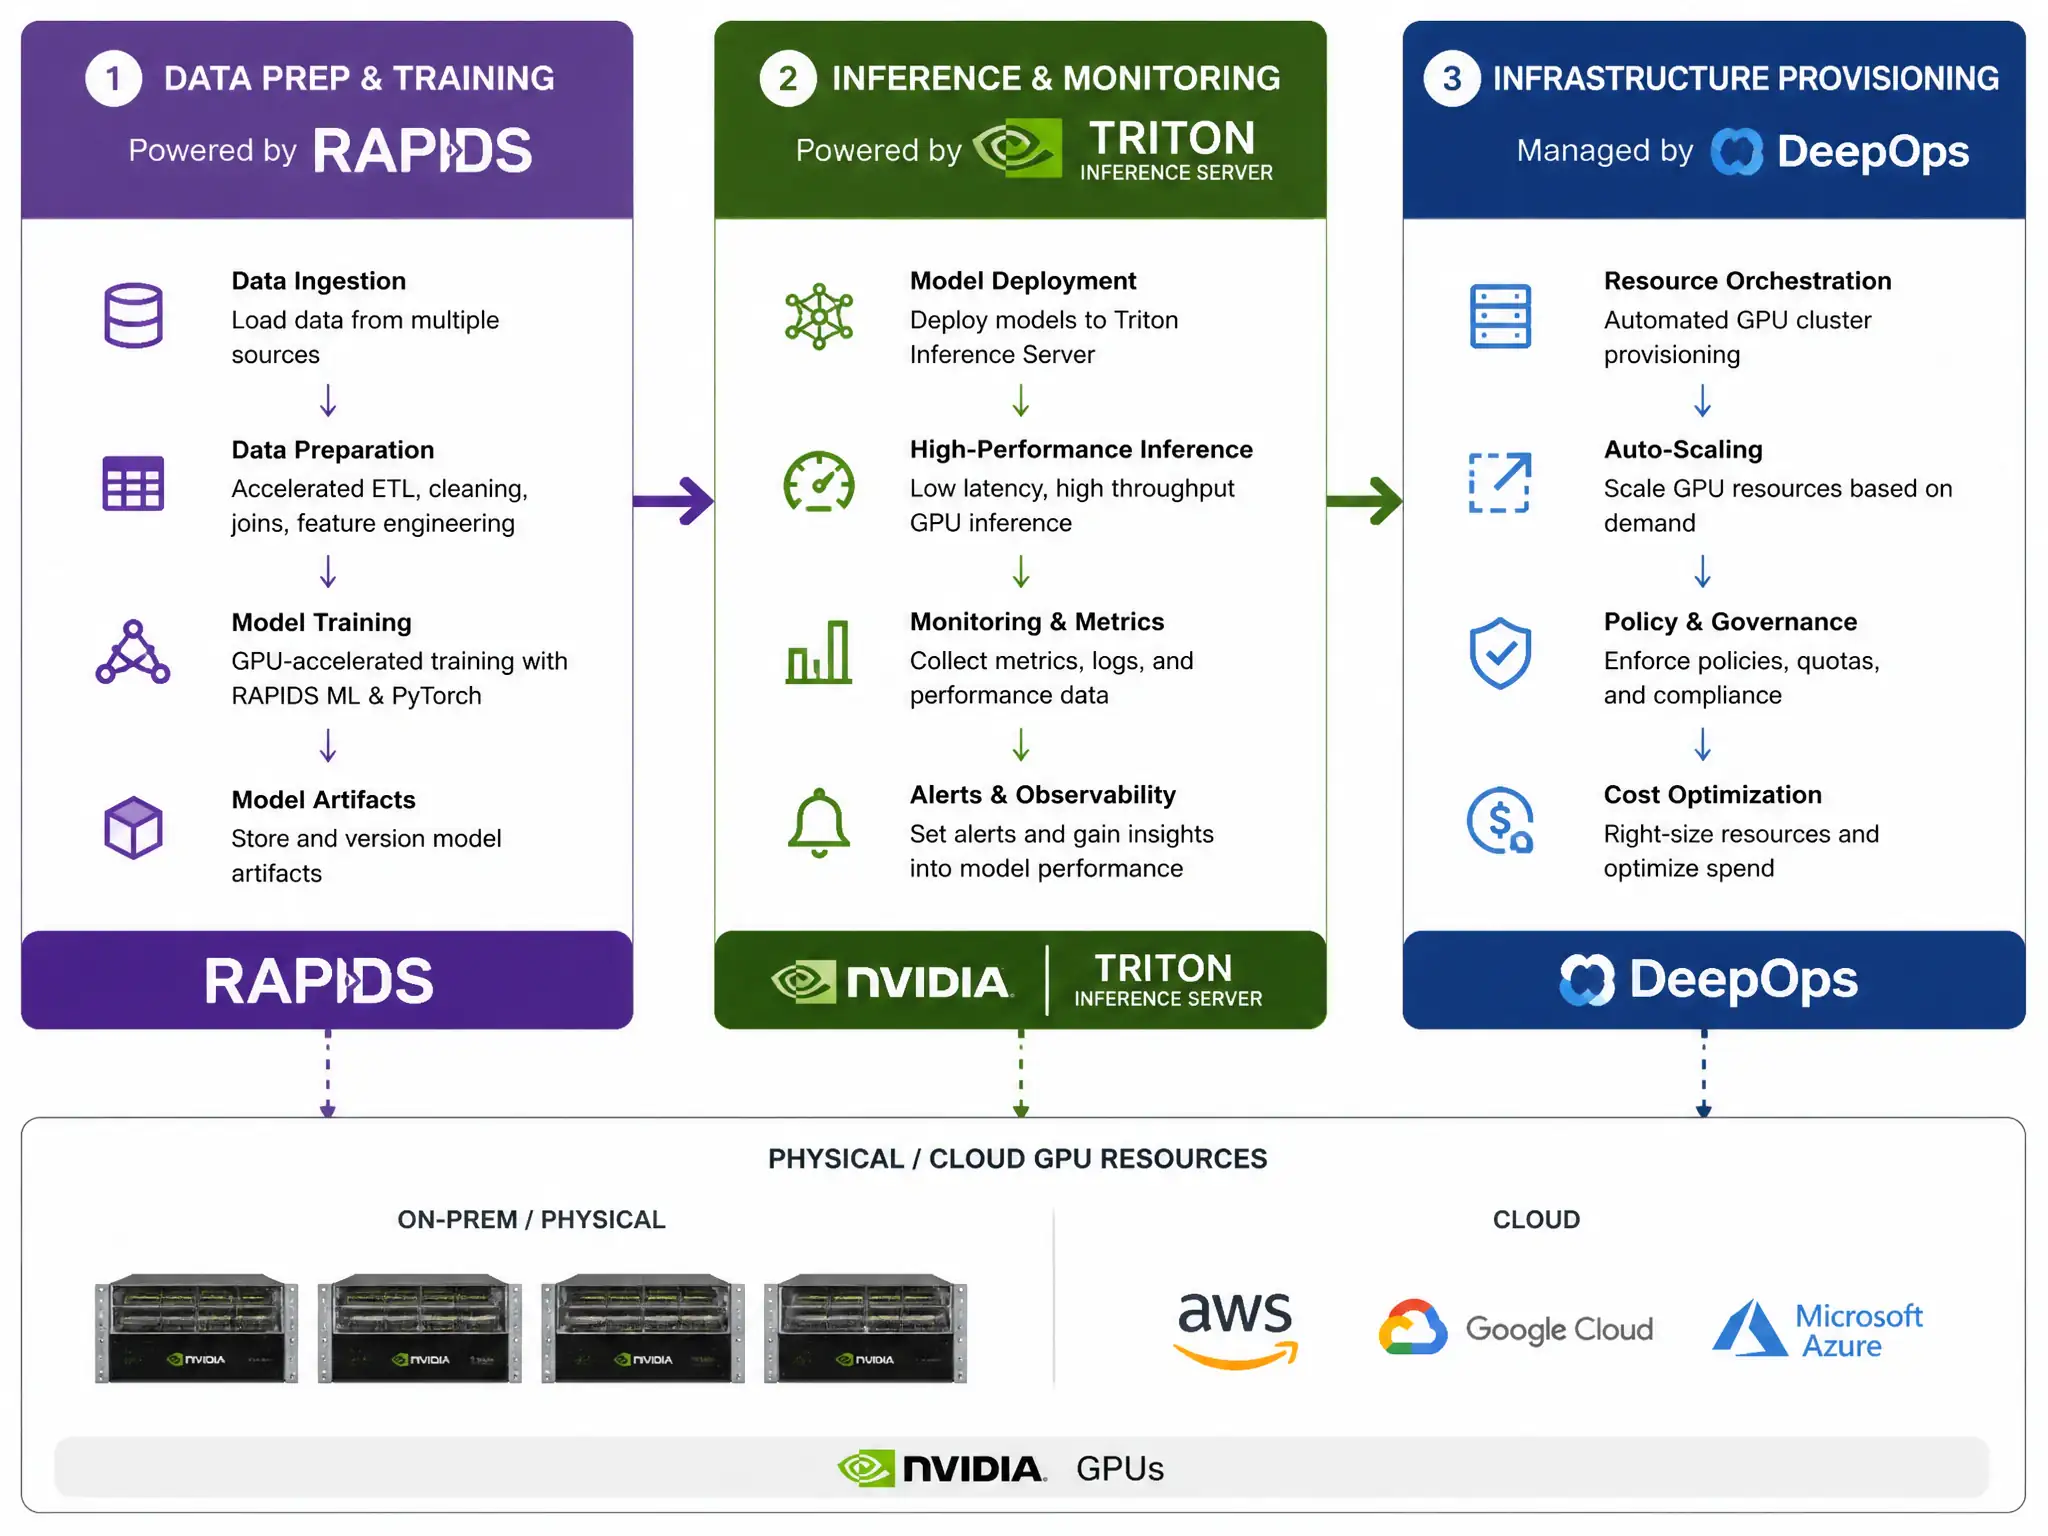
Check this out: you need RAPIDS to accelerate data prep and classic ML training, Triton Inference Server to serve multiple models with dynamic batching and monitoring, and DeepOps to automate Kubernetes/Slurm provisioning. That trio covers the full pipeline from raw data to production. Without DeepOps, you'll be stuck hand-building cluster YAML.
Full Explanation
Building an enterprise AI workflow requires software that spans data science, model serving, and infrastructure provisioning. The complete end-to-end solution must integrate these three stages seamlessly.
The correct combination is NVIDIA RAPIDS, NVIDIA Triton Inference Server, and NVIDIA DeepOps.
1. Data Science and Training Acceleration: NVIDIA RAPIDS is a suite of open-source software libraries (such as cuDF and cuML) built on CUDA. It enables executing end-to-end data science and analytics pipelines entirely on GPUs, cutting down data preparation and traditional machine learning training times from hours to minutes. 2. Model Serving and Monitoring: NVIDIA Triton Inference Server is an enterprise-grade open-source inference serving software. It enables teams to deploy trained AI models from any framework (TensorFlow, PyTorch, ONNX, TensorRT, etc.) on CPU or GPU-based infrastructure. It features dynamic batching, concurrent model execution, model ensembling, and built-in Prometheus metrics for real-time monitoring. 3. Infrastructure Orchestration: NVIDIA DeepOps provides deployment scripts and templates (utilizing Ansible, Kubernetes, Helm, and Slurm) to automate the setup and management of GPU-accelerated compute, networking, and storage infrastructure.
Let's review the incorrect combinations: - The combination of NVIDIA Nsight Systems, NVIDIA TensorRT, and NGC Container Registry is wrong because, while Nsight Systems, TensorRT, and NGC are valuable, they lack data processing libraries (RAPIDS) and infrastructure provisioning automation (DeepOps), covering only optimization and container acquisition. - The combination of NVIDIA Clara Deploy SDK, NVIDIA Triton Inference Server, and NVIDIA BlueField DPU drivers is wrong because Clara Deploy SDK is heavily vertical-specific (healthcare imaging and genomics) and does not provide general-purpose accelerated data science (RAPIDS) or cluster orchestration templates (DeepOps). - The combination of NVIDIA RAPIDS, NVIDIA TensorRT, and NVIDIA Nsight Compute is wrong because it lacks an infrastructure automation framework (like DeepOps) and a dedicated inference serving server (like Triton), focusing instead on profiling (Nsight Compute) and raw model optimization (TensorRT).
Therefore, the combination of NVIDIA RAPIDS, Triton Inference Server, and DeepOps offers a comprehensive, general-purpose end-to-end pipeline solution.