
You are assisting in troubleshooting a distributed training job for a large neural network across an 8-GPU node. You notice that while GPU 0 is pinned at 100% utilization, the other seven GPUs (GPUs 1-7) are frequently sitting idle or showing very low utilization. What is the most likely cause of this poor scaling performance?
Select an answer to reveal the explanation.
Short Explanation
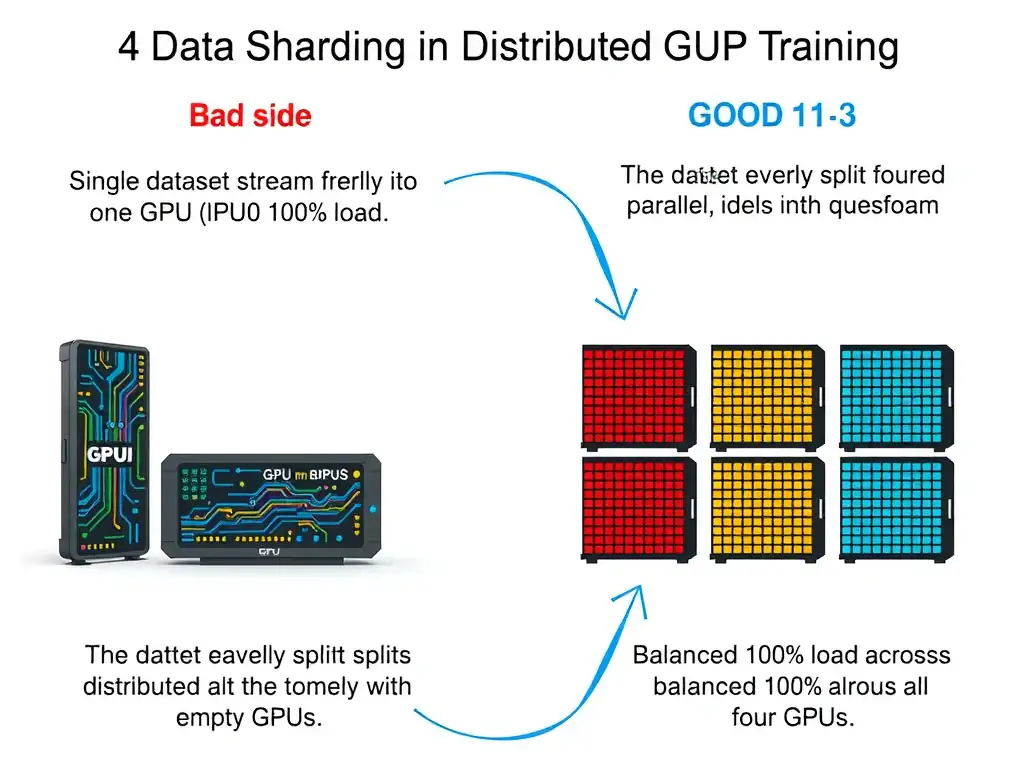
Pay close attention, because this bites people in production all the time. If your dataset isn't sharded correctly, GPU 0 does the heavy lifting while the other seven GPUs just sit there waiting. Use a distributed sampler so every GPU gets its own equal slice of the data.
Full Explanation
Distributed training on multiple GPUs relies on parallel processing techniques, most commonly Data Parallelism or Distributed Data Parallelism. In these paradigms, the model is replicated across all GPUs, and the training dataset must be partitioned so that each GPU processes a unique subset (shard) of the data during each step. The most likely cause here is that the training dataset is not partitioned (sharded) correctly among the GPUs, forcing one GPU to process the bulk of the data while the others wait. If the dataset isn't sharded properly, the pipeline suffers from severe workload imbalance. Typically, this manifests as a single GPU (often GPU 0, which acts as the coordinator) performing the bulk of the data loading, preprocessing, or gradient aggregation, while the remaining GPUs wait idle. A proper implementation uses a distributed data sampler (like PyTorch's DistributedSampler) to ensure that each GPU processes an equal-sized, unique chunk of the batch simultaneously. The gradients are then synchronized across all GPUs using collective communication operations (such as All-Reduce) via NCCL. Without proper sharding, you lose the linear speedup expected from multi-GPU scaling.
The choice claiming the global batch size is configured too high, causing out-of-memory errors on the primary GPU, is wrong because if the global batch size were set too high, it would typically trigger an out-of-memory error on the GPUs, crashing the training script entirely rather than causing low utilization on the other GPUs. The choice claiming the learning rate scheduler is not synchronized across the worker processes, causing them to stall, is wrong because learning rate schedulers are mathematical functions that update the learning rate hyperparameter. While they must be synchronized to ensure mathematical correctness, desynchronization does not physically prevent GPUs from executing their compute kernels or cause them to sit idle. The choice claiming the model is too simple, causing the GPUs to complete their calculations faster than the PCIe bus can transmit data, is wrong because a model being 'too simple' would result in high data transfer overhead relative to computation, but it would affect all GPUs relatively equally (high communication overhead causing overall low utilization across all GPUs, not one GPU at 100% and others idle).