
Your production Kubernetes cluster is running real-time AI inference services across several multi-GPU nodes. You observe that some GPU nodes are overloaded and bottlenecked, while others sit idle, causing inconsistent latency. What strategy should you implement to balance the GPU workload across the cluster?
Select an answer to reveal the explanation.
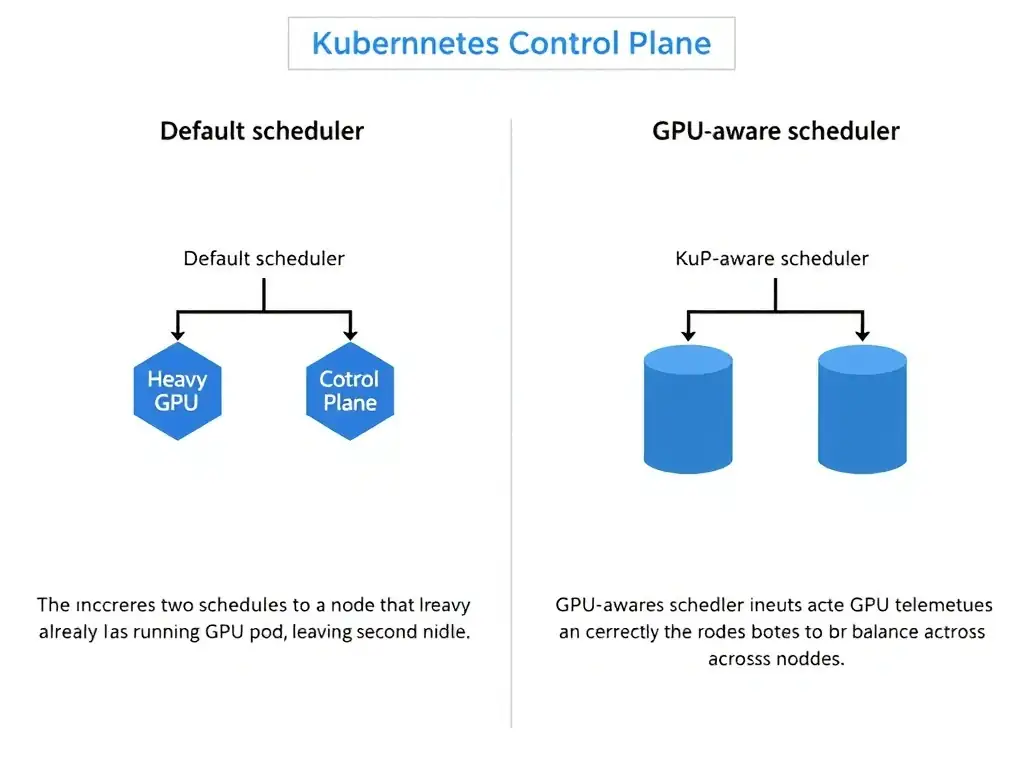
Short Explanation
Here's the deal: standard Kubernetes only sees GPUs as a yes-or-no resource, so it can pile heavy inference pods onto one GPU node while another sits idle. You need a GPU-aware scheduler that reads real GPU telemetry—memory, utilization, and topology—and places pods where there are actual free GPU cycles. CPU-based autoscaling won't help because your CPUs aren't doing the heavy lifting.
Full Explanation
In a standard Kubernetes cluster, the default scheduler makes decisions based on CPU and system memory requests and limits. It lacks visibility into GPU-specific metrics, such as GPU memory usage, temperature, or compute utilization, and topology, such as NVLink connections between GPUs. Consequently, it may place multiple GPU-intensive pods on the same node, causing resource contention, while other GPU nodes remain underutilized.
To resolve this imbalance, deploy a GPU-aware scheduler, such as NVIDIA's GPU-aware scheduling stack or custom scheduler plugins. A GPU-aware scheduler integrates with the Kubernetes control plane and gathers real-time telemetry from nodes via agents like the NVIDIA Device Plugin and DCGM. It evaluates parameters like GPU memory capacity, topology, and current utilization when determining the optimal node for a pod. This ensures balanced distribution of inference workloads, prevents hot-spotting, and maintains consistent low latency.
The approach that scales on host CPU utilization is wrong because host CPU usage is a poor proxy for GPU workloads; an inference container might max out a GPU while consuming very little CPU, leaving the autoscaler unresponsive. The approach that consolidates workloads by reducing the physical count of GPU nodes is wrong because it decreases overall cluster capacity and worsens performance congestion, rather than balancing the existing workload. The approach that applies strict namespace-level GPU resource quotas is wrong because quotas limit the maximum number of GPUs a team or namespace can allocate, but they do not solve the scheduling problem of how pods are distributed across the physical nodes.
Furthermore, GPU-aware scheduling is critical when running distributed multi-node training workloads, such as PyTorch Elastic or Torchrun. The scheduler can ensure that pods belonging to the same training job are scheduled on nodes with high-speed interconnects, such as NVLink and InfiniBand, rather than scattered across nodes separated by slower Ethernet switches, minimizing communication latency.
Thus, deploying a GPU-aware scheduler in Kubernetes to distribute pods based on GPU metrics is the correct and most effective architectural solution.