
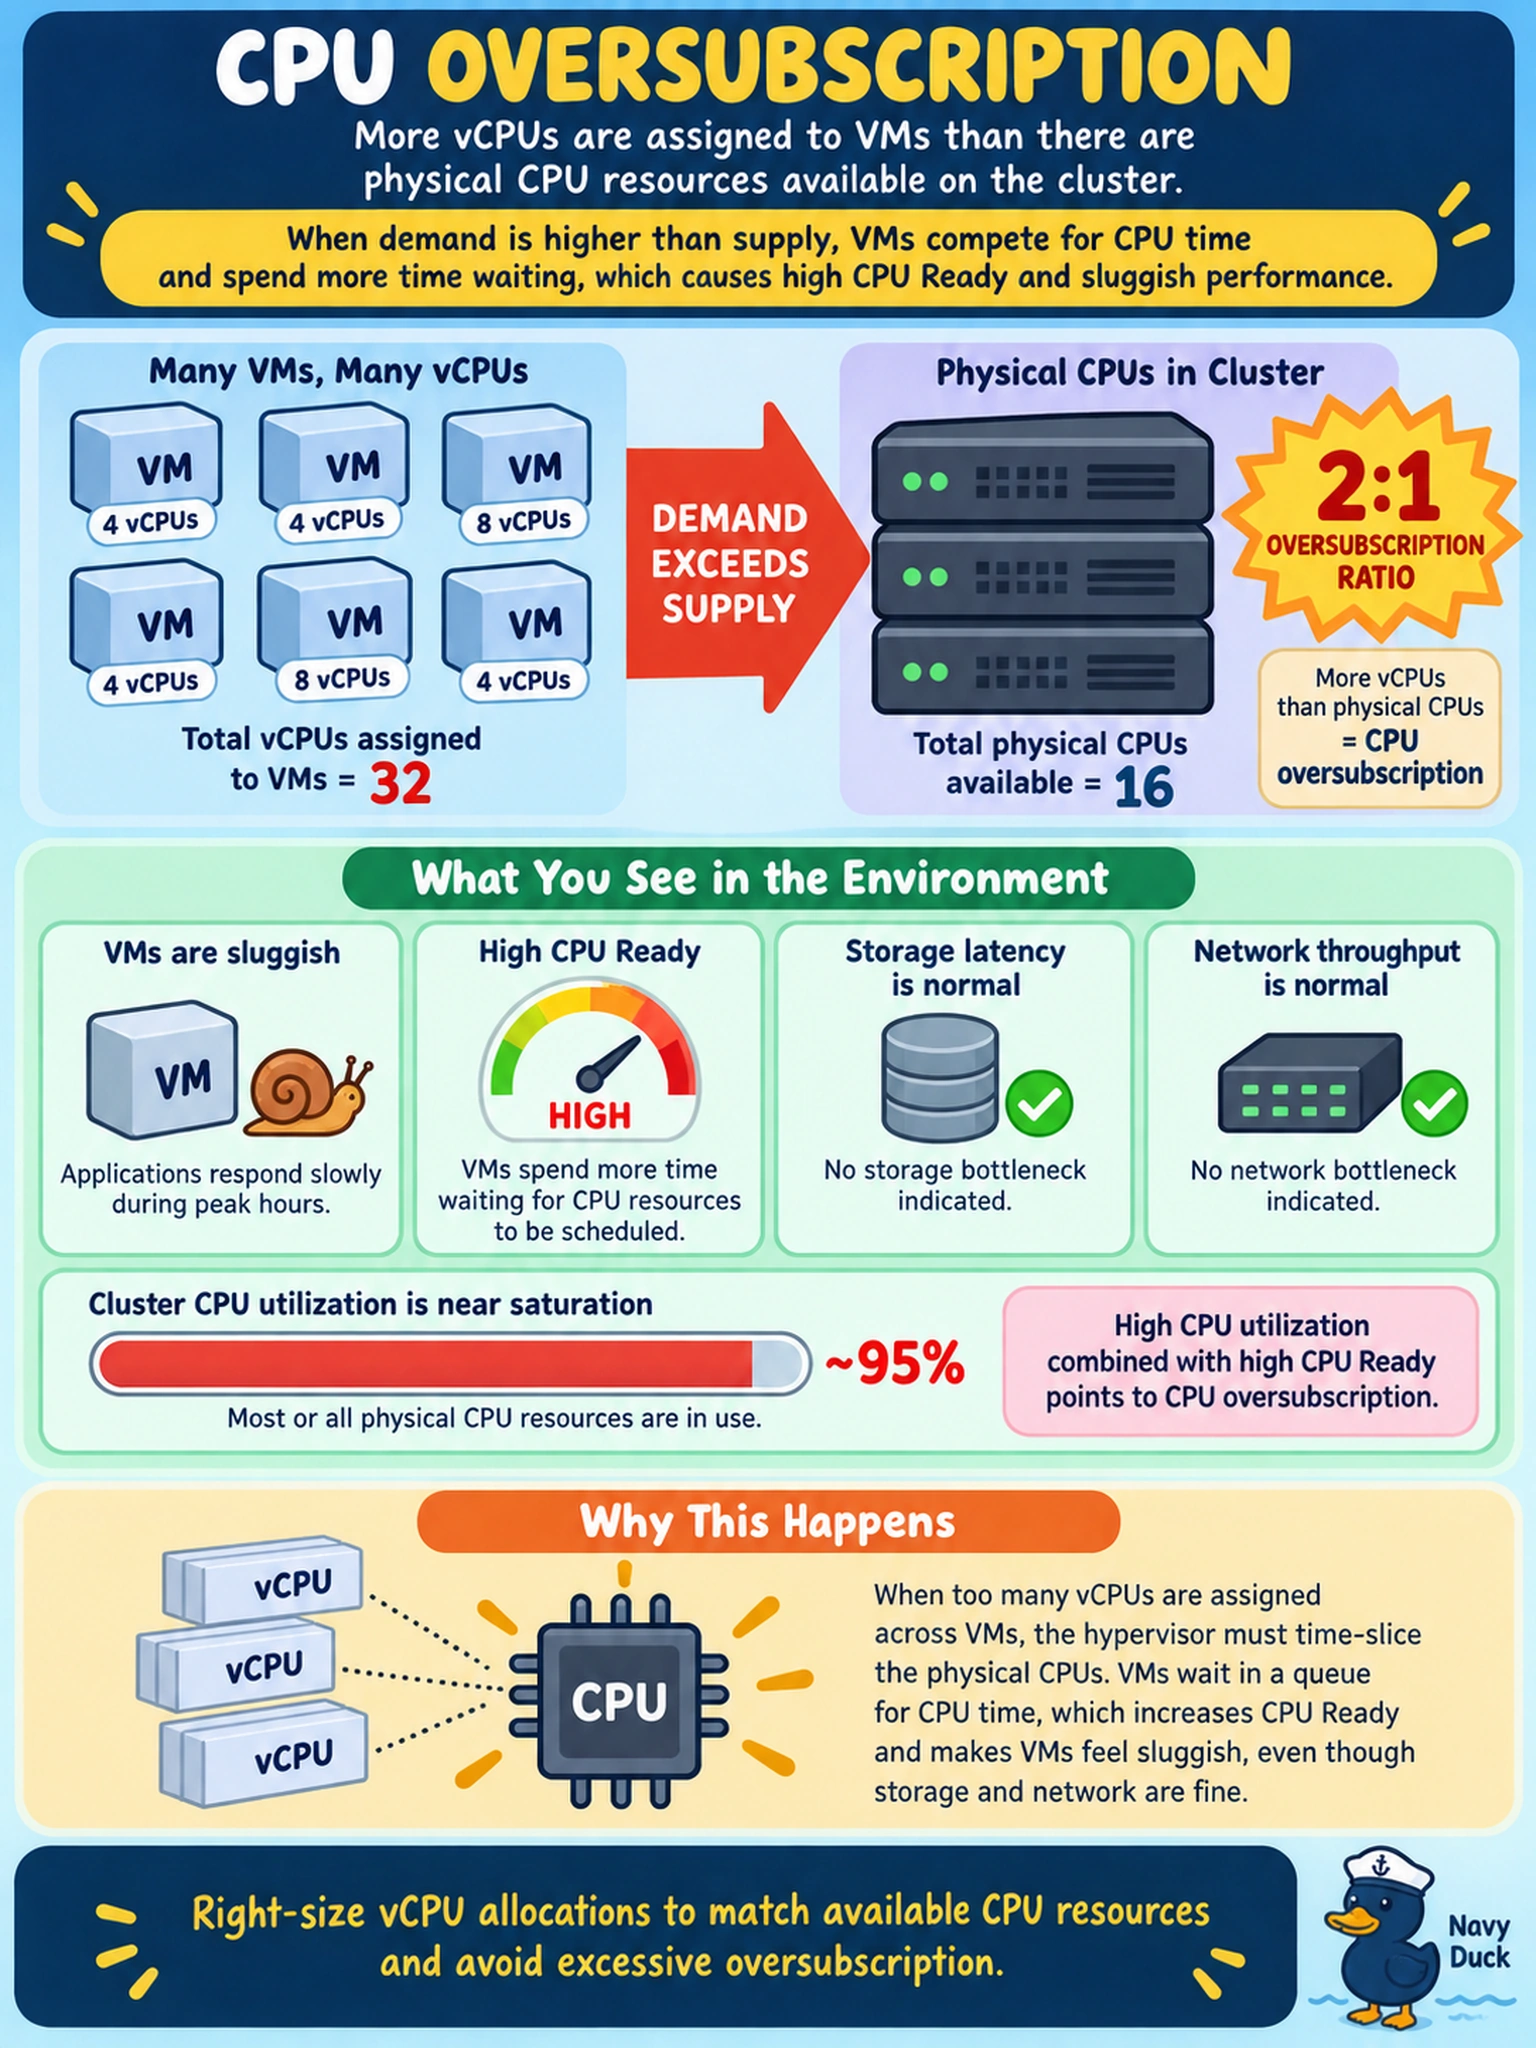
During peak business hours, multiple AHV VMs in a Prism Central-managed cluster become sluggish and show high CPU Ready, while storage latency and network throughput remain normal. Cluster CPU utilization is near saturation. What is the most likely root cause?
Select an answer to reveal the explanation.
Short Explanation
Think of a busy coffee shop: if everyone orders at once and there's only one barista, the queue backs up even when the espresso machine is fine. You'll see high CPU Ready and slow response when vCPUs are oversubscribed, not when storage or networking is healthy.
Full Explanation
CPU contention on AHV occurs when the aggregate vCPU demand of powered-on VMs exceeds the physical CPU cycles available on one or more hosts, so guest threads spend time waiting for scheduler execution. The visible symptom is poor responsiveness, elevated CPU Ready or steal time, and high cluster CPU utilization while storage I/O latency, network throughput, and memory pressure remain within normal limits. This is a resource-management condition, not a hardware fault, and it is identified by correlating VM-level CPU Ready with host CPU contention and placement. Compression overhead is a storage data-path effect; it would raise storage latency, CVM or Curator-related metrics, and I/O wait rather than CPU Ready. Flow inspection delay affects packet processing and network service latency, producing throughput or packet-loss symptoms instead of scheduler starvation. Memory reservations or ballooning create guest memory pressure, swap or reclaim activity, and memory-related performance degradation, not primary CPU contention. Exam caveat: distinguish CPU Ready and scheduler starvation from storage latency, network inspection, and memory pressure before selecting a remediation. Operational check: review Prism Central host and VM CPU Ready, compare active vCPU demand with physical core capacity, and inspect placement and reservation settings for the affected hosts.