
A turnpike booth’s chart requests a GPU for Riva speech containers. A volunteer offers a custom kernel “to make the GPU count.” What is the correct stance?
Select an answer to reveal the explanation.
Short Explanation
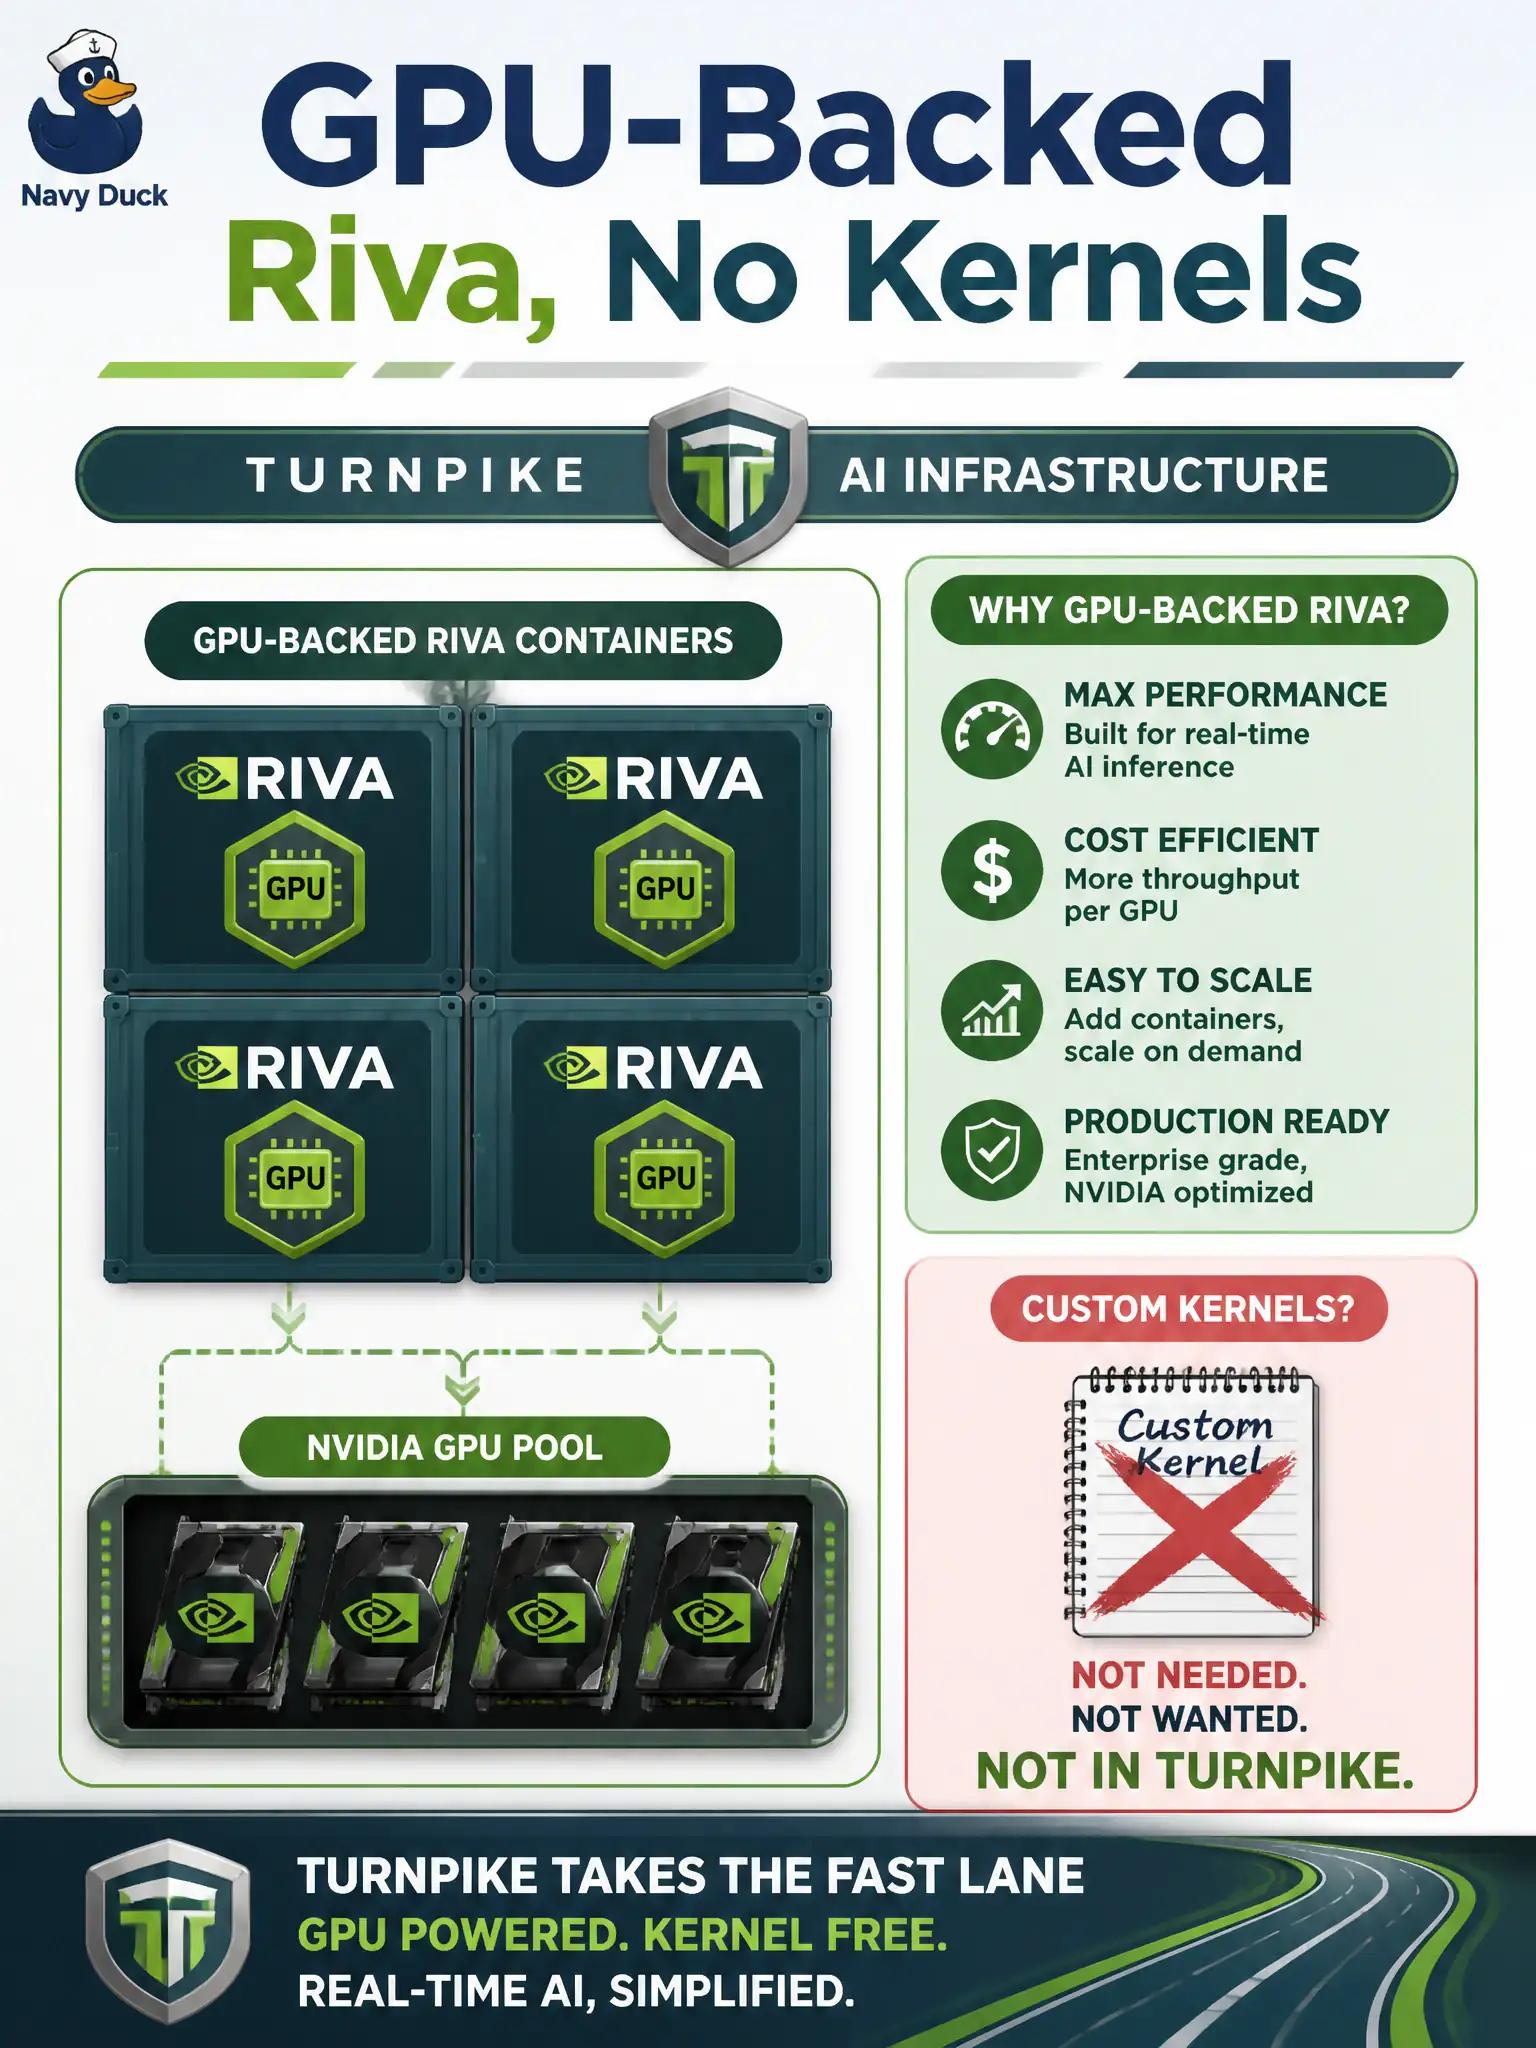
GPUs in the chart for official Riva speech are fine; homemade kernels are not the ticket. Use the accelerated service as shipped—do not reinvent the GPU in C++.
Full Explanation
A turnpike booth chart that requests a GPU for Riva speech containers should accept GPU-accelerated official Riva services in the chart and refuse custom kernel work. Associate performance allows accelerated official services without demanding handwritten CUDA as a gate.
Requiring a handwritten CUDA kernel before any GPU may appear in the chart fails because official Riva services already target GPUs without custom kernels. Removing GPUs from speech containers because associate exams forbid acceleration fails: accelerated official services are in scope. Replacing Riva with a RAPIDS kernel path as the official speech stack fails modality and product scope.
Exam caveat: GPUs for official Riva in Helm are fine; custom kernels are not the associate requirement to “make the GPU count.”
Operational check: enable GPU resource requests for Riva containers per chart guidance; reject custom-kernel tickets; validate latency on the civic turnpike booth after GPU scheduling. In municipal platform operations, record the chosen performance lever and the rejected alternatives in the change record so future on-call engineers understand the failure modes avoided for citizen services. Re-check the decision after the next traffic spike or model update to ensure the same answer still holds for the city's estate.