
A cameo-carver intern wants either to flatten PDF bytes into a training tensor or to start a Domain 1 wording trial on garbage text. What is the Domain 5 path first?
Select an answer to reveal the explanation.
Short Explanation
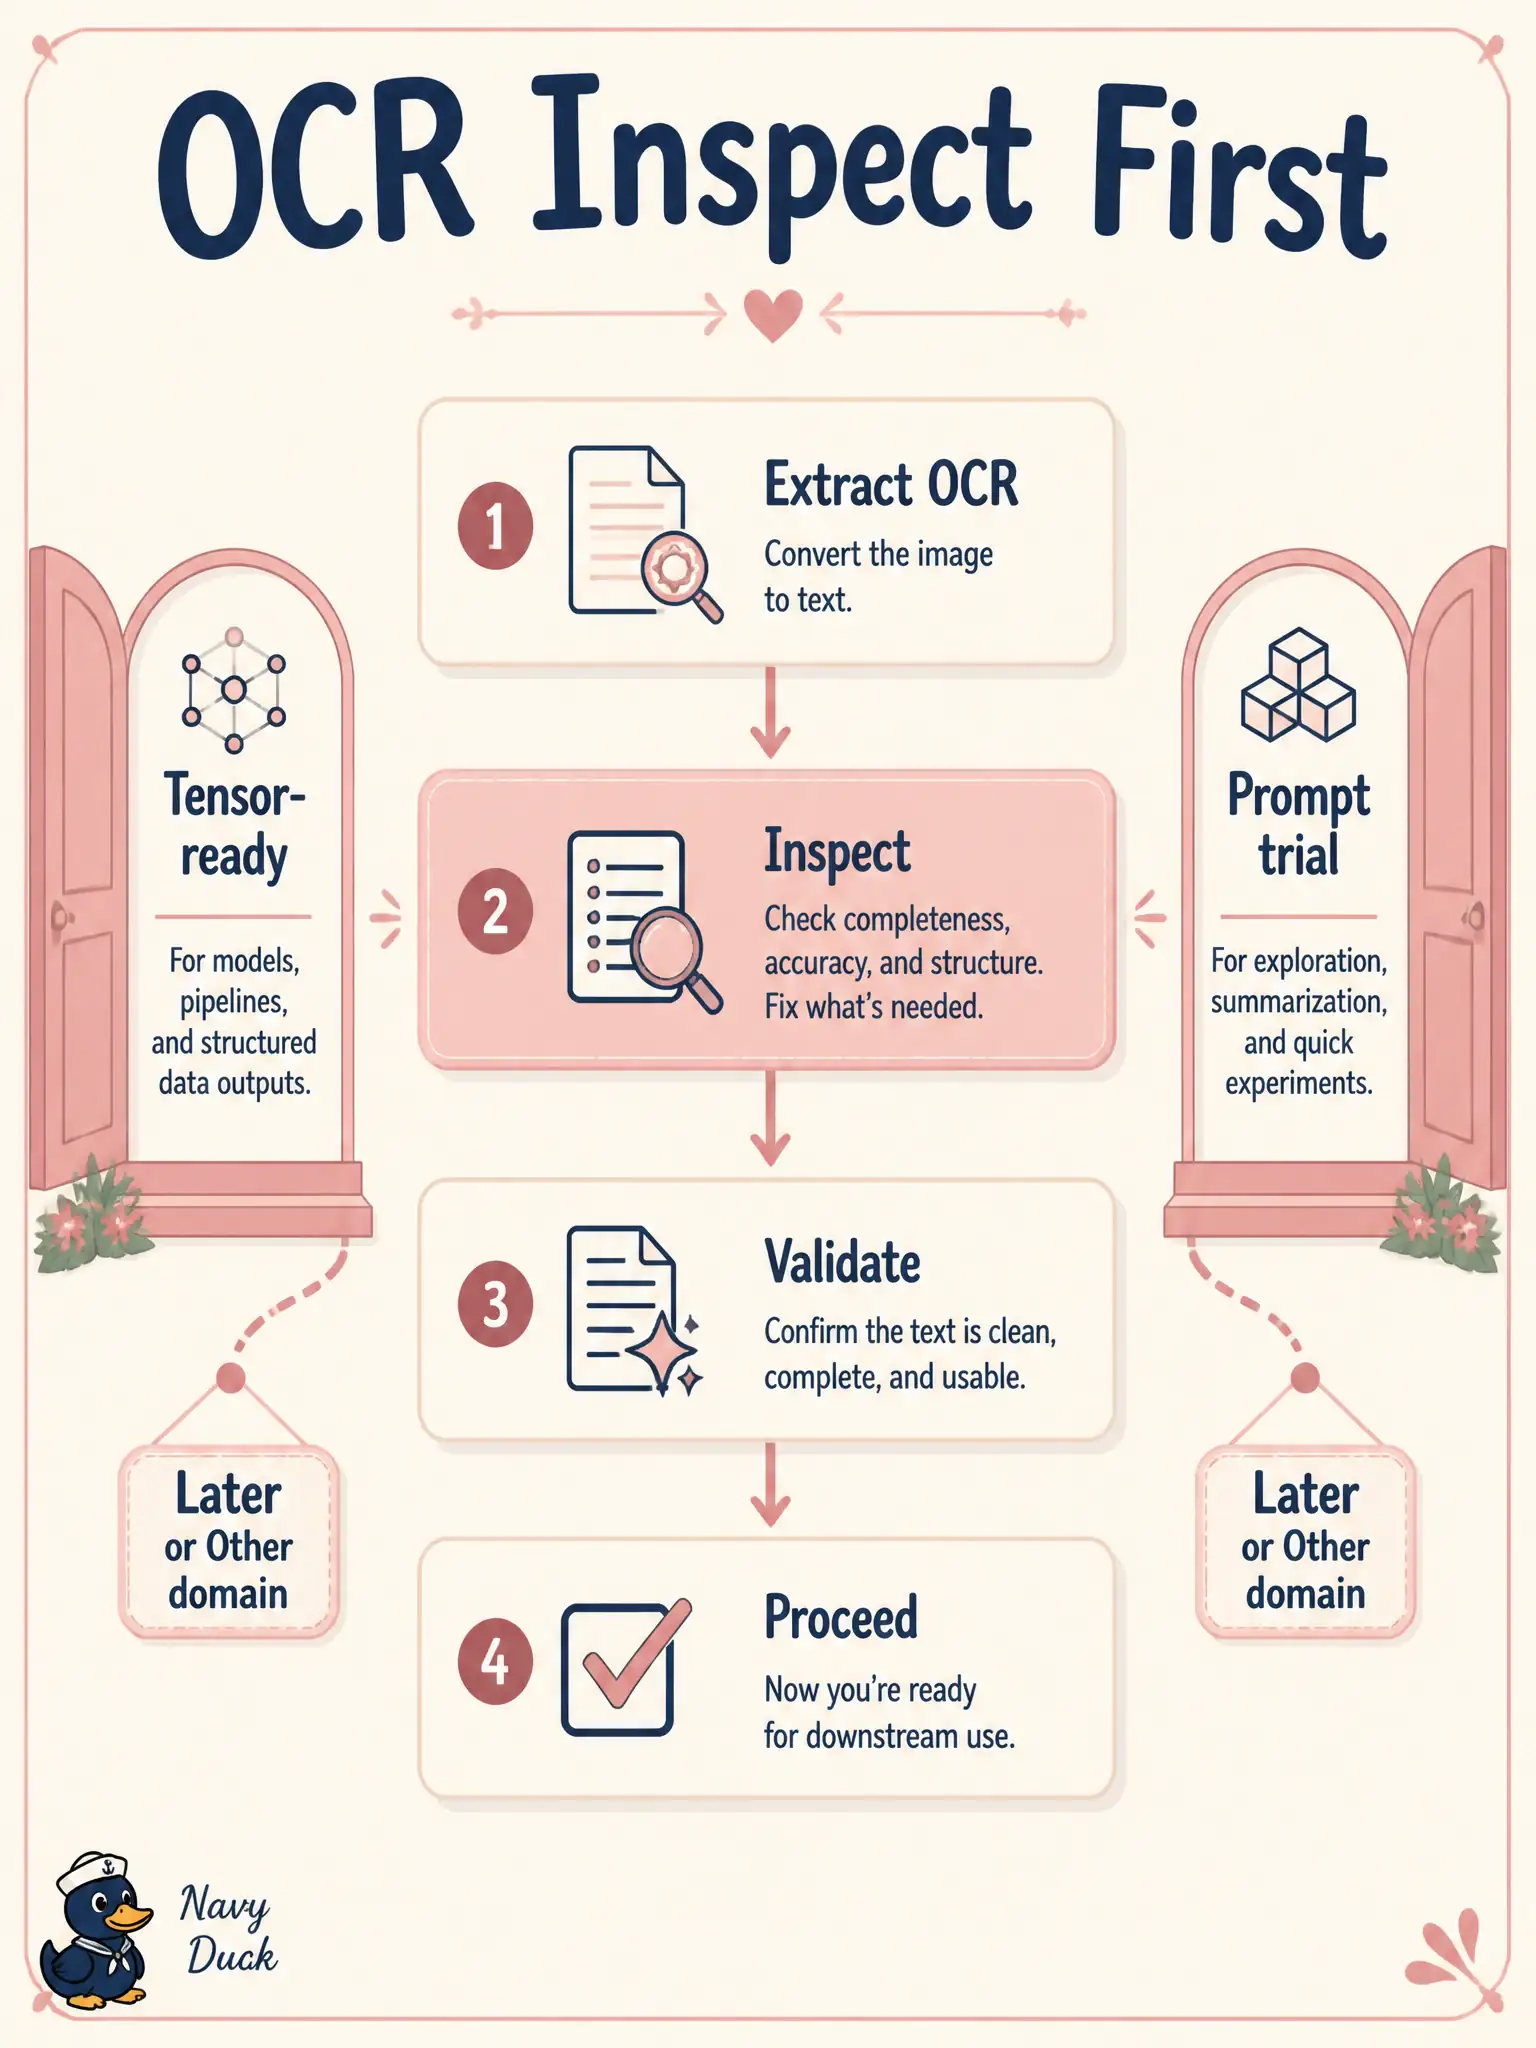
You read the menu before you cook or critique the poetry of the typos. Extract and inspect OCR first—that is Domain 5—before tensor talk or generator trials.
Full Explanation
A cameo-carver intern who wants either to flatten PDF bytes into a training tensor or to start a Domain 1 wording trial on garbage text should first extract and inspect the OCR output as document analysis. Domain 5 requires readable, inspected text before tensor packaging or generator prompt trials on unread garbage.
Skipping extraction and declaring the PDF tensor-ready as-is fails because uninspected bytes are not analyzed document text. Beginning Domain 1 generator prompt trials on the unread garbage string fails by experimenting on noise instead of cleaning document text. Treating the PDF as a Domain 7 authenticity deepfake of the workshop fails because the immediate need is OCR inspection, not a deepfake verdict.
Exam caveat: extract → inspect → then decide. Domain 5 document analysis precedes Domain 1 generation experiments and Domain 2 tensor packaging myths.
Operational check: OCR the cameo PDF; open a sample in a review UI; measure garbage rate; only after a pass/fail decision allow downstream tensor packaging or any generator trials for the municipal workshop. In municipal multimodal stewardship, record the chosen Domain 5 reading and the rejected distractors in the loft change log so future stewards understand which concept boundaries were enforced for citizen-facing archives. Re-check the same chart or extraction after the next collection or OCR pass to confirm the civic gap is closing rather than merely relabeled.