
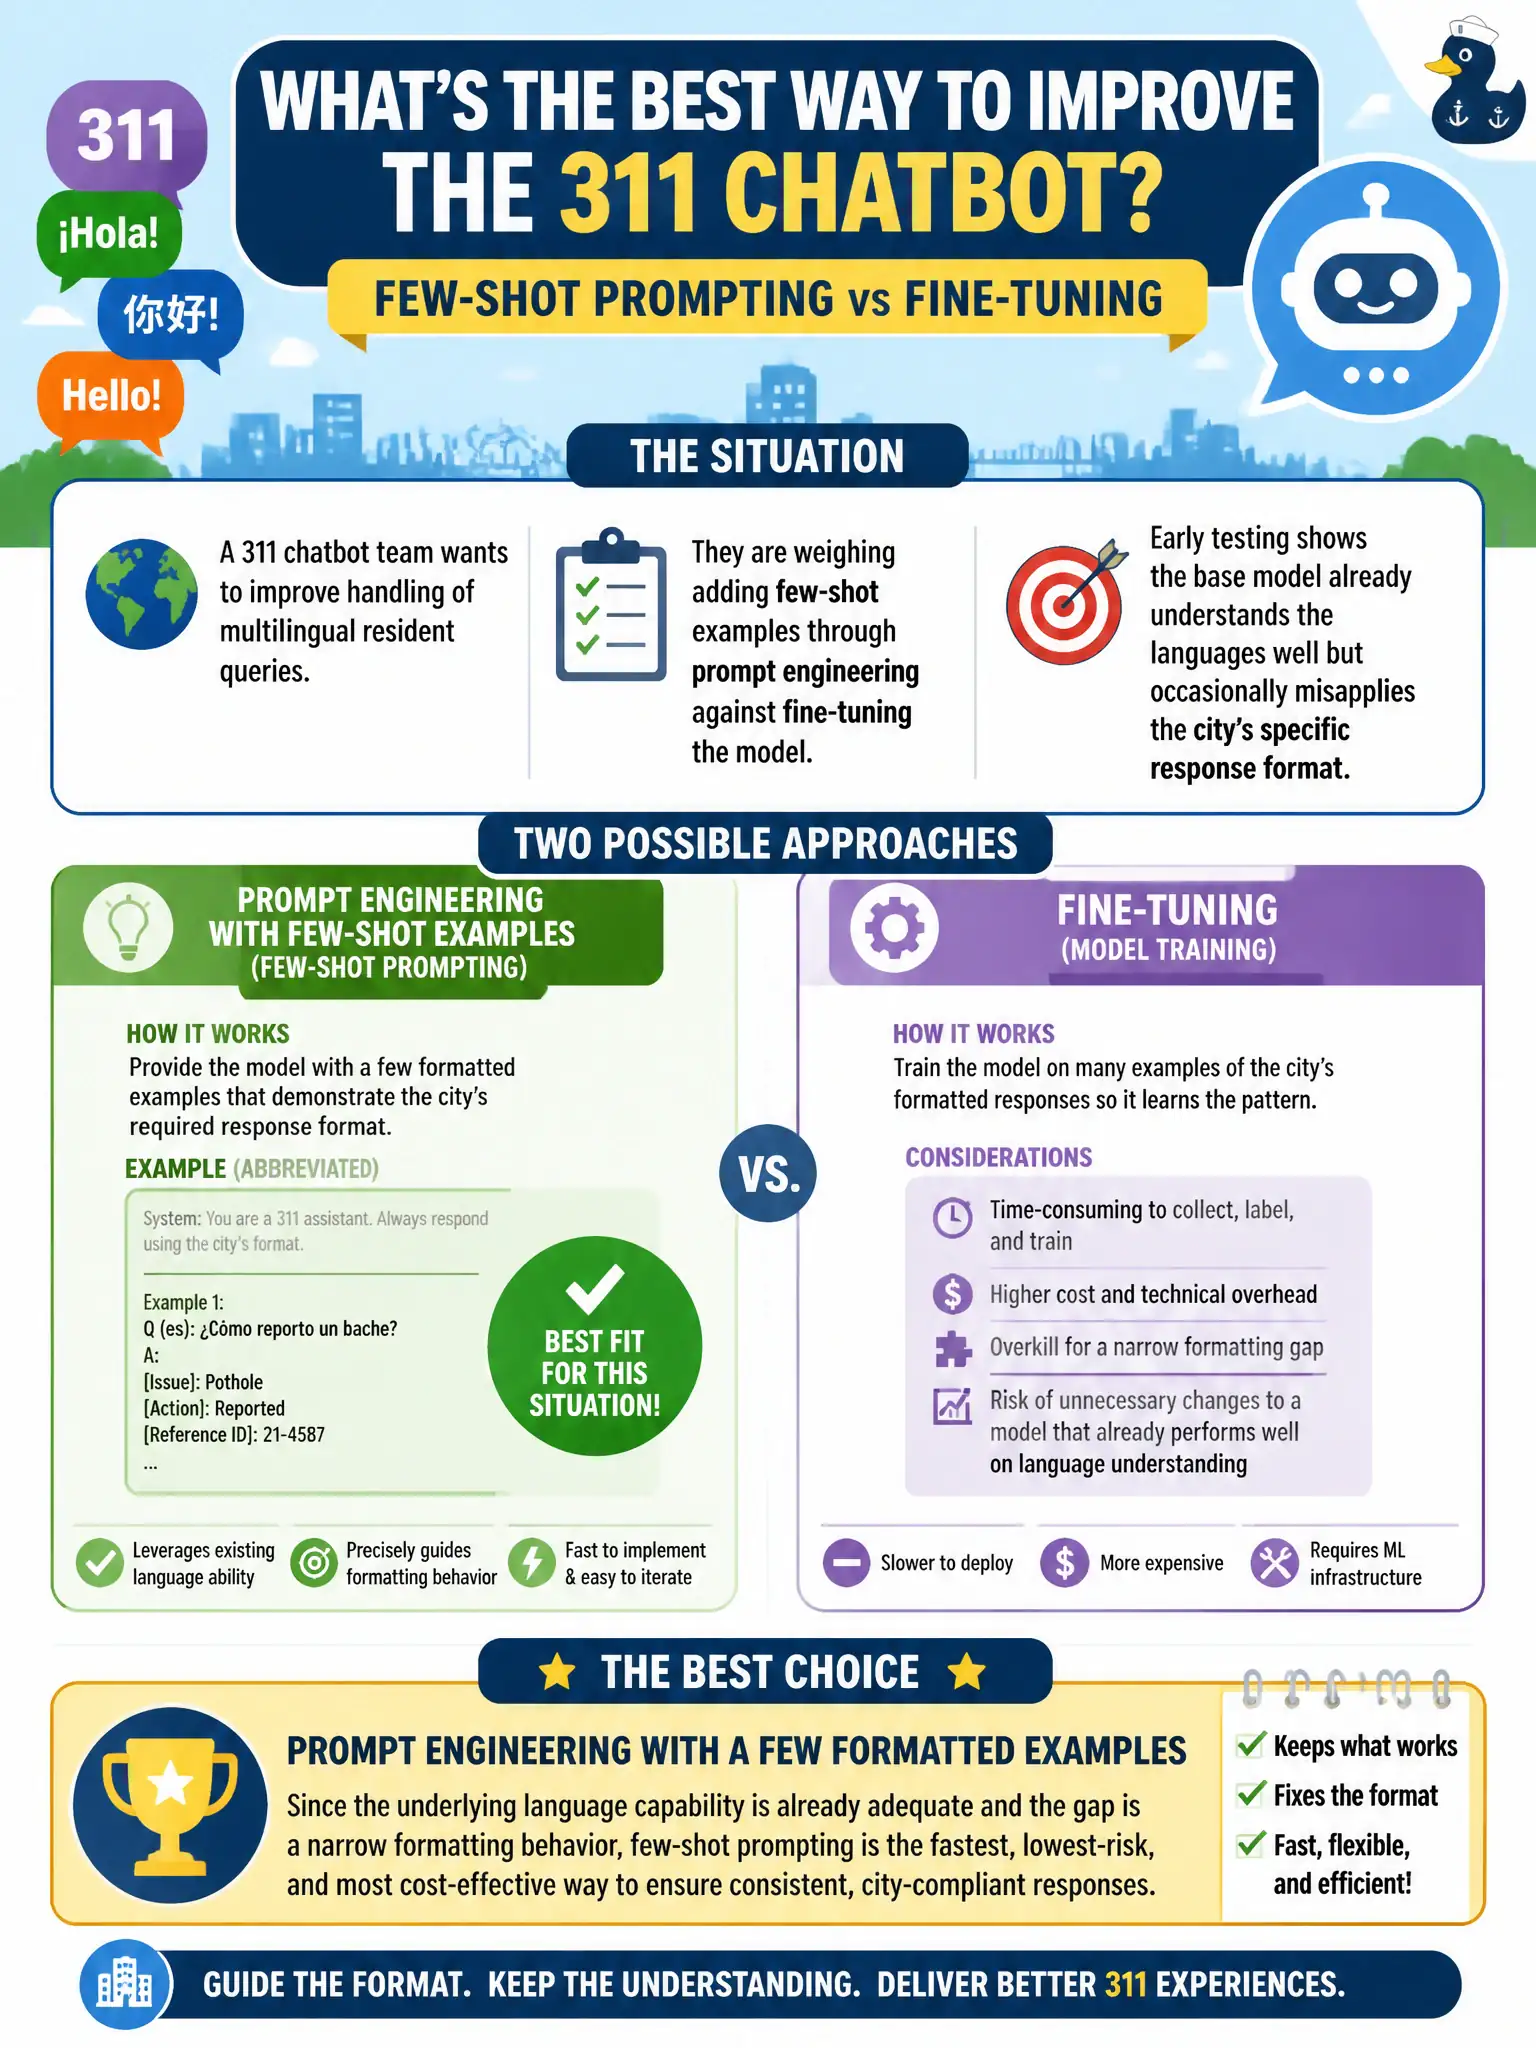
A 311 chatbot team wants to improve handling of multilingual resident queries and is weighing adding few-shot examples through prompt engineering against fine-tuning the model. Early testing shows the base model already understands the languages well but occasionally misapplies the city's specific response format. Which approach fits this situation best?
Select an answer to reveal the explanation.
Short Explanation
Think of a translator who already speaks every language fluently but keeps forgetting to sign the letter the way city hall wants — the fix isn't more language lessons, it's a couple of clear examples showing the expected format. When the base capability is already solid and the gap is narrow and behavioral, a few well-chosen prompt examples usually close it faster and cheaper than retraining anything.
Full Explanation
Prompt engineering, particularly few-shot prompting with examples that demonstrate the desired response format, is well suited to closing narrow behavioral gaps when the model's underlying capability, in this case multilingual understanding, is already adequate. Showing the model a small number of correctly formatted examples in the prompt steers its output pattern without touching its weights, which is faster, cheaper, and lower-risk than a training-based fix for this kind of targeted formatting issue. Fine-tuning on a large labeled dataset is a heavier intervention than the problem calls for, and the claim that prompt engineering cannot influence formatting is simply false, since output structure and style are exactly the kind of behavior few-shot examples are effective at shaping. Continuous pre-training targets broad domain or language knowledge gaps, but the scenario states language understanding is already adequate, so exposure to more raw multilingual text would not address a narrow response-format problem. Distillation produces a smaller, cheaper model that approximates a teacher's behavior; it does not inherently improve or correct formatting inconsistencies, and a smaller model has no built-in tendency toward stricter format compliance. Scope note: if formatting issues persist across many edge cases despite good few-shot examples, that may signal a larger fine-tuning need instead. Operational check: test the few-shot prompt against a sample of prior multilingual queries that previously showed formatting errors to confirm the fix generalizes.