
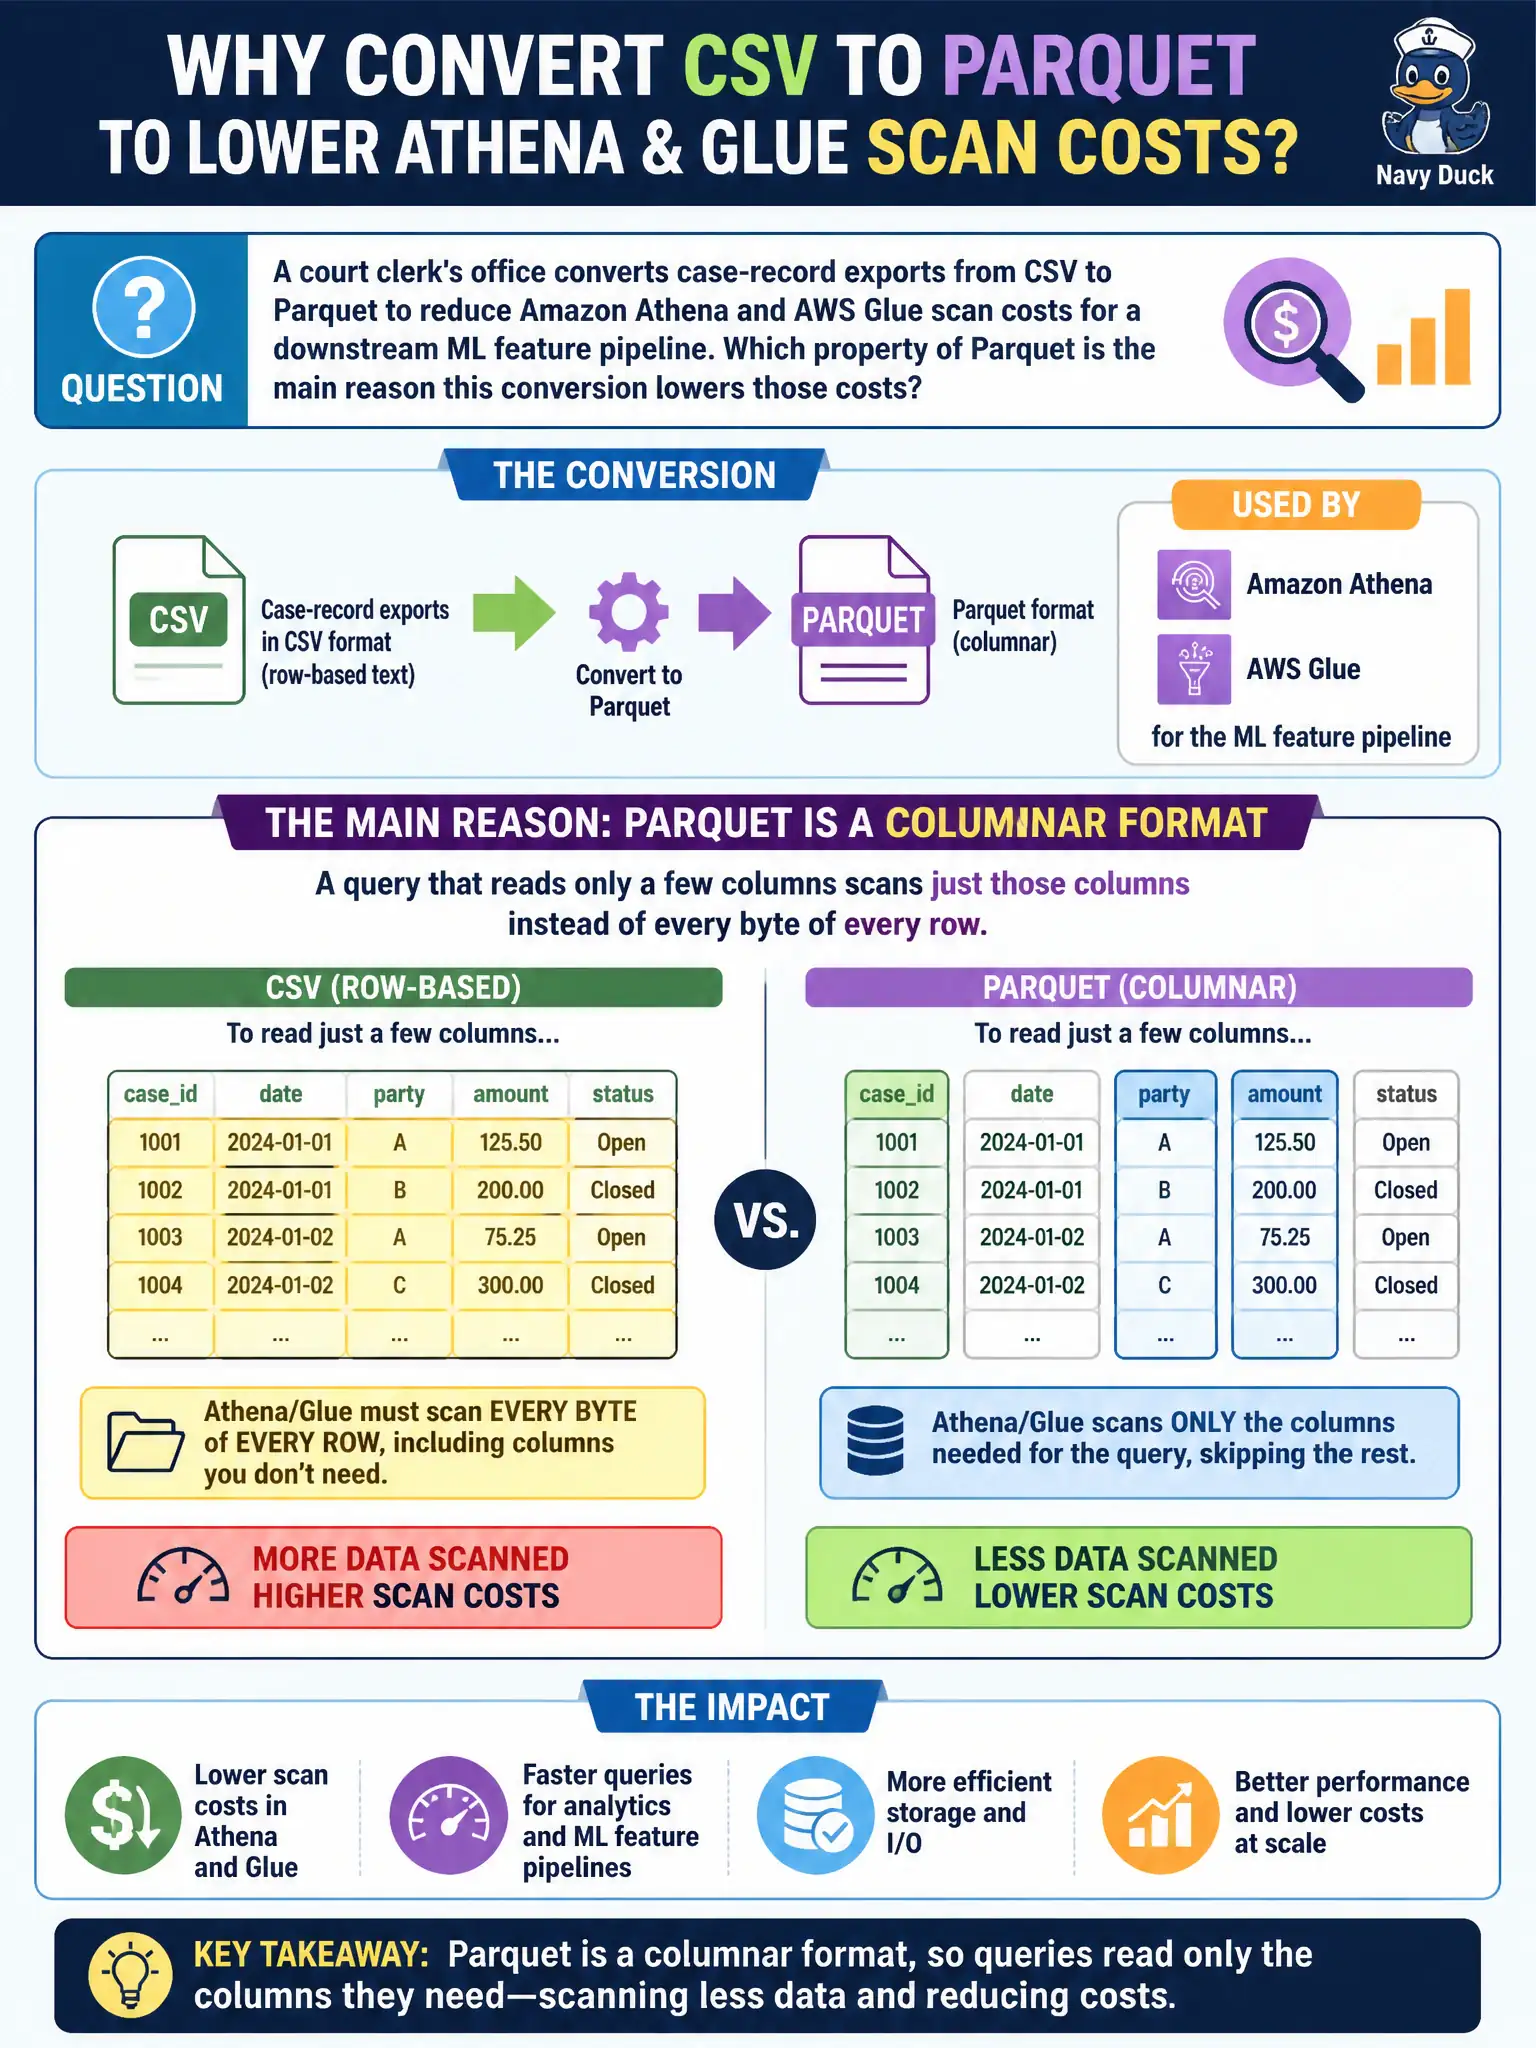
A court clerk's office converts case-record exports from CSV to Parquet to reduce Amazon Athena and AWS Glue scan costs for a downstream ML feature pipeline. Which property of Parquet is the main reason this conversion lowers those costs?
Select an answer to reveal the explanation.
Short Explanation
Think of CSV like a phone book you have to read cover to cover to find every area code, while Parquet is that same phone book pre-sorted into separate stacks by column — area codes in one stack, names in another. Athena and Glue only pay for the bytes they actually scan, so when a query needs three columns out of twenty, a columnar format lets them skip the other seventeen entirely. That's where the cost savings come from, not from encryption or file parsing tricks.
Full Explanation
Athena and Glue price by bytes scanned, and Parquet's columnar layout groups each column's values together on disk, so a query selecting a handful of columns can skip reading the rest — a dramatic reduction compared to CSV, where every row must be read in full because all columns for a record sit together. That's the mechanism behind the reported cost drop. Describing Parquet as JSON-based misidentifies the format entirely; Parquet is a binary columnar format, not a text-based row format like JSON, and the parses-it-faster framing skips the actual columnar-scan mechanism that drives the savings. Attributing the savings to automatic encryption confuses two unrelated concerns — encryption at rest protects confidentiality and has no bearing on how many bytes a query scans or what that scan costs. Claiming Parquet removes the need for a Glue Data Catalog table gets the dependency backwards: Athena still needs a catalog table (built manually or via a Glue crawler) describing the schema and location, regardless of file format. Scope note: columnar savings are largest for wide tables and narrow, selective queries; a query that reads nearly every column sees less benefit. Operational check: compare the data-scanned metric Athena reports for the same query before and after the CSV-to-Parquet conversion.