
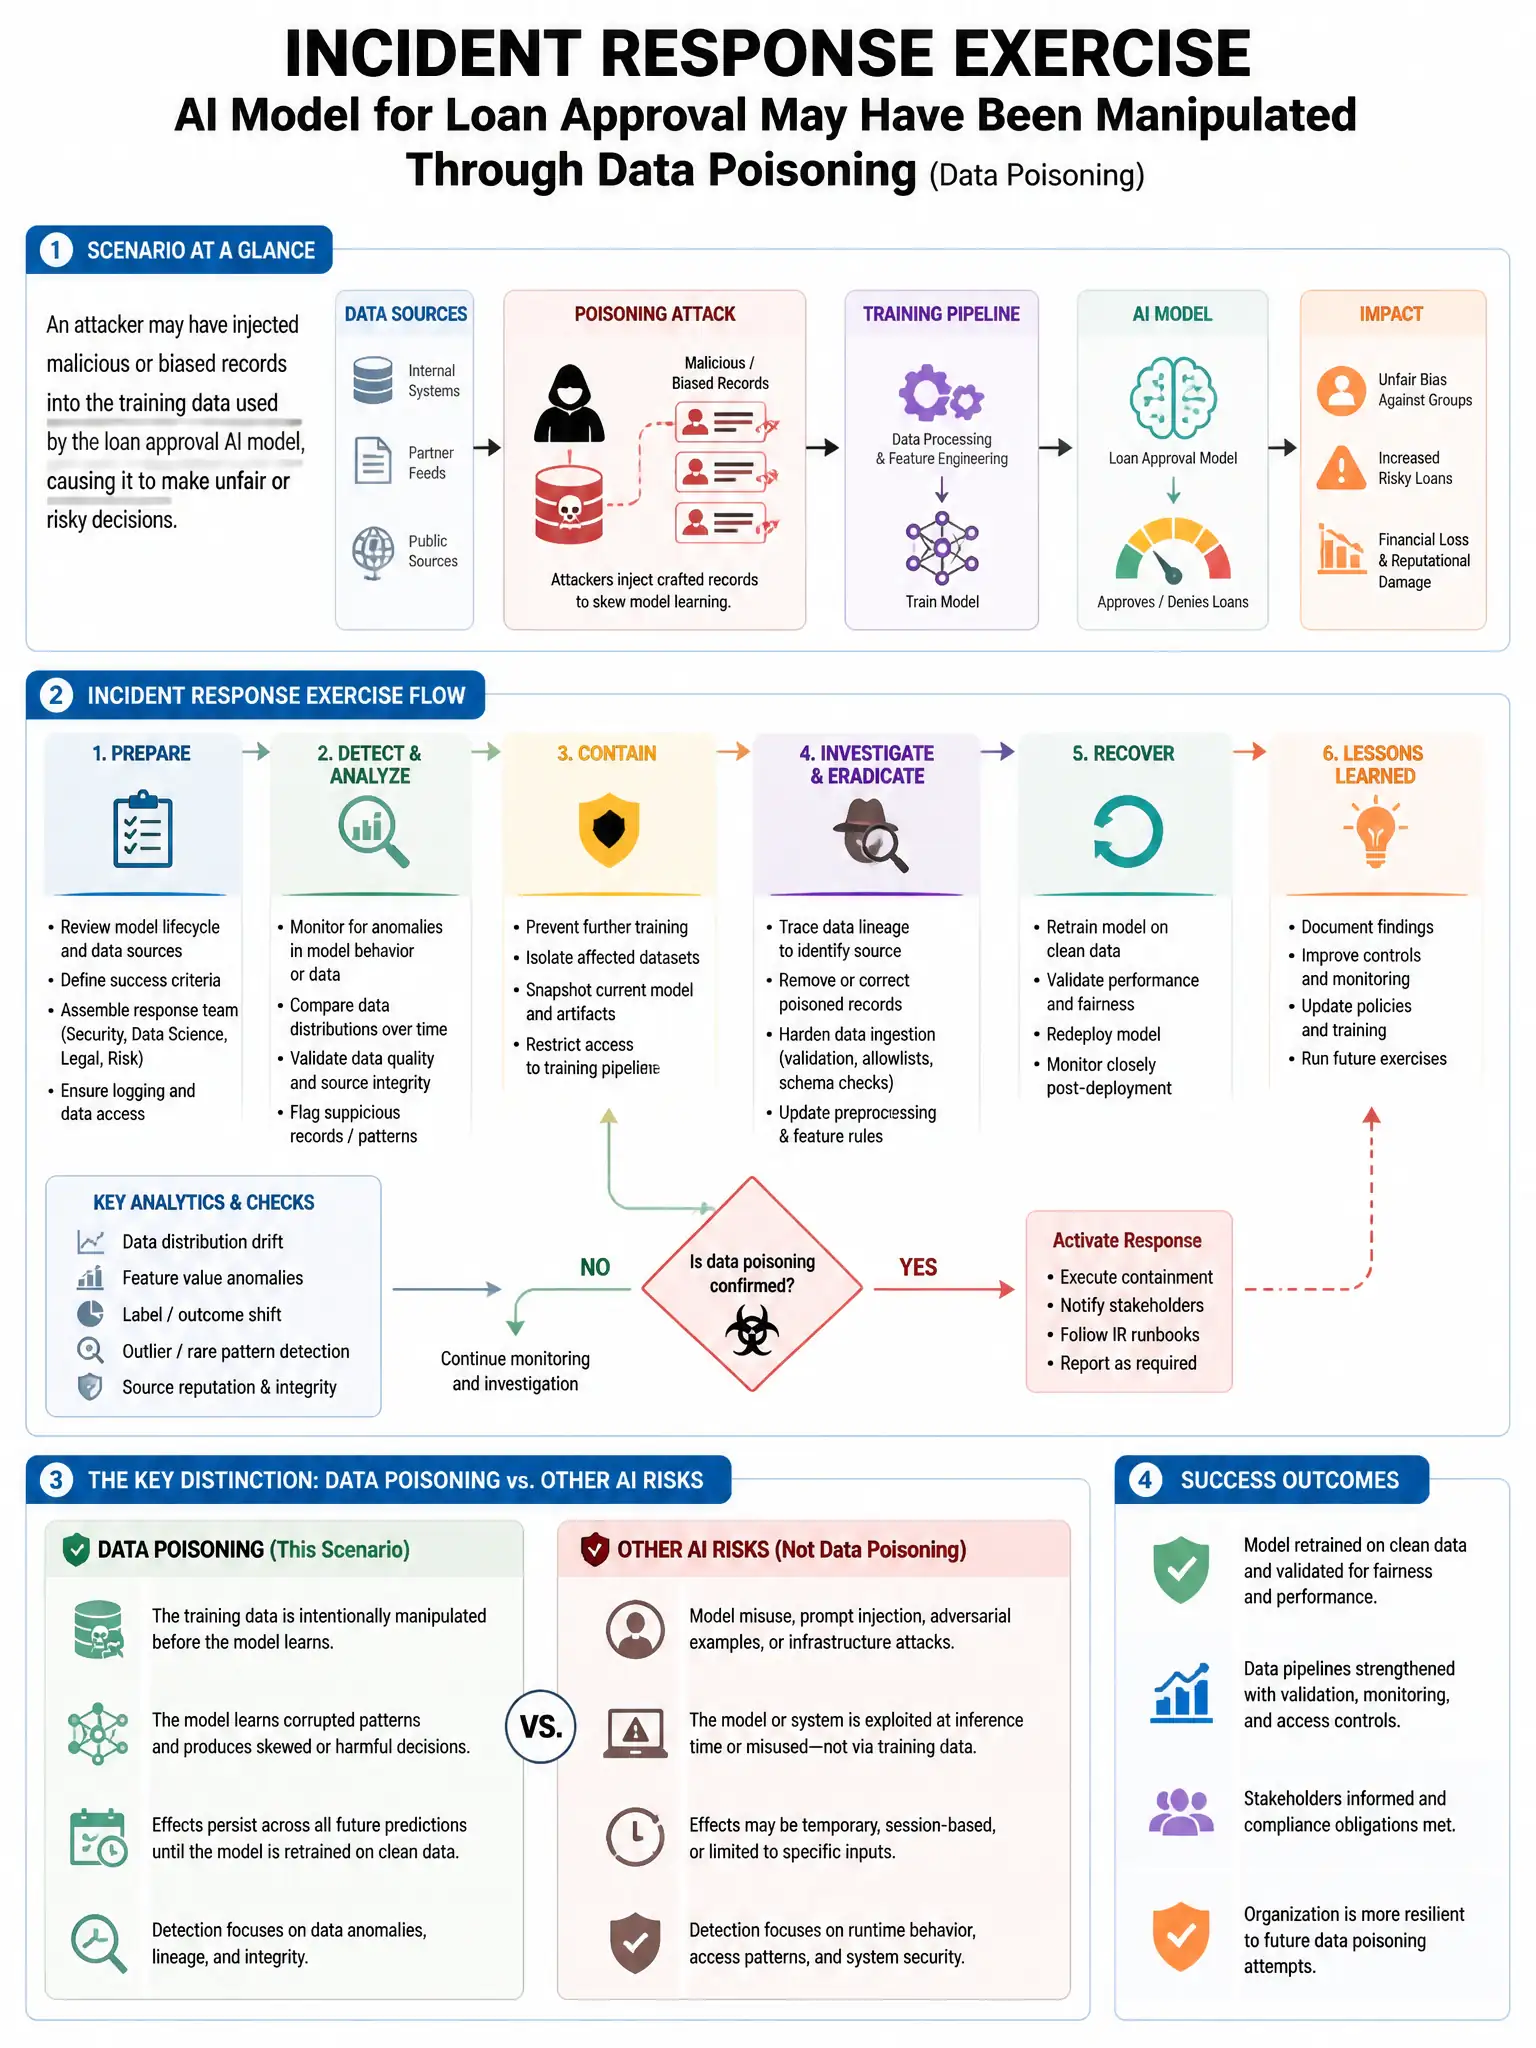
A security team is conducting an incident response exercise for a scenario where an organization's AI model used for loan approval may have been manipulated through data poisoning to approve fraudulent applications. Which artifact should the incident response team prioritize collecting to determine if poisoning occurred?
Select an answer to reveal the explanation.
Short Explanation
Data poisoning happens when bad data gets into the training set, so you need the Azure Machine Learning training run logs, dataset version history, and data validation pipeline logs. Those show what data was used, what changed, and whether validation failed before the last retraining.
Full Explanation
The Azure Machine Learning training run logs, dataset version history, and data validation pipeline logs are correct because data poisoning attacks occur during the model training process by introducing malicious data into the training dataset. To investigate, the incident response team must review the Azure Machine Learning training run logs to identify what data was used in each training iteration, the dataset version history in the AML data assets registry to identify when and what changed in the training data, and the data validation pipeline logs to find if validation was bypassed or failed. These artifacts provide the forensic trail to determine whether poisoned data was introduced before the retraining that produced the suspect model. The Azure Firewall logs for the training pipeline network traffic are wrong because they show network connectivity to the training pipeline, which may reveal unauthorized data uploads, but the model training run logs and dataset history are more directly informative for a data poisoning investigation. The Azure OpenAI API request and response logs for the loan approval endpoint are wrong because they capture inference-time interactions; data poisoning occurs at training time, not inference time. The Microsoft Entra ID sign-in logs for the model training compute cluster are wrong because they show who authenticated to the compute cluster, which is relevant for access investigation but does not directly reveal whether training data was poisoned.