
An organization is designing a Zero Trust architecture for an internal AI assistant built on Azure OpenAI Service. The AI assistant processes confidential business data. Which Zero Trust principle is most critical to apply when a user request reaches the AI inference layer?
Select an answer to reveal the explanation.
Short Explanation
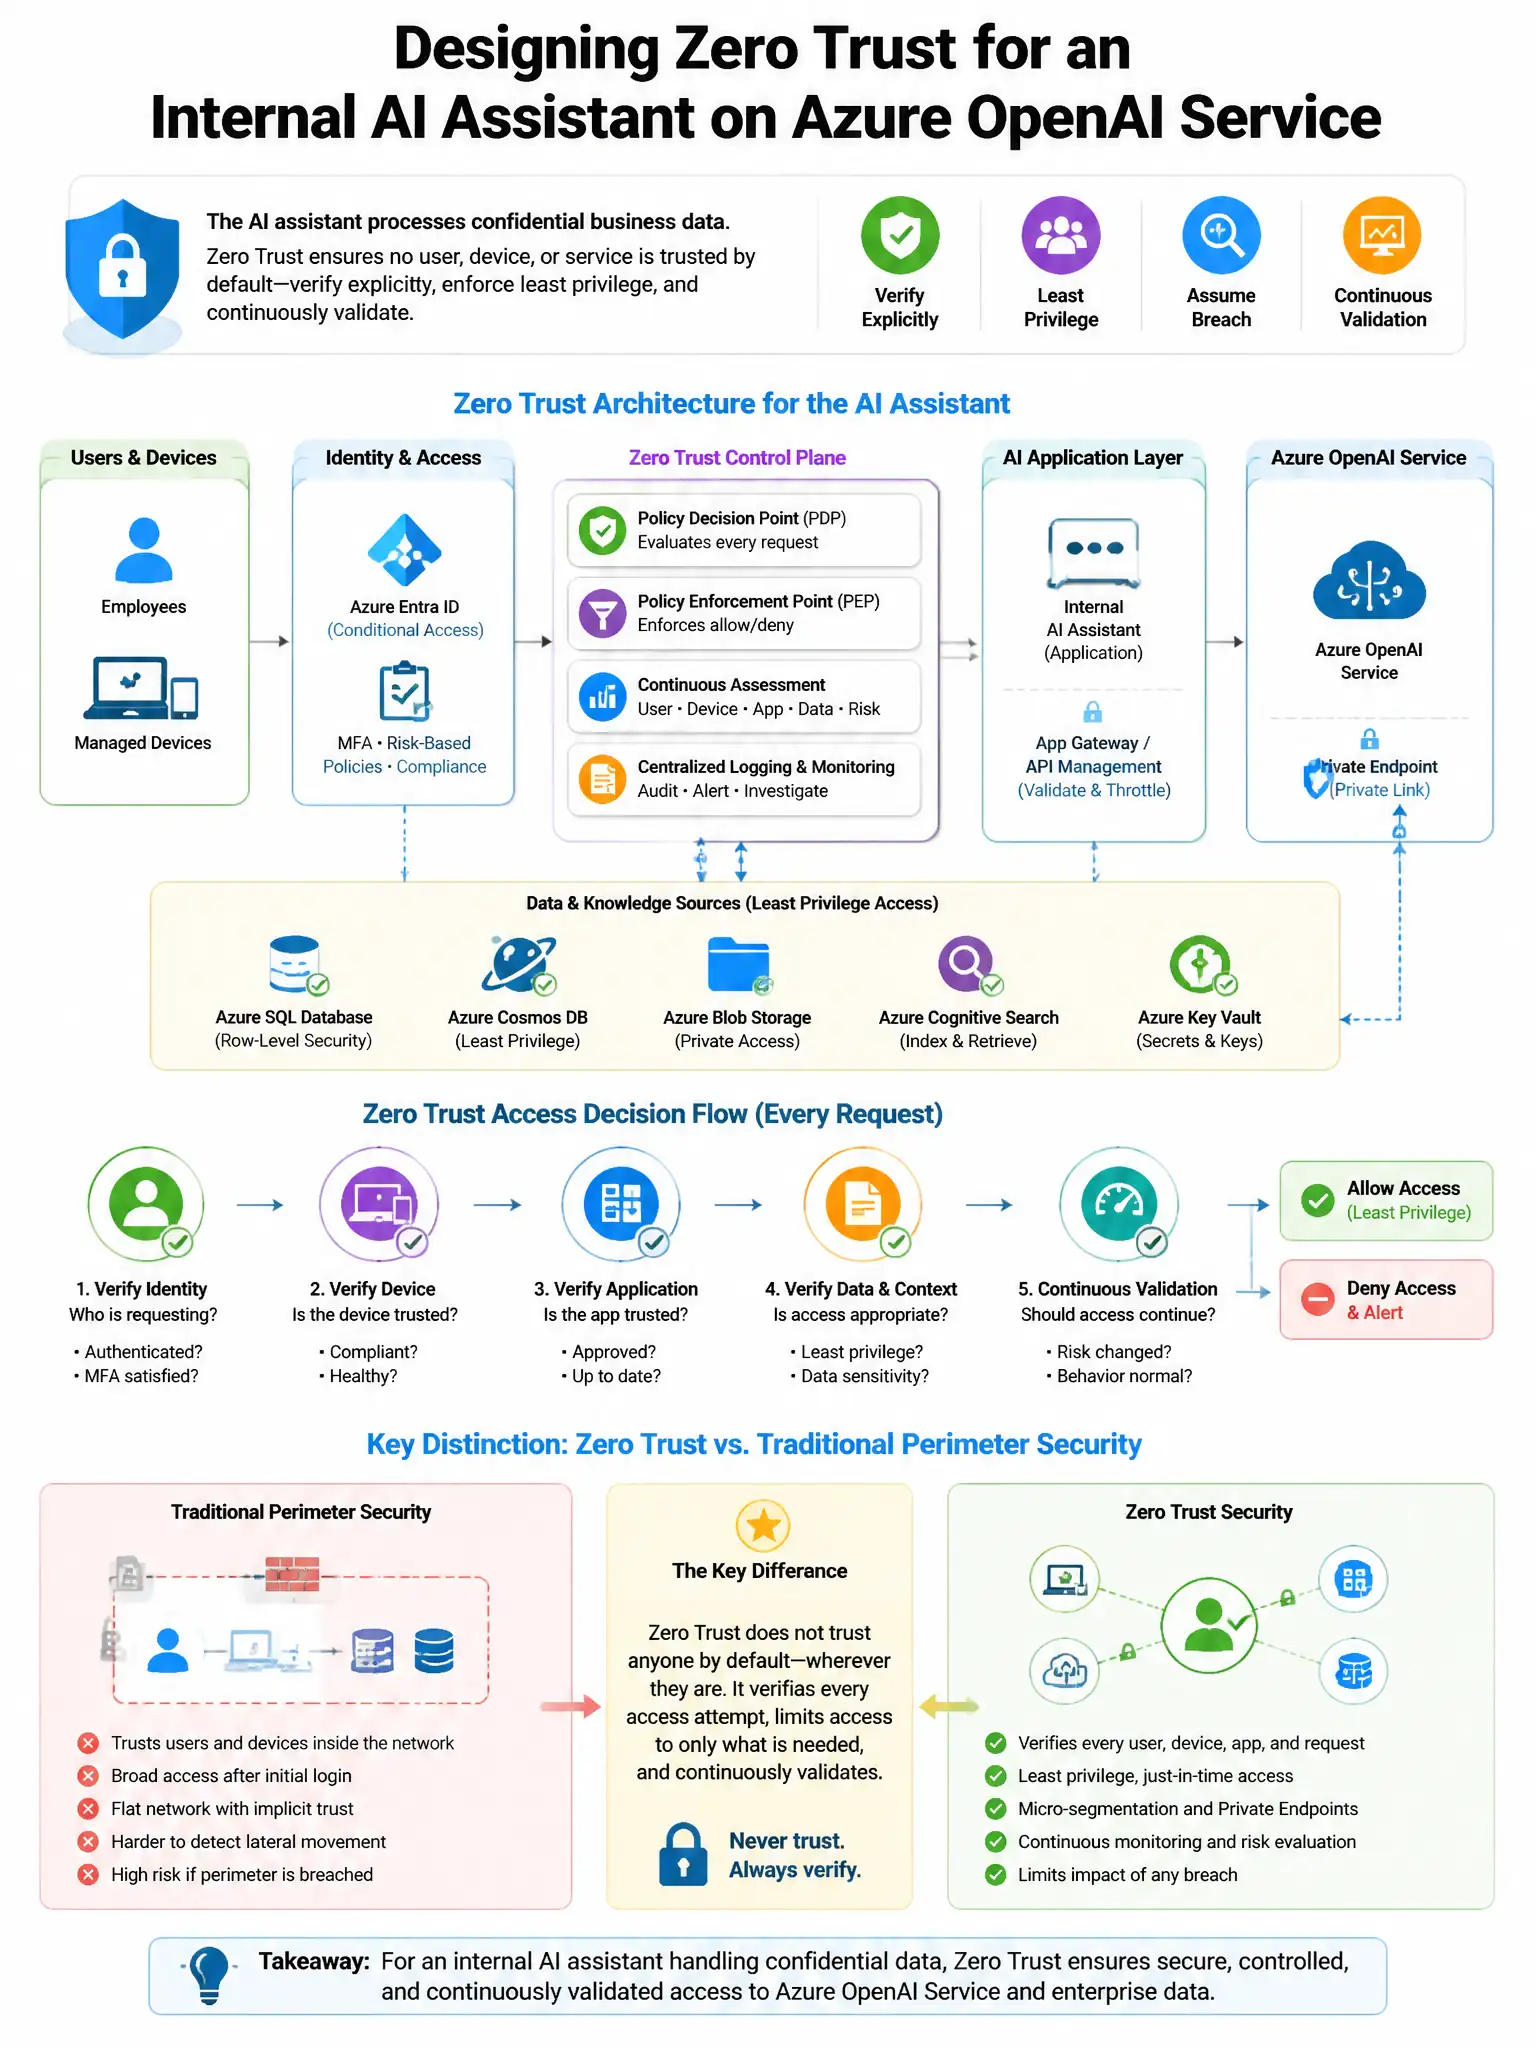
Here's the deal — you need to assume breach at the AI inference layer. Treat every request as potentially malicious, validate the Entra ID token on every call, enforce scope to authorized models/deployments, and use content validation like prompt shield to catch injection attacks.
Full Explanation
The correct choice is the option that applies the Zero Trust 'Assume breach' principle by treating all inference requests as potentially malicious and validating tokens, scope, and content on every request. At the AI inference layer, this means continuously validating the caller's Entra ID token on every request, enforcing scope restrictions to authorized models/deployments, and applying content validation such as prompt shield to catch injection attacks. This is in contrast to implicit trust granted after network perimeter authentication. The option that says verify explicitly but authenticate only the user's identity at the edge and trust all downstream AI calls is wrong because it violates Zero Trust by creating a trusted interior zone. The option that says use least privilege but assign all users read access to all models within the deployment is wrong because it violates the 'Use least privilege' principle—the principle means granting minimum necessary access, not universal access. The option that says assume breach but allow all requests from the corporate network without additional validation is wrong because trusting all corporate network traffic is the legacy perimeter model and directly contradicts the 'Assume breach' principle of Zero Trust.