
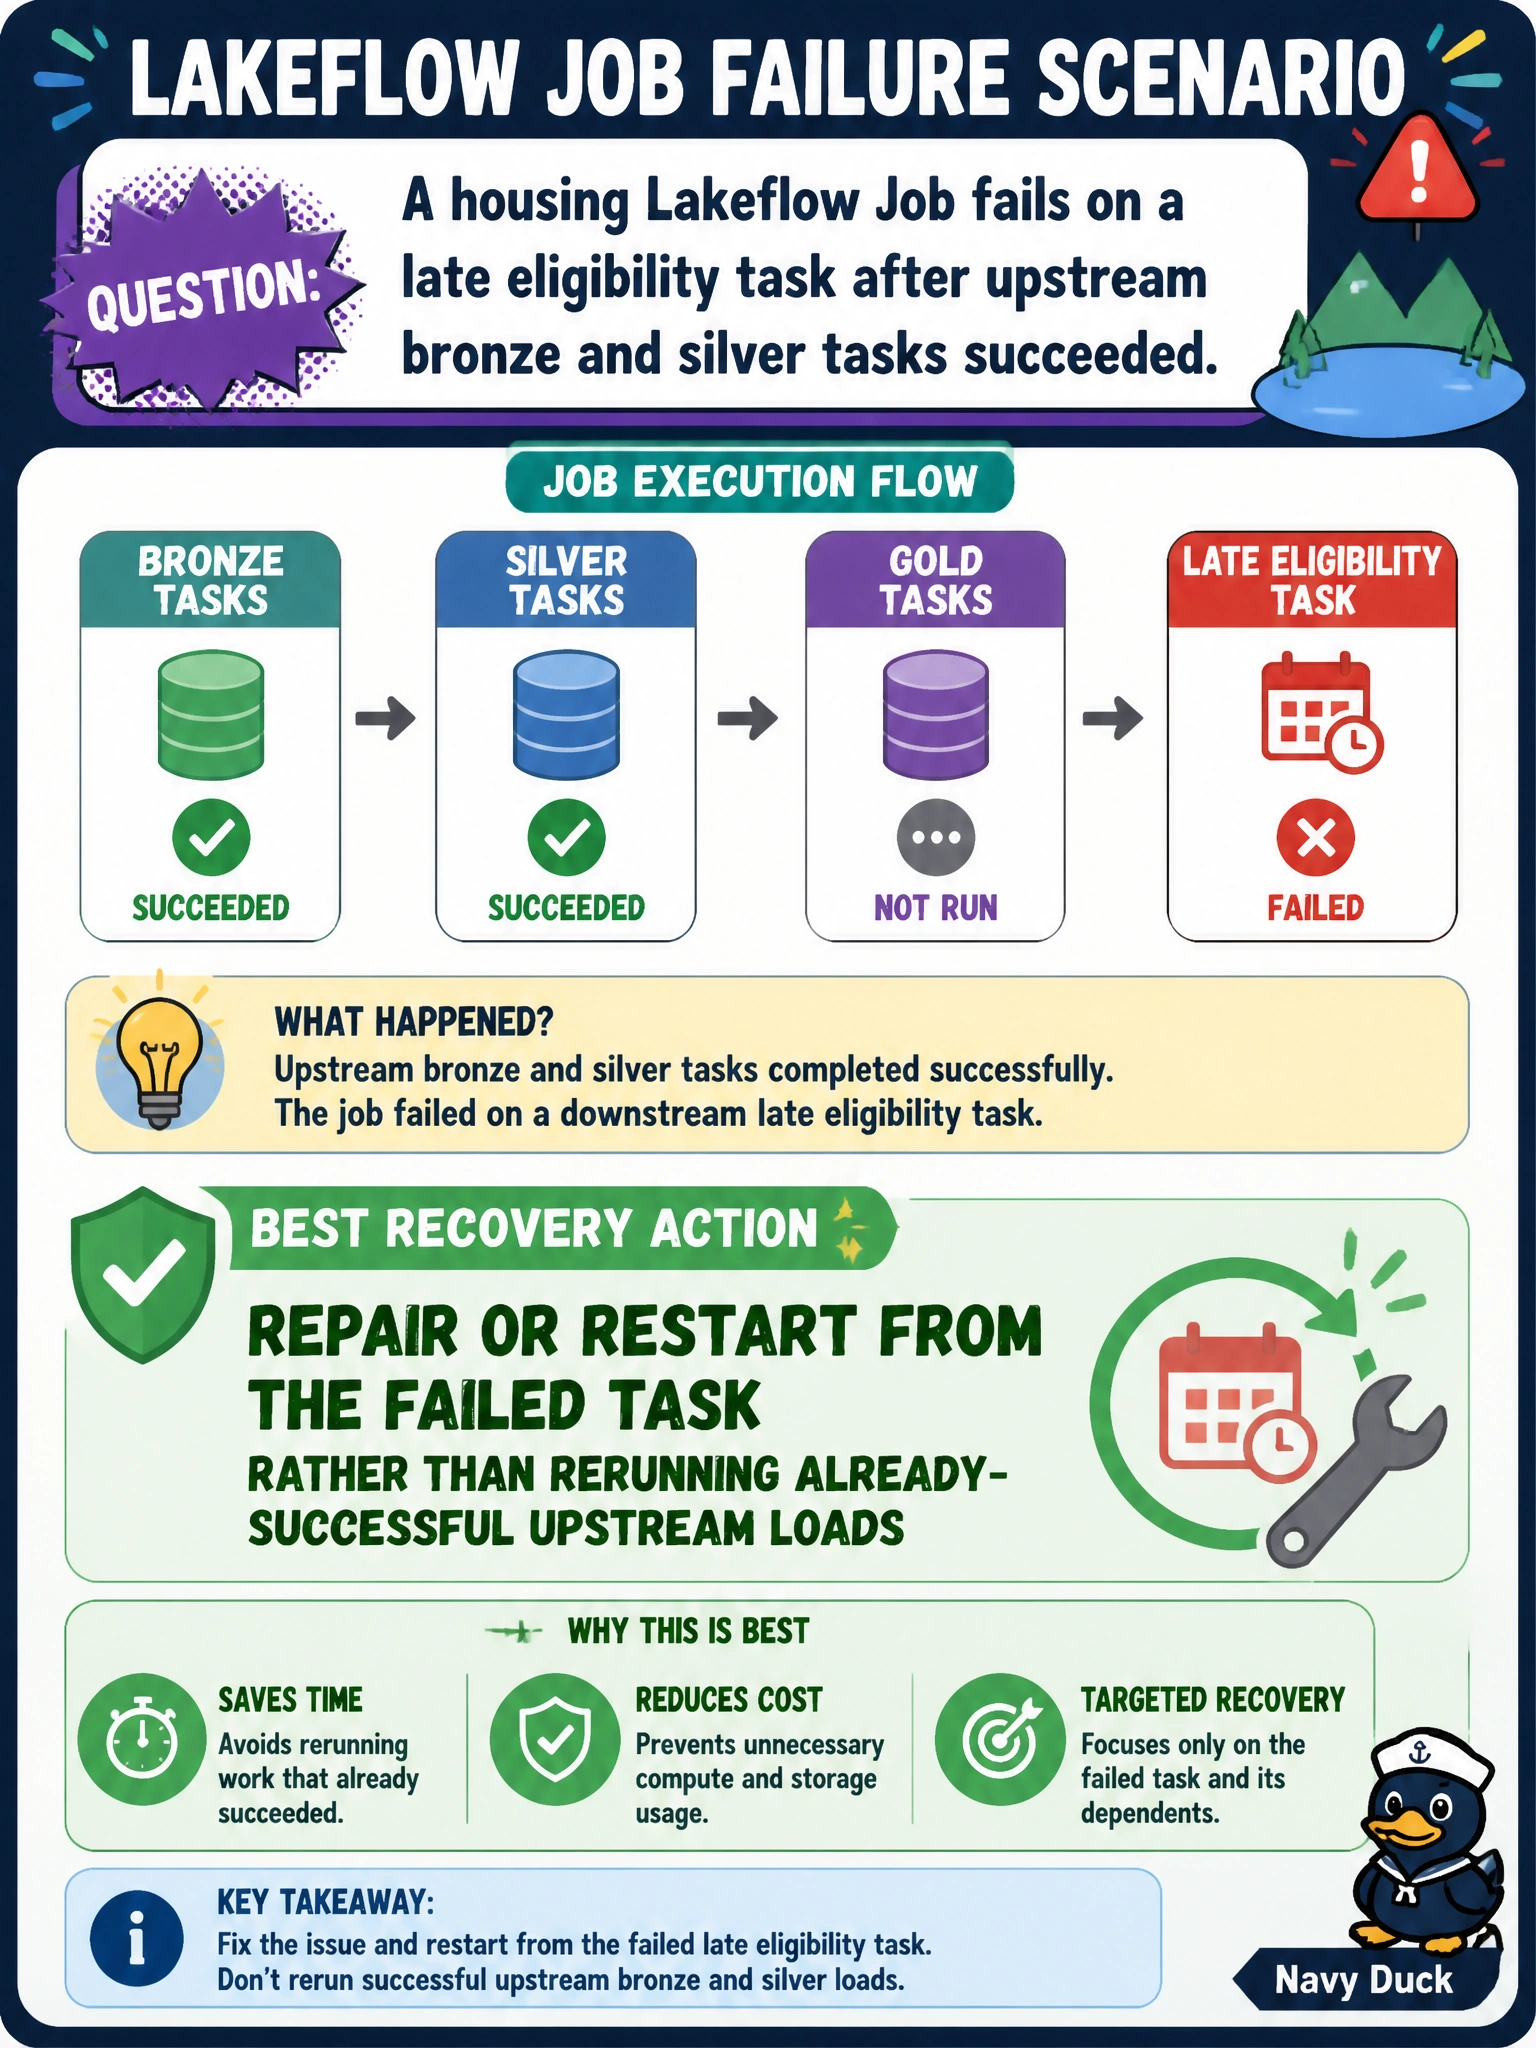
A housing Lakeflow Job fails on a late eligibility task after upstream bronze and silver tasks succeeded. What recovery action fits best?
Select an answer to reveal the explanation.
Short Explanation
Don't re-mow the whole lawn when the last strip failed — you've got good upstream cuts, so you'll repair from the broken task and leave them alone. You'll get clean history without resetting checkpoints, cloning runs, or forcing a full refresh.
Full Explanation
When a housing Lakeflow Job fails on a late eligibility task after upstream bronze and silver tasks already succeeded, the best recovery is to repair or restart from the failed task rather than rerunning already-successful upstream loads. Lakeflow Jobs expose repair/restart controls precisely so municipal engineers can resume from the break point, preserve valid upstream outputs, and avoid duplicate side effects or wasted compute on bronze and silver stages that already completed correctly. Repairing and rerunning the failed task while resetting bronze and silver checkpoints for consistency undermines the repair itself: bronze and silver already completed cleanly, so wiping their checkpoints forces those stages to reprocess valid data unnecessarily, risking duplicates and wasted compute instead of simply resuming at the eligibility task that actually broke. Rerunning eligibility in a cloned job run rather than repairing the failed run to preserve history gets preservation backwards: repair keeps lineage and task state in the original run, while a clone fragments tracking, loses the successful bronze and silver context, and leaves the original failure unresolved instead of resuming it directly. Repairing and rerunning the eligibility task with full refresh enabled to ensure deterministic gold outputs adds unneeded heavy work: full refresh discards incremental state and forces wider reprocessing for determinism you already have from intact bronze and silver outputs, burning compute and time just to retry the one eligibility task that failed. Exam caveat: DP-750 recovery questions favor targeted repair/restart from the failed task over resetting upstream checkpoints, cloning runs for history, or adding full refresh for determinism. Operational check: use the job’s repair/restart from the failed eligibility task, confirm bronze and silver outputs remain intact, verify gold completes, and document that a full DAG replay was unnecessary.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.