
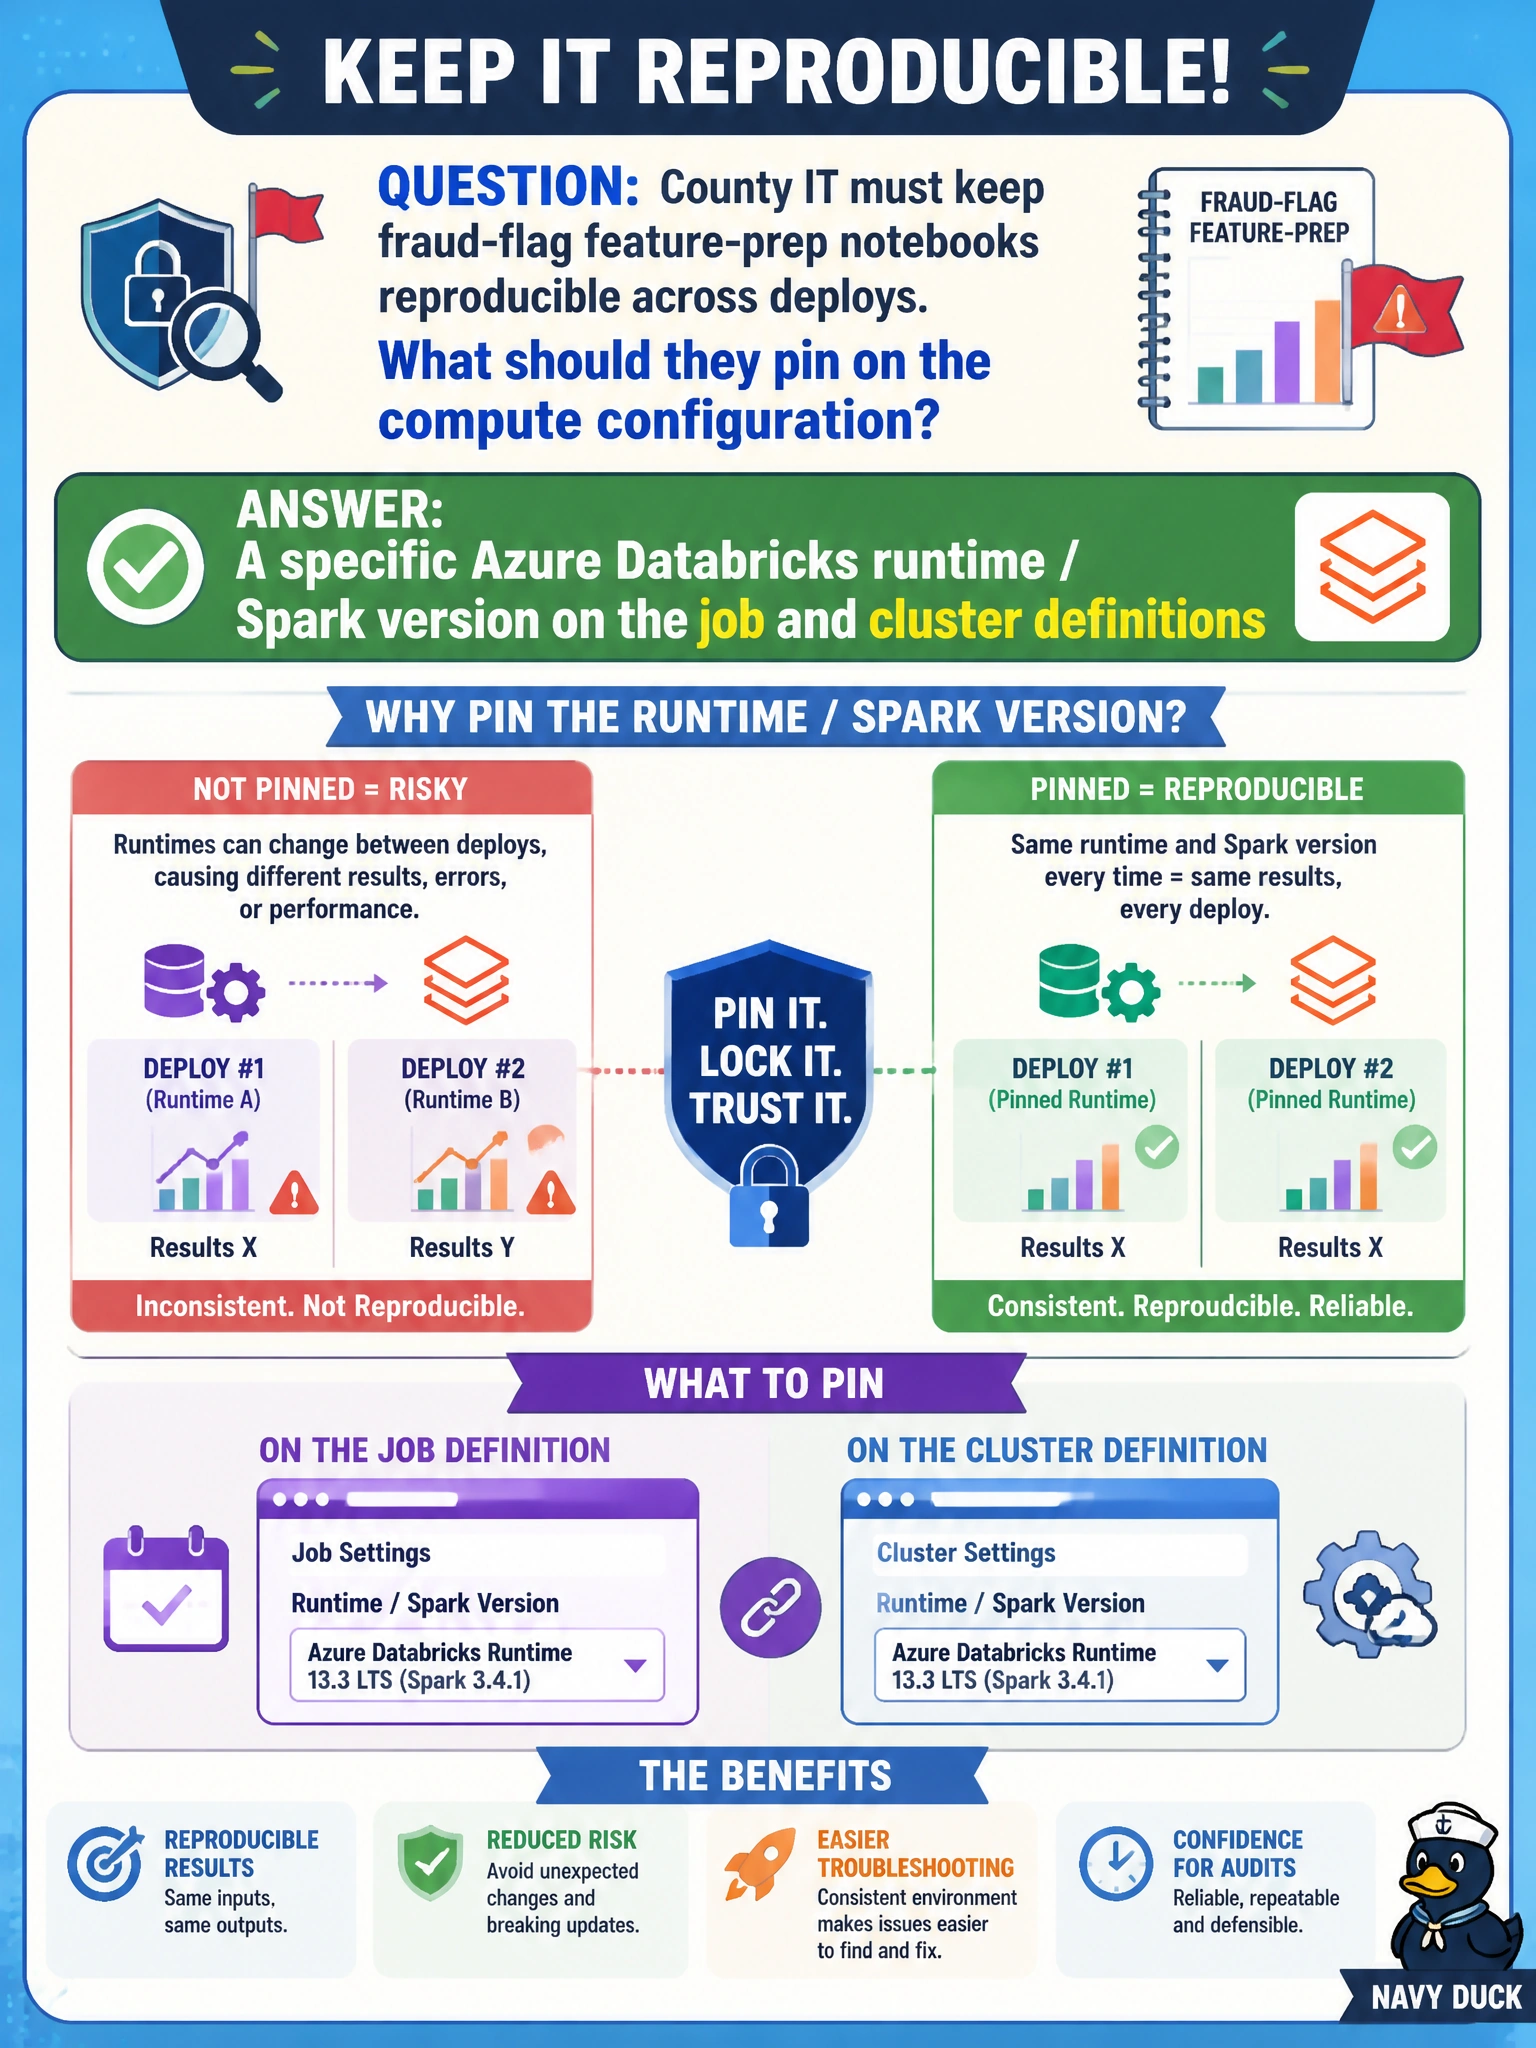
County IT must keep fraud-flag feature-prep notebooks reproducible across deploys. What should they pin on the compute configuration?
Select an answer to reveal the explanation.
Short Explanation
Pinning the runtime is like recording which recipe card the kitchen used—same Spark/Databricks version every deploy so fraud-flag prep does not silently change behavior. Pinning just the worker count and autoscaling range only controls how much you'll scale, so you'll still drift to different Spark behavior across deploys and you won't get reproducibility. Pinning just the driver and worker VM image SKU only locks the hardware size you've chosen, so it doesn't freeze the runtime and you haven't actually pinned the compute.
Full Explanation
County IT keeping fraud-flag feature-prep notebooks reproducible across deploys must pin a specific Azure Databricks runtime / Spark version on the job and cluster definitions. Runtime pinning freezes Spark, library defaults, and behavior so civic ML feature pipelines produce consistent outputs when promoted across environments; undocumented “whatever is current” runtimes are a common source of silent training/serving skew in government MLOps.
Pinning only a specific worker node count and autoscaling range on the job and cluster definitions controls parallelism and scale, not software behavior, so the Spark/Databricks runtime can still drift across deploys and break the reproducibility the stem requires. Pinning only a specific driver and worker Azure VM image SKU on the job and cluster definitions fixes the hardware family and size, not the Databricks runtime/Spark version, so engine behavior and library defaults can still change after a refresh and the stem's compute-configuration reproducibility requirement remains unmet. Pinning only a specific cluster auto-terminate timeout and retry policy on the job and cluster definitions governs idle shutdown and retry resilience, not what software executes, so it does not freeze Spark behavior and fails the same reproducibility and pinning requirement as leaving the runtime unpinned.
Exam caveat: pin both interactive (if used for promotion testing) and job compute definitions to the same tested LTS/runtime where policy allows; mismatch between notebook exploratory runtime and job runtime is a frequent exam trap. Preview channels can appear in distractors—prefer specified supported runtimes for production. Libraries and Spark configs should also be declared, but the stem asks specifically what to pin on compute configuration: the runtime/Spark version.
Operational check: set an explicit spark_version / runtime in cluster policies and job cluster JSON for fraud-flag prep, record that version in change tickets, block interactive attaches from drifting via policy, and re-validate features when intentionally upgrading runtimes.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.