
A team is building a document search feature for a Foundry-hosted assistant: articles from the internal wiki need to be converted into vectors and stored in a vector database so the assistant can retrieve semantically similar passages at query time. Which type of model should generate those vectors?
Select an answer to reveal the explanation.
Short Explanation
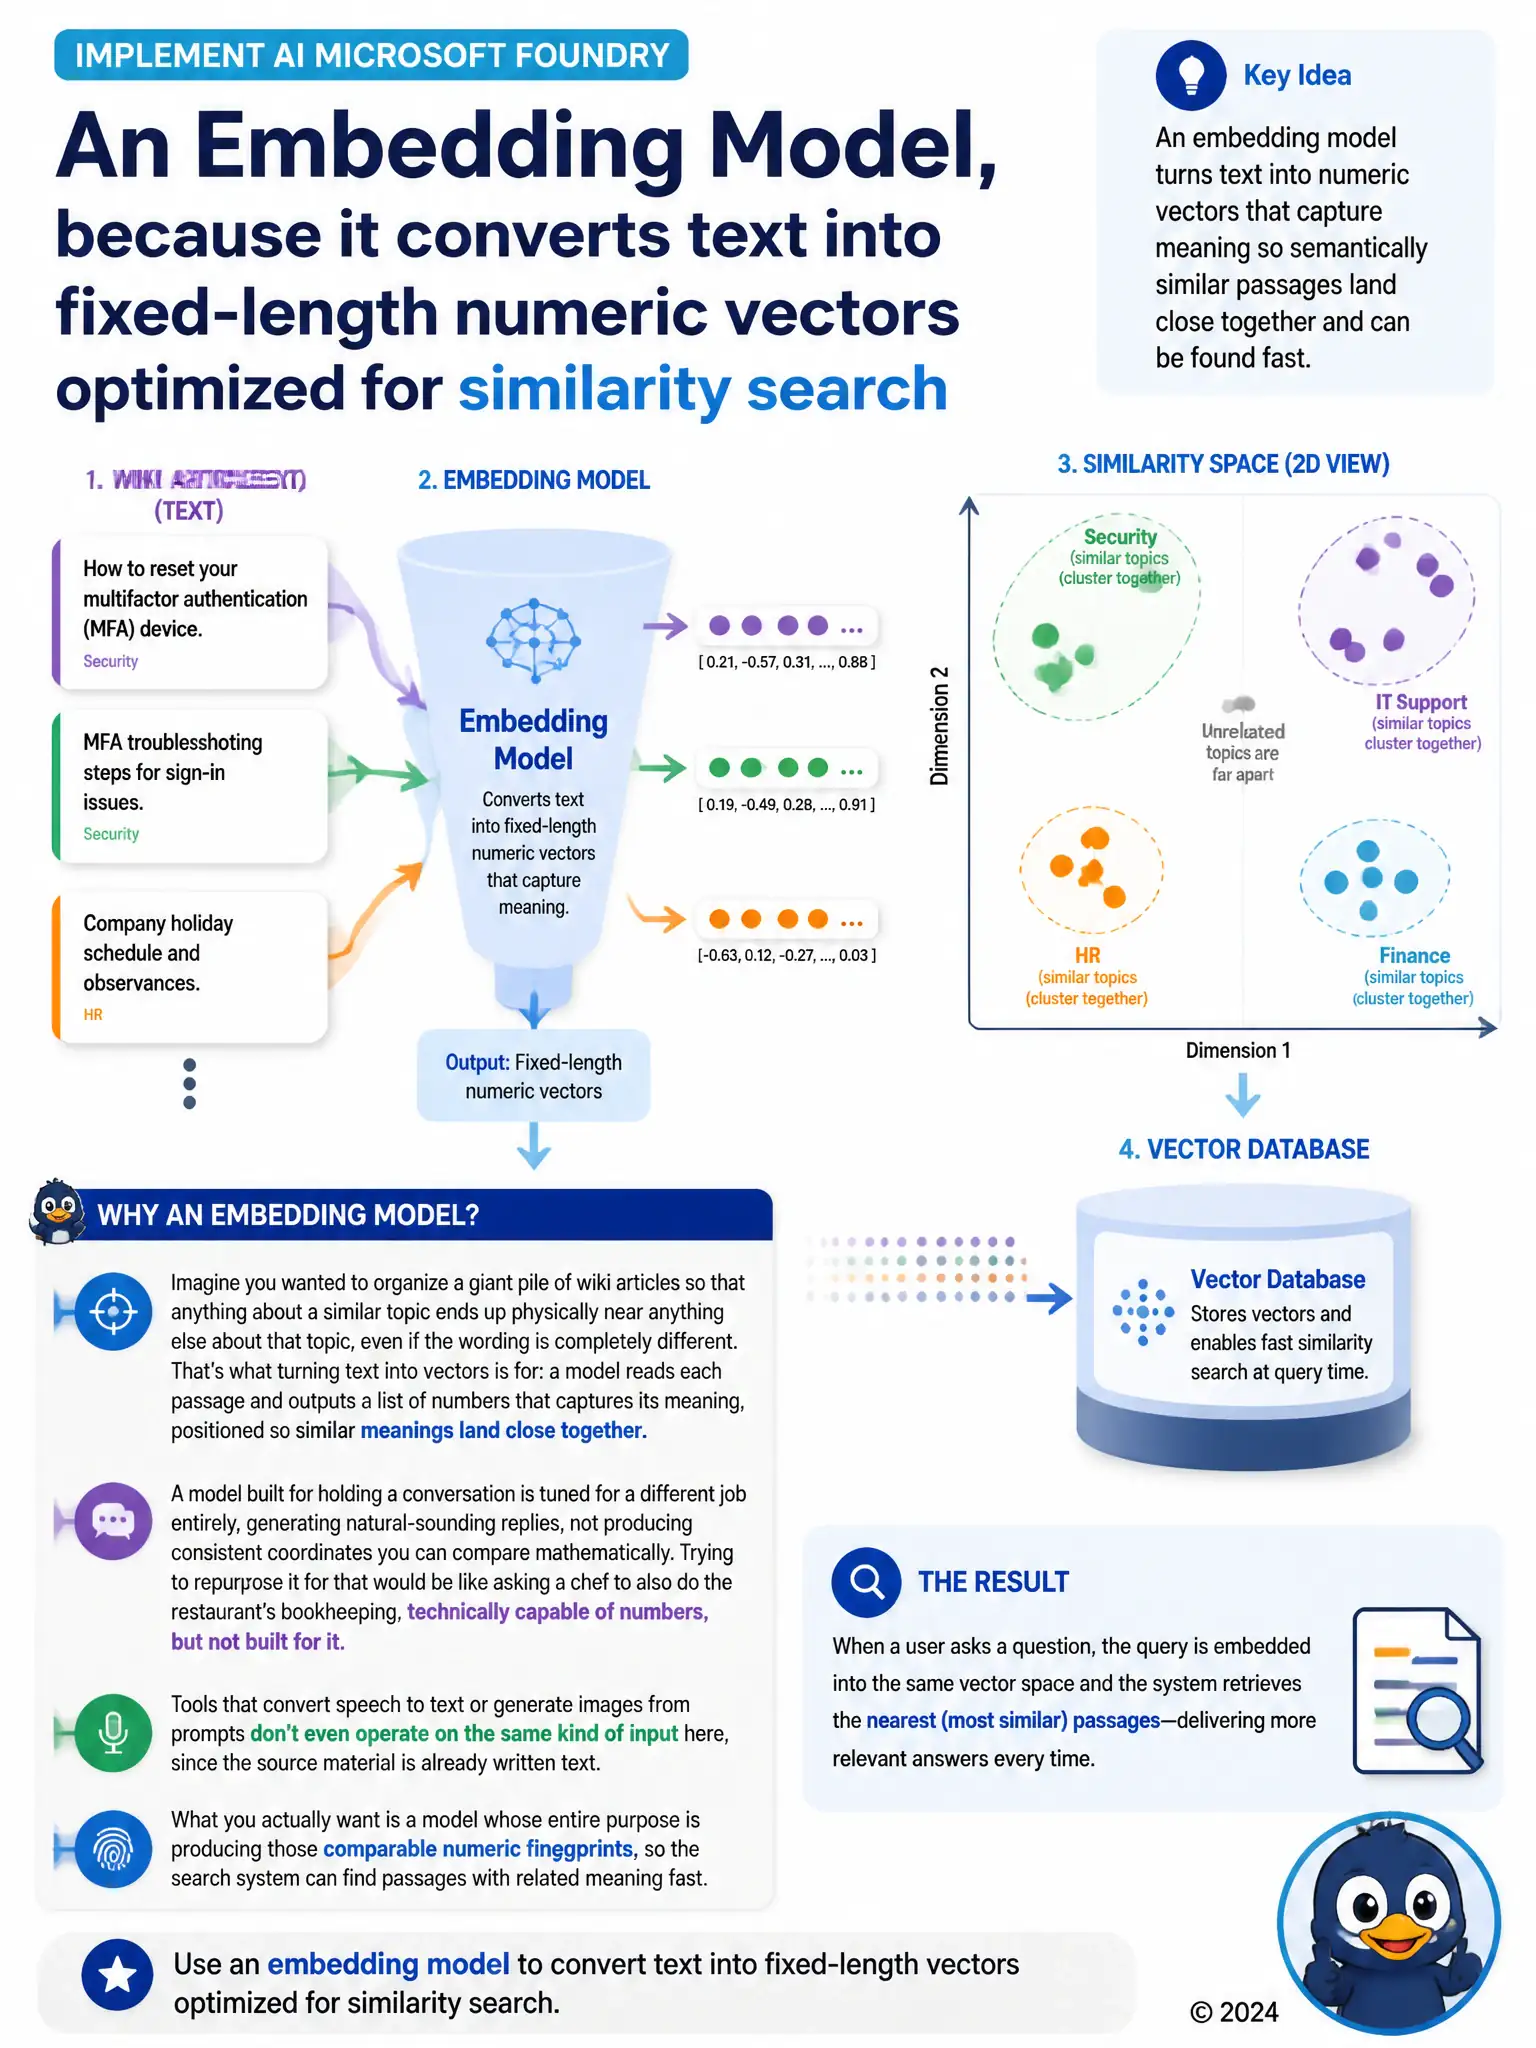
You want an embedding model here because it converts text into fixed-length numeric vectors that a vector database can compare for semantic similarity. Chat, speech-to-text, and image models aren't built to produce those searchable numeric fingerprints.
Full Explanation
An embedding model is the right choice because it is built specifically to convert text into fixed-length numeric vectors positioned in a space where semantically similar passages sit close together, which is exactly what a vector database needs to support similarity search over the wiki articles. A chat completion model is incorrect because it is optimized to generate conversational text responses, not to produce the consistent, similarity-optimized numeric vectors a search index depends on; using its output for search would be unreliable and inefficient. A speech-to-text model is incorrect because it converts audio into text and has no role here, since the wiki articles are already written text that needs to be vectorized, not transcribed. An image generation model is incorrect because it produces pictures from prompts; it has no mechanism for representing text meaning as a searchable numeric vector and is irrelevant to a text-based document search feature. Because the goal is to enable semantic retrieval of similar passages at query time, the team needs a model purpose-built to translate meaning into comparable numeric form, which is precisely the role of an embedding model in this pipeline.