
A media company is choosing which model to use for a new Foundry-hosted summarization feature. Several candidate models in the model catalog could plausibly work, and the team wants to compare their quality, cost per token, and expected latency before committing engineering time to build against any single one. What should they do first?
Select an answer to reveal the explanation.
Short Explanation
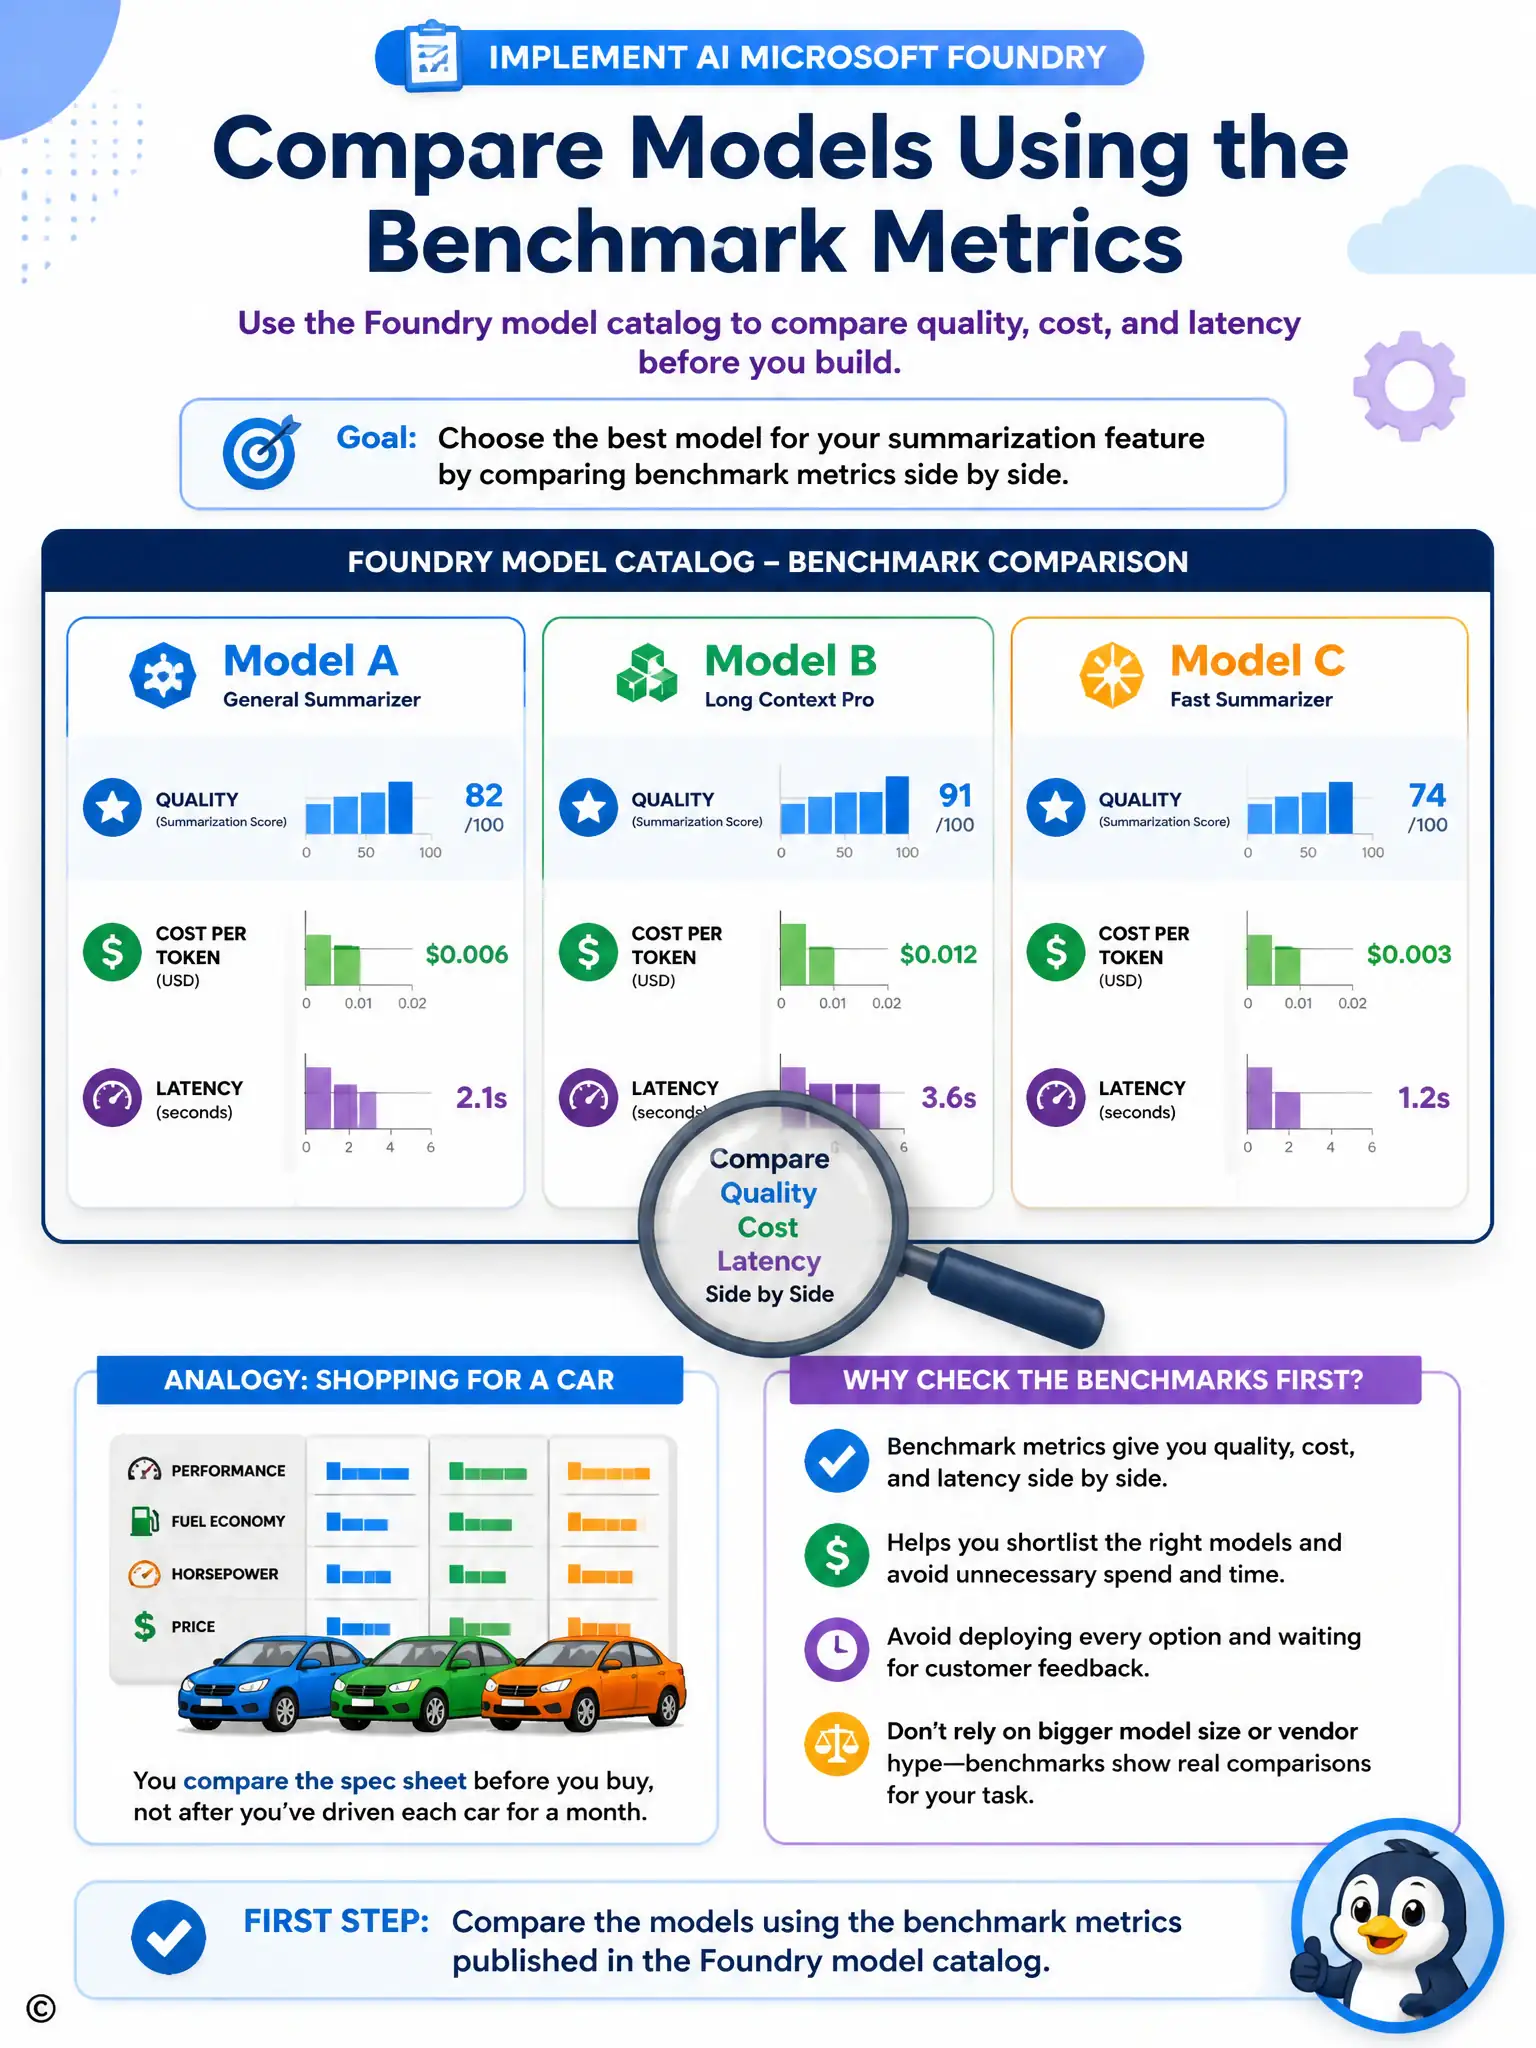
When you're shopping for a car, you don't buy five cars and drive each one for a month. You look at the spec sheet first. Use the model catalog's benchmark metrics to compare quality, cost, and latency before writing integration code.
Full Explanation
The best first step is comparing the models using the benchmark metrics published in the Azure AI Foundry model catalog. That catalog publishes quality scores, cost per token, and latency for many models side by side, letting the team compare candidates before writing integration code or spending on production traffic. This directly answers the stated need to evaluate options up front. Deploying every candidate model to production and monitoring customer feedback for a month is wrong because it is slow, expensive, and risks exposing real customers to a poorly suited model for weeks before a decision is made. Choosing the model with the largest published parameter count is wrong because parameter count alone does not reliably predict summarization quality, cost, or latency; smaller models are frequently competitive or superior on specific tasks. Relying on each vendor's marketing description of model capability is wrong because those descriptions are not independently verified and can overstate capability, whereas the catalog's benchmark data comes from consistent, comparable evaluation runs the team can inspect directly.