
A team's Foundry-hosted customer support assistant handles conversations that sometimes run to 40 or more back-and-forth turns. Testers notice that in very long conversations, the assistant starts giving generic answers and stops referencing details the customer mentioned near the start of the chat, even though those details are still relevant. What is the most likely cause of this behavior?
Select an answer to reveal the explanation.
Short Explanation
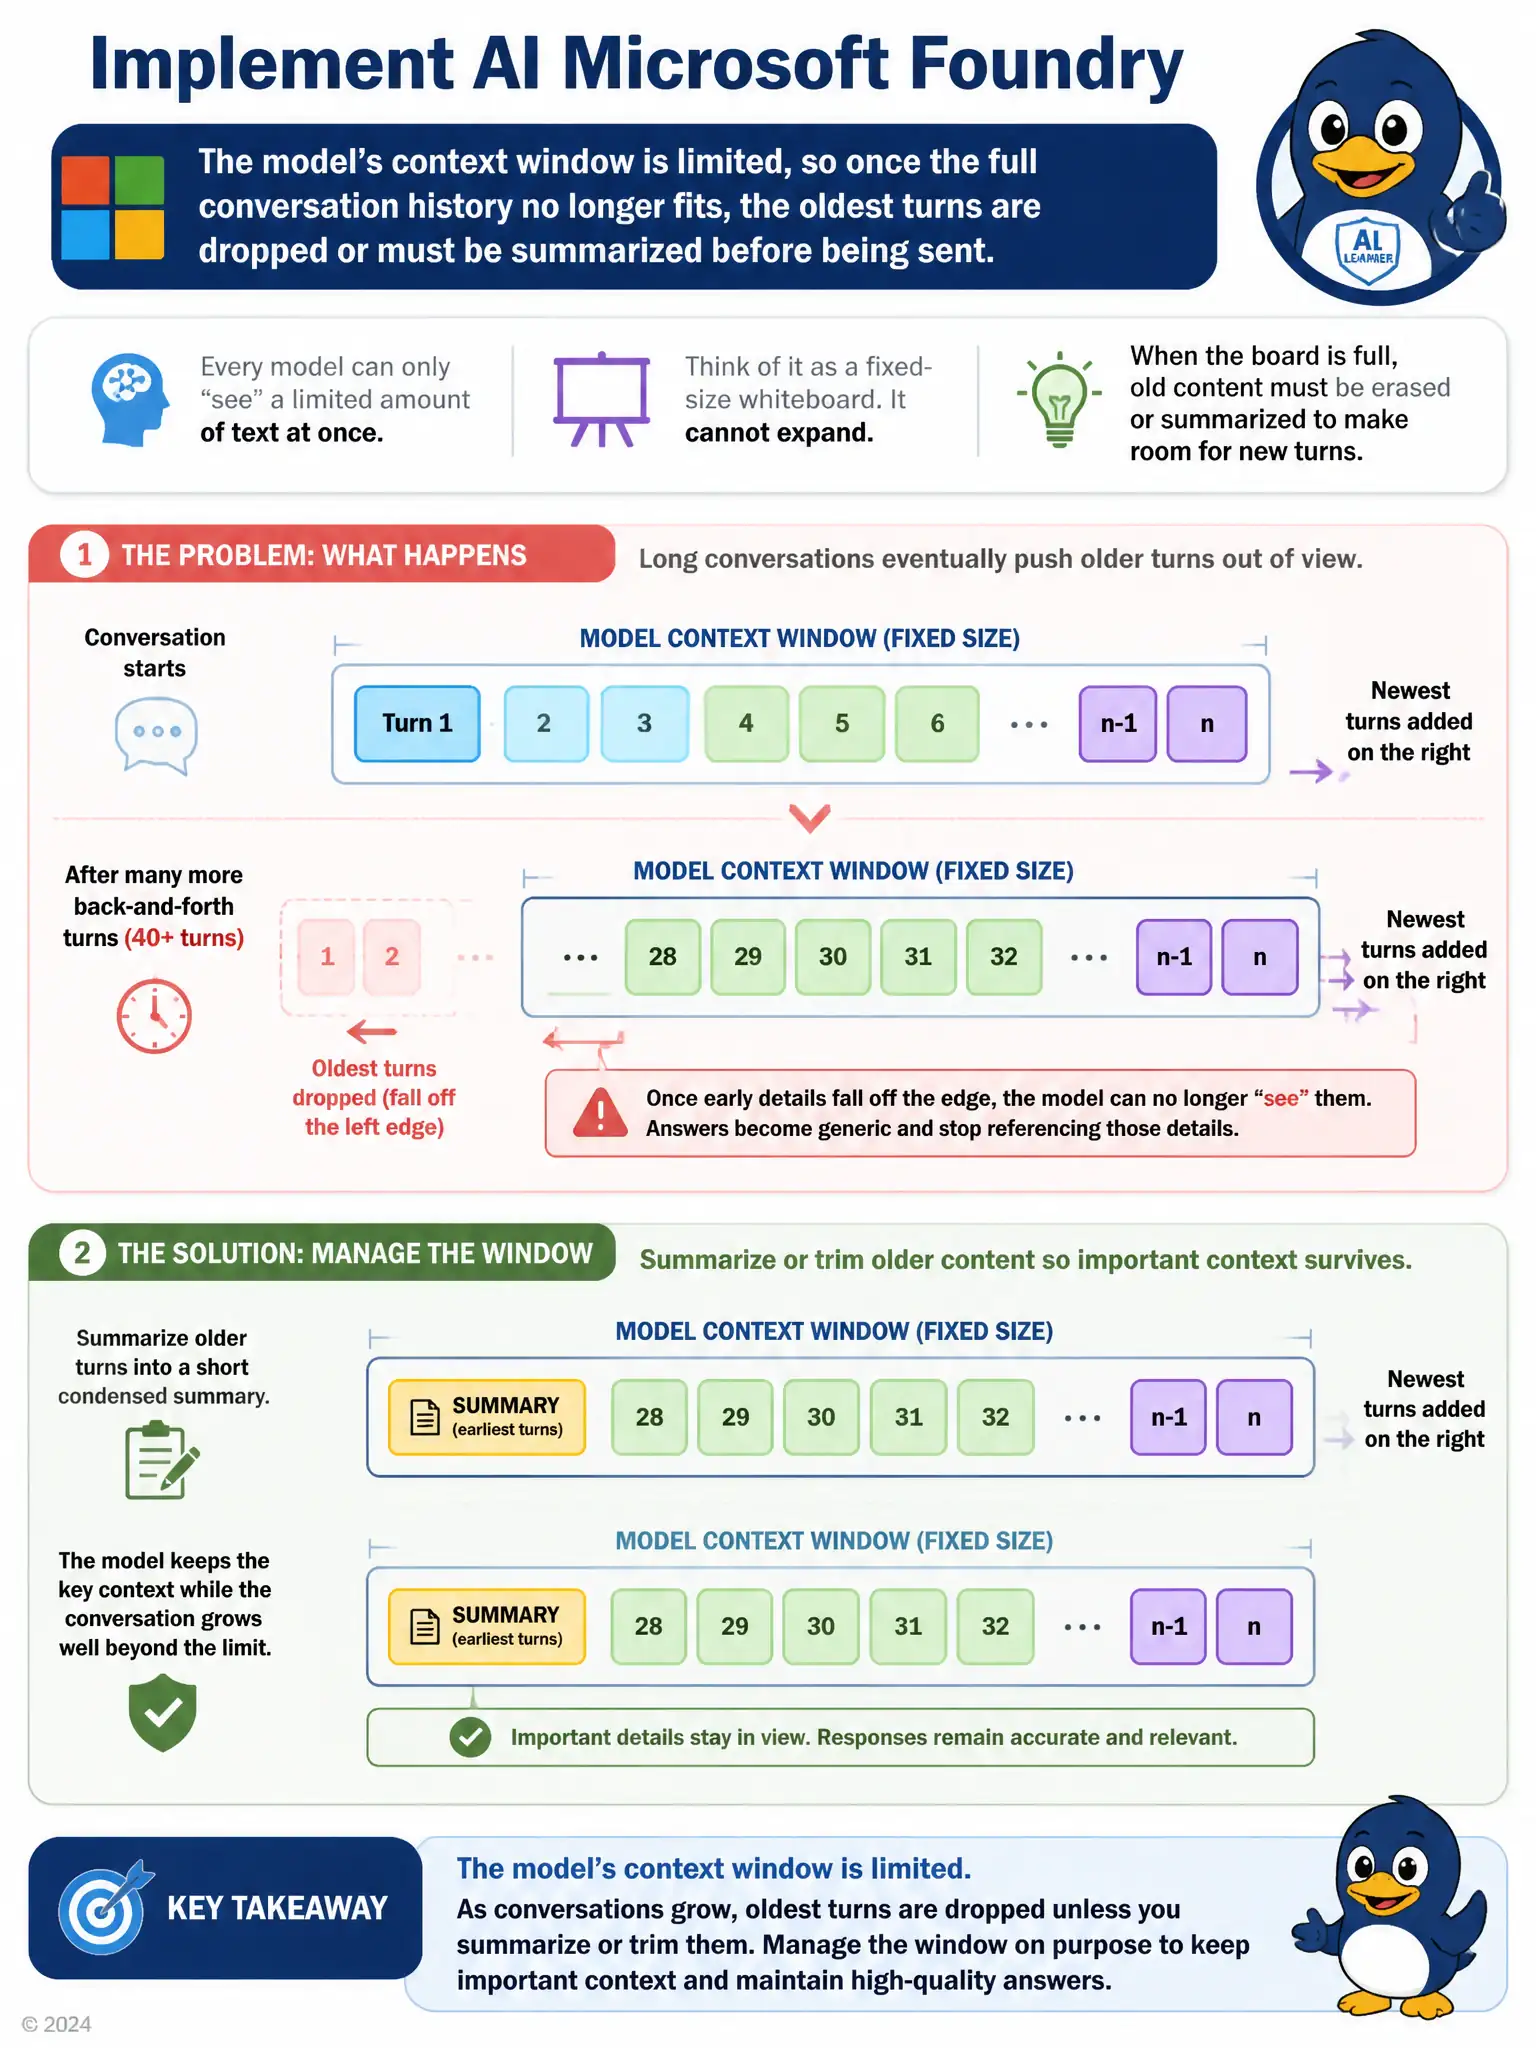
Every model can only 'see' a limited amount of text at once, like a fixed-size whiteboard. As the chat grows, the oldest turns get dropped or summarized to make room, so early details fall off and answers turn generic. You fix it by managing context on purpose, such as compressing older turns into a running summary.
Full Explanation
The likely cause is the model's limited context window. Every model has a fixed context window measured in tokens, and once a conversation's full history exceeds that window, the application or platform must drop or summarize earlier turns to fit the remaining ones in. That is why early customer details stop influencing later answers in very long support chats. The idea that the assistant randomly discards messages to comply with a hard-coded conversation length limit set by the developer is incorrect because nothing in the scenario suggests an intentional cap; the gradual loss of early detail as the chat grows is the signature of a token-budget limit, not an arbitrary cutoff rule. The idea that the assistant's system message was configured once at deployment and cannot be updated during a conversation is incorrect because the system message is a small, separate piece of the prompt that stays present regardless of conversation length; its static nature does not explain why turn-specific customer details disappear as the chat grows longer. The idea that the content filter is silently removing early customer messages that mention sensitive topics is incorrect because content filtering evaluates messages for policy violations and blocks or flags them; it does not selectively erase early conversation history based on topic sensitivity, and there is no indication the missing details were sensitive. The fix is to manage context proactively, for example by summarizing older turns into a condensed running summary or trimming least-relevant history, rather than assuming the platform will preserve everything indefinitely.