
A market-research firm needs to summarize 50,000 archived customer-interview transcripts stored in blob storage. The summaries are needed by tomorrow morning for a report, but no one needs any individual summary right away, and the firm wants to minimize the per-request cost of calling its Foundry-hosted model. Which deployment approach should the firm use to process the transcripts?
Select an answer to reveal the explanation.
Short Explanation
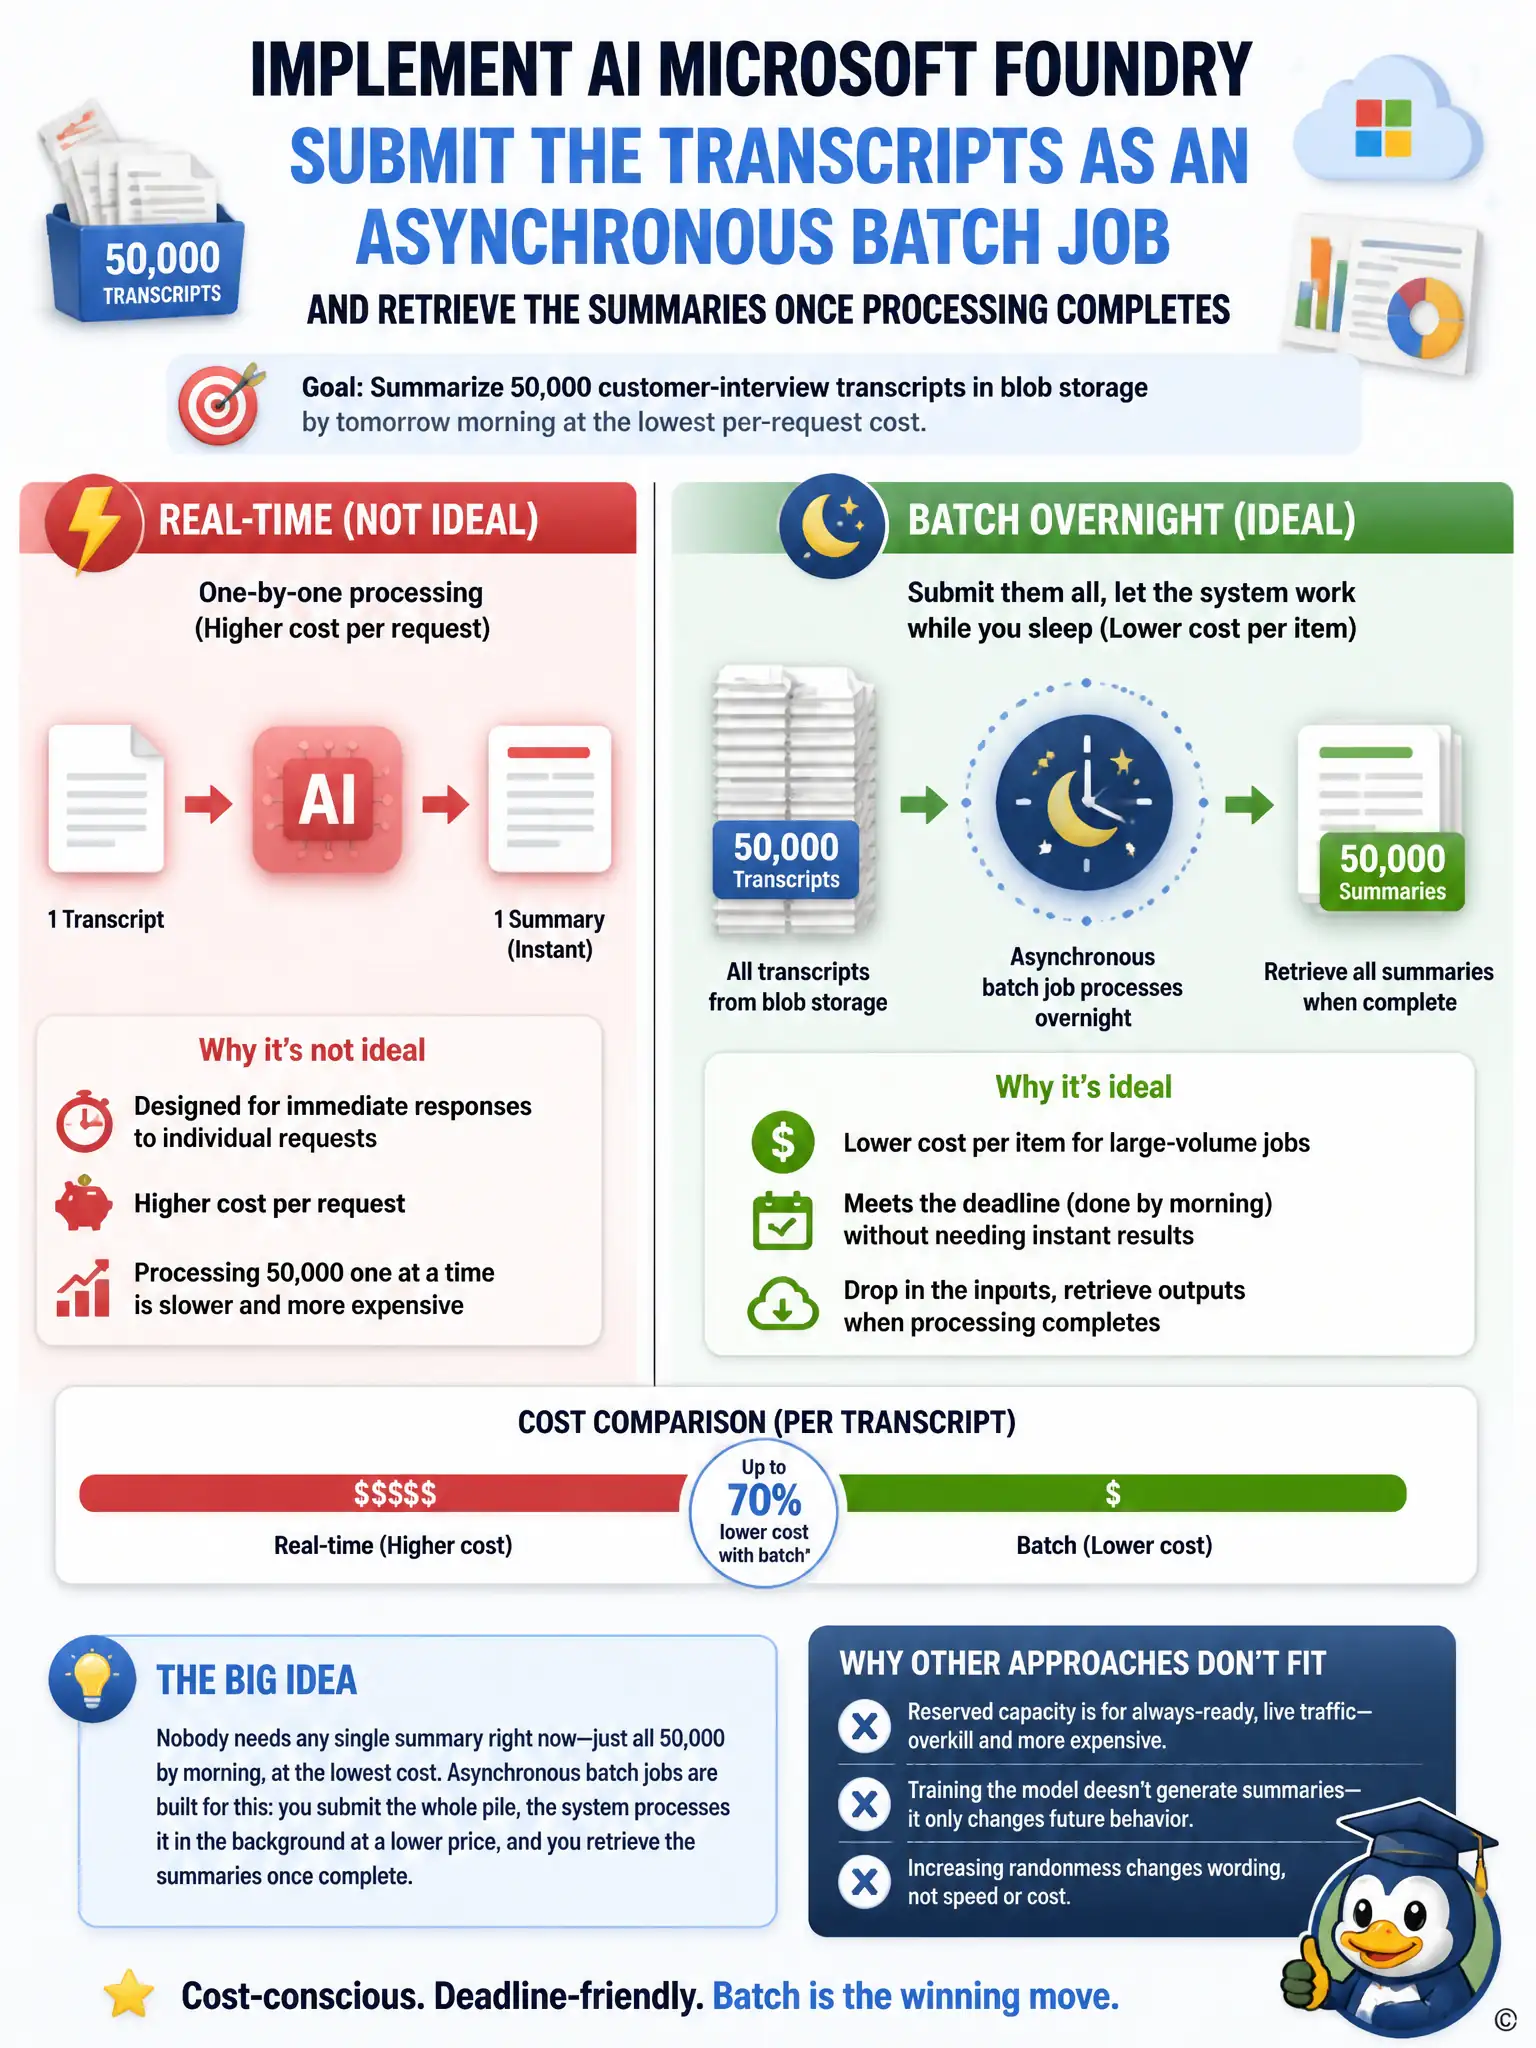
You need all 50,000 summaries by morning, not any one of them right now, and you want the lowest per-request cost. Submit them as an asynchronous batch job so Foundry can process them when capacity allows at a discounted price. Reserved real-time capacity, fine-tuning, or higher temperature won't solve this.
Full Explanation
The correct approach is to submit the transcripts as an asynchronous batch job and retrieve the summaries once processing completes. Foundry's batch processing option lets you submit a large set of independent requests as an asynchronous job that runs when capacity allows, and it is priced at a discount specifically because none of the individual results are needed immediately, which matches a firm that only needs all 50,000 summaries by tomorrow morning and cares about minimizing per-request cost. The approach that deploys the model with provisioned throughput and sends every transcript in the same real-time request session is incorrect because provisioned throughput is designed for steady, latency-sensitive real-time traffic, and its reserved-capacity pricing is meant to guarantee low-latency responses, not to discount one-off bulk jobs, so it would cost more than necessary for work with no immediate deadline. The approach that fine-tunes the model on the transcripts first is incorrect because fine-tuning changes how a model responds to future prompts by training on examples; it does not produce summaries of the training data itself, so the transcripts would still need to be summarized afterward through separate requests. The approach that increases the model's temperature setting is incorrect because temperature controls the randomness and creativity of generated text, not the speed of generation or the cost per request, so adjusting it would have no effect on either the report deadline or the firm's cost goal.