
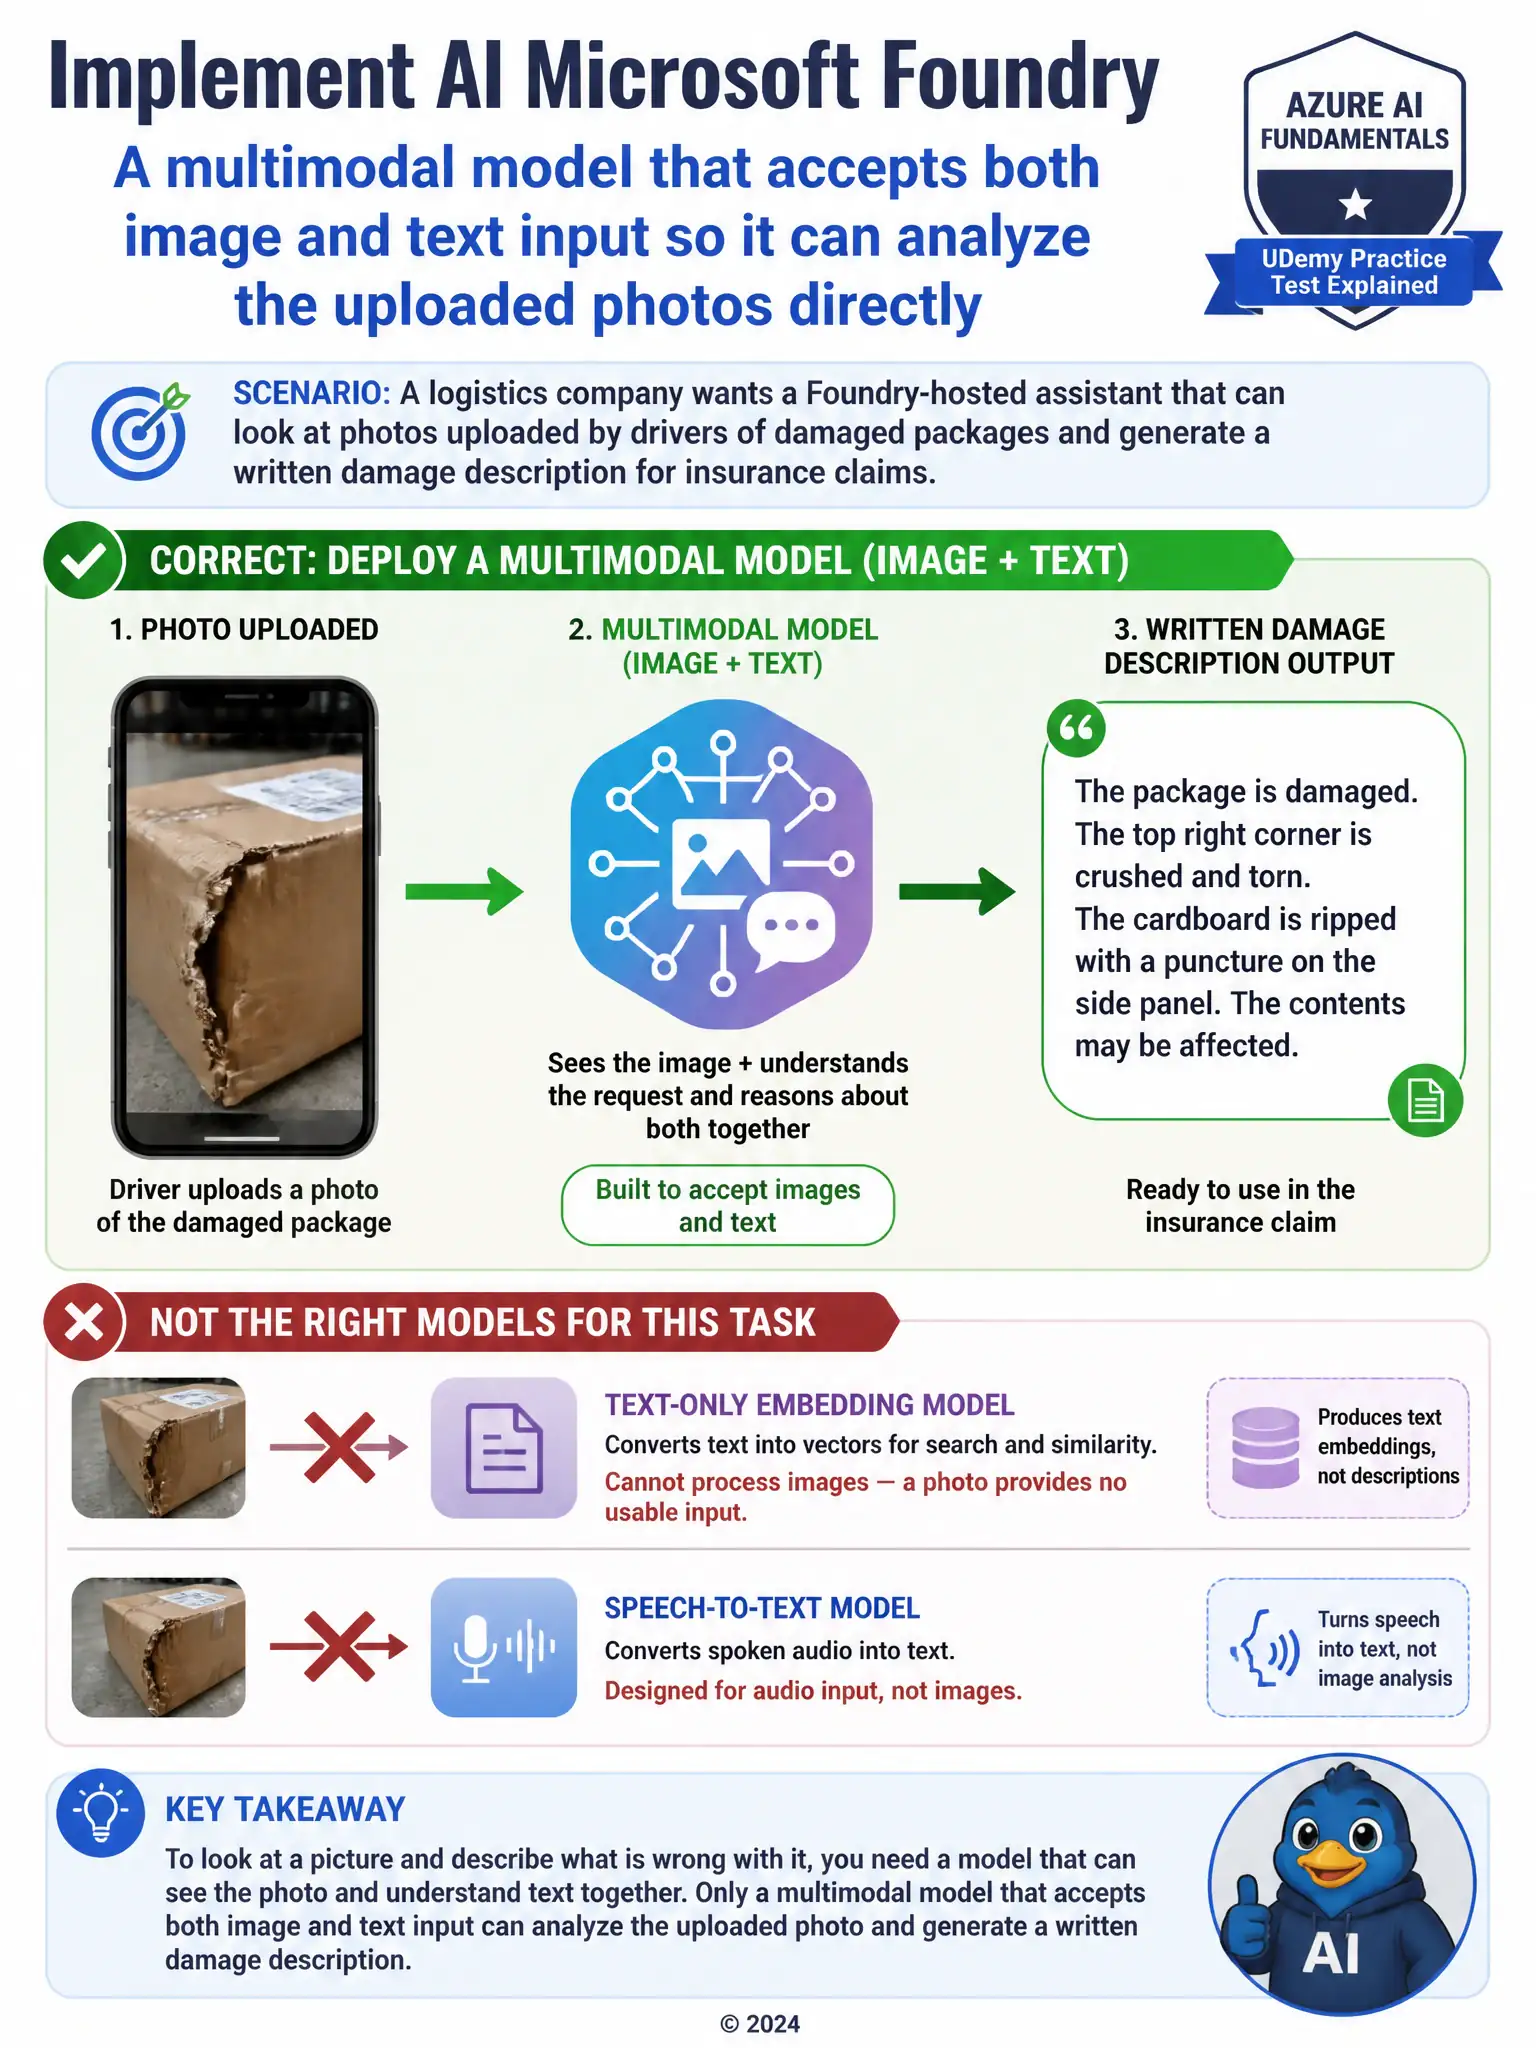
A logistics company wants a Foundry-hosted assistant that can look at photos uploaded by drivers of damaged packages and generate a written damage description for insurance claims. Which type of model should they deploy for this capability?
Select an answer to reveal the explanation.
Short Explanation
You need a model that can actually see the photos and reason about them with text, so deploy a multimodal model that accepts image and text input. Text-only embeddings, bigger text-only chat models, and speech-to-text tools can't inspect the picture itself.
Full Explanation
Multimodal model that accepts both image and text input is correct because analyzing photos of damaged packages and producing a written description requires a model that can accept image input alongside text. A multimodal model with vision capability can interpret the visual content of the photo and generate the corresponding text description. Text-only embedding model is incorrect because it converts text into numeric vectors for tasks like search and similarity comparison; it is not designed to interpret the visual content of a raw photograph. Larger text-only chat model is incorrect because it still has no way to perceive an image's content just because it is bigger — model scale does not substitute for the ability to process visual input, and a file name carries no information about what the photo shows. Speech-to-text model is incorrect because it transcribes spoken audio into text; it addresses a completely different input modality and would not process an uploaded photograph at all.