
A research firm wants a Foundry-hosted assistant to answer questions about individual 300-page technical reports. Each report is far larger than the deployed model's context window, and sending the full document in one prompt causes errors. What approach lets the assistant answer questions grounded in a specific report without exceeding the model's input limit?
Select an answer to reveal the explanation.
Short Explanation
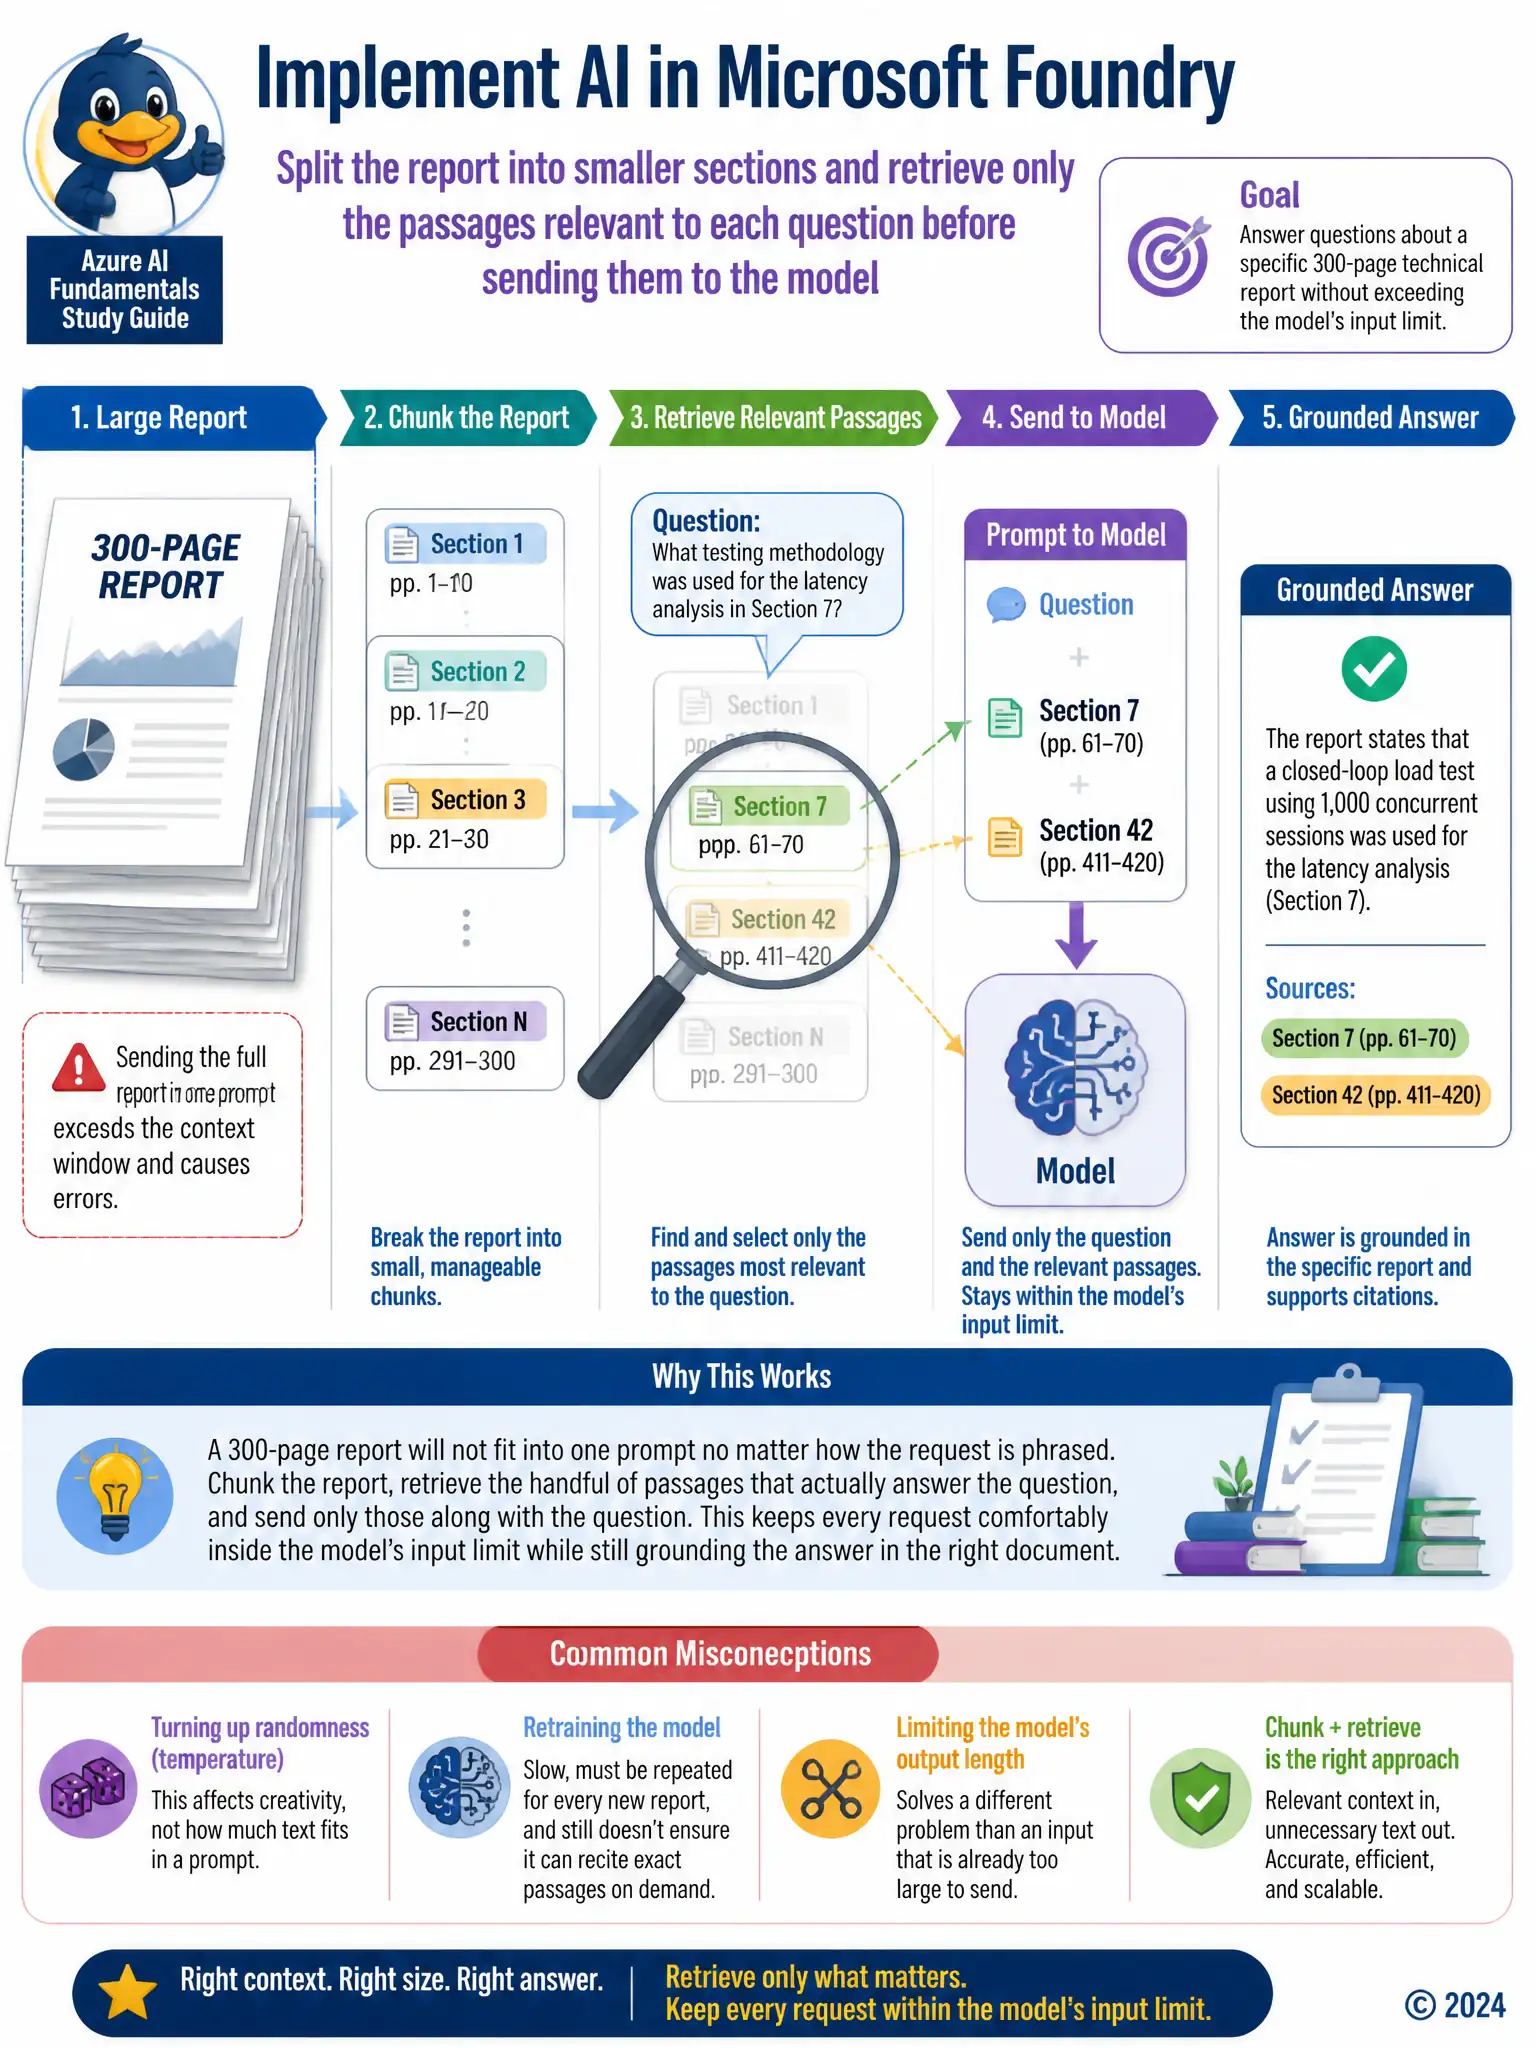
You can't shove a 300-page report into one prompt, so don't try. Split it into chunks, pull only the passages that answer the question, and send those with the question. That keeps you inside the input limit and still grounds the answer in the right report.
Full Explanation
The correct approach is splitting each report into smaller sections and retrieving only the passages relevant to a given question. That keeps the amount of text sent to the model within its context window while still grounding the answer in the correct report, which is the retrieval-augmented pattern built for exactly this constraint. Increasing the temperature setting is incorrect because temperature controls how varied or deterministic the wording of a response is; it has no effect on how much input text the model can accept. Fine-tuning the model on the full text of every report in advance is incorrect because it is a heavy, slow process aimed at shaping general behavior or style, not a reliable way to guarantee the model recalls and cites the exact contents of a specific 300-page document on demand, and it would need to be redone whenever reports change. Reducing the number of output tokens requested from the model is incorrect because it addresses how much the model writes back, not the separate problem of the input document exceeding the model's context window in the first place.