
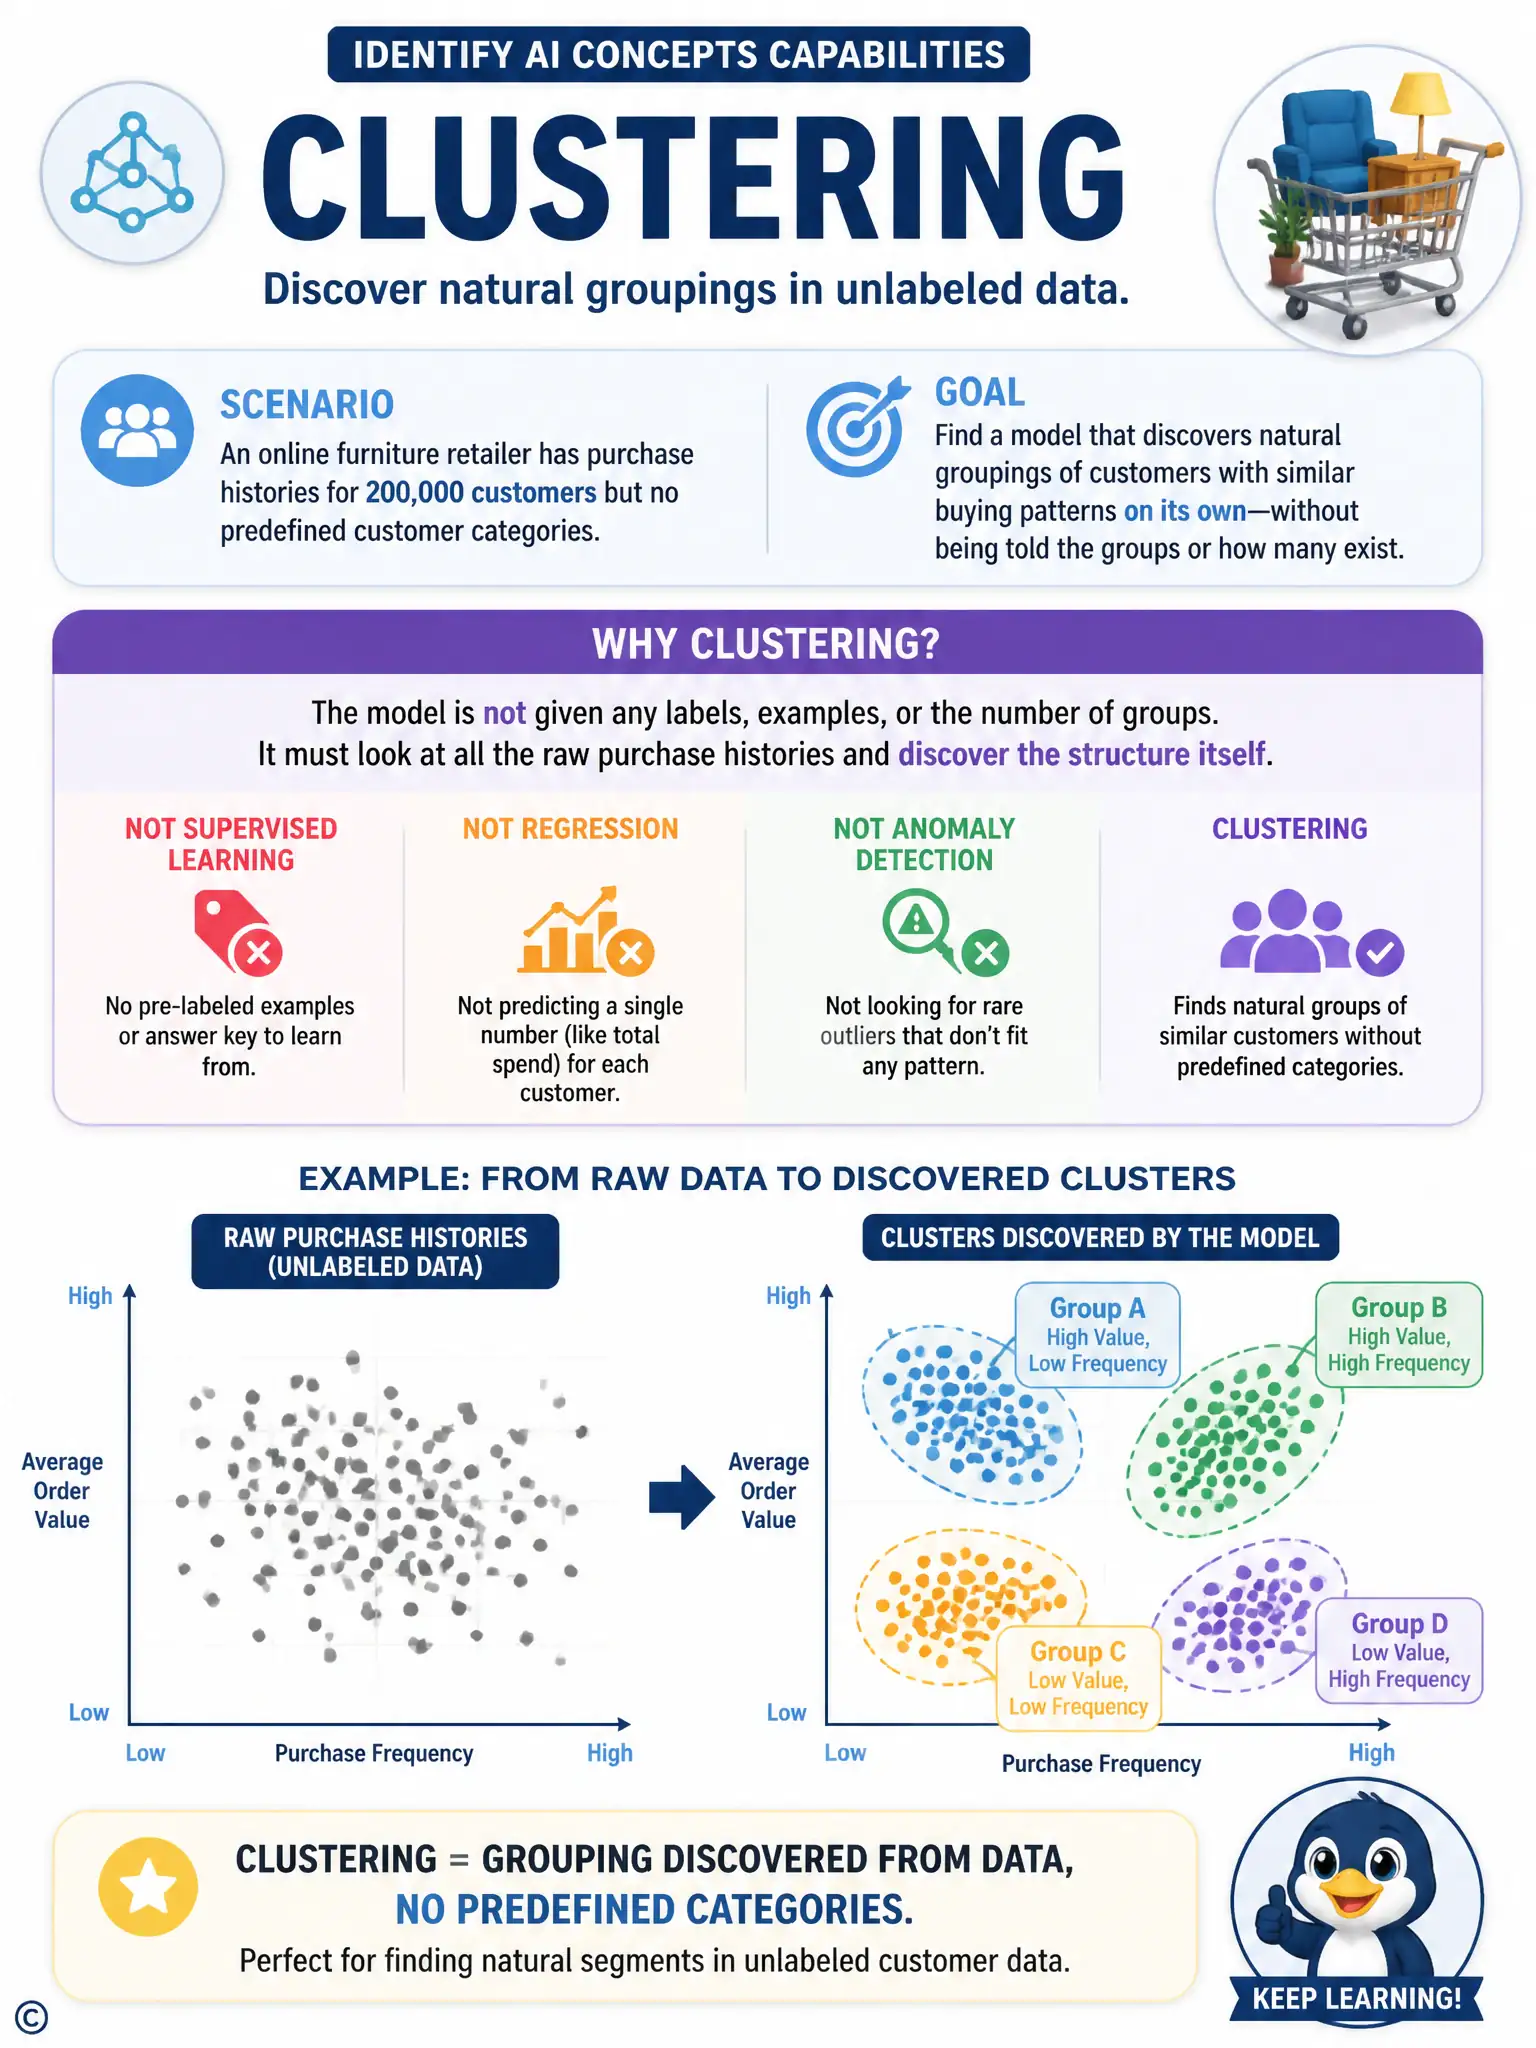
An online furniture retailer has purchase histories for 200,000 customers but no predefined customer categories. A data science team wants a model to discover natural groupings of customers with similar buying patterns on its own, without being told in advance what the groups should be or how many exist. Which type of machine learning task fits this goal?
Select an answer to reveal the explanation.
Short Explanation
You've got raw purchase histories with no predefined categories or count of groups, so the model has to find structure on its own. That rules out anything needing pre-labeled examples, since there's no answer key for the model to study. Clustering is what sorts similar buying patterns into natural customer segments.
Full Explanation
Clustering is the task that fits here. It's an unsupervised technique that groups data points by similarity without relying on predefined labels or a fixed number of categories, which matches the team's goal of letting the model discover customer segments on its own. The classification option is wrong because classification is a supervised technique that requires training data already labeled with the correct category for each example, but the scenario explicitly states there are no predefined categories to learn from. The regression option is wrong because regression predicts a single continuous numeric value, such as expected spend, rather than organizing the entire customer base into groups of similar behavior. The anomaly detection option is wrong because anomaly detection is built to flag rare or unusual data points that deviate from normal patterns, not to organize the full population of customers into cohesive segments. Because the retailer wants the model to find structure in unlabeled purchase data and produce groupings that were not specified beforehand, clustering is the task that matches both the unsupervised nature of the problem and the goal of discovering segments rather than predicting a number or spotting outliers.