
An operations team is scoping four candidate AI features for next quarter's roadmap and must sort each one by workload type to budget for the right specialists. (Select TWO.) The candidates are: extracting invoice line items from scanned image files using optical character recognition, translating shipping manifests from English into Spanish, counting vehicles in traffic camera footage using object detection, and condensing lengthy supplier contracts into short paragraphs. Which two candidates are computer vision workloads?
Select all correct answers, then click Submit.
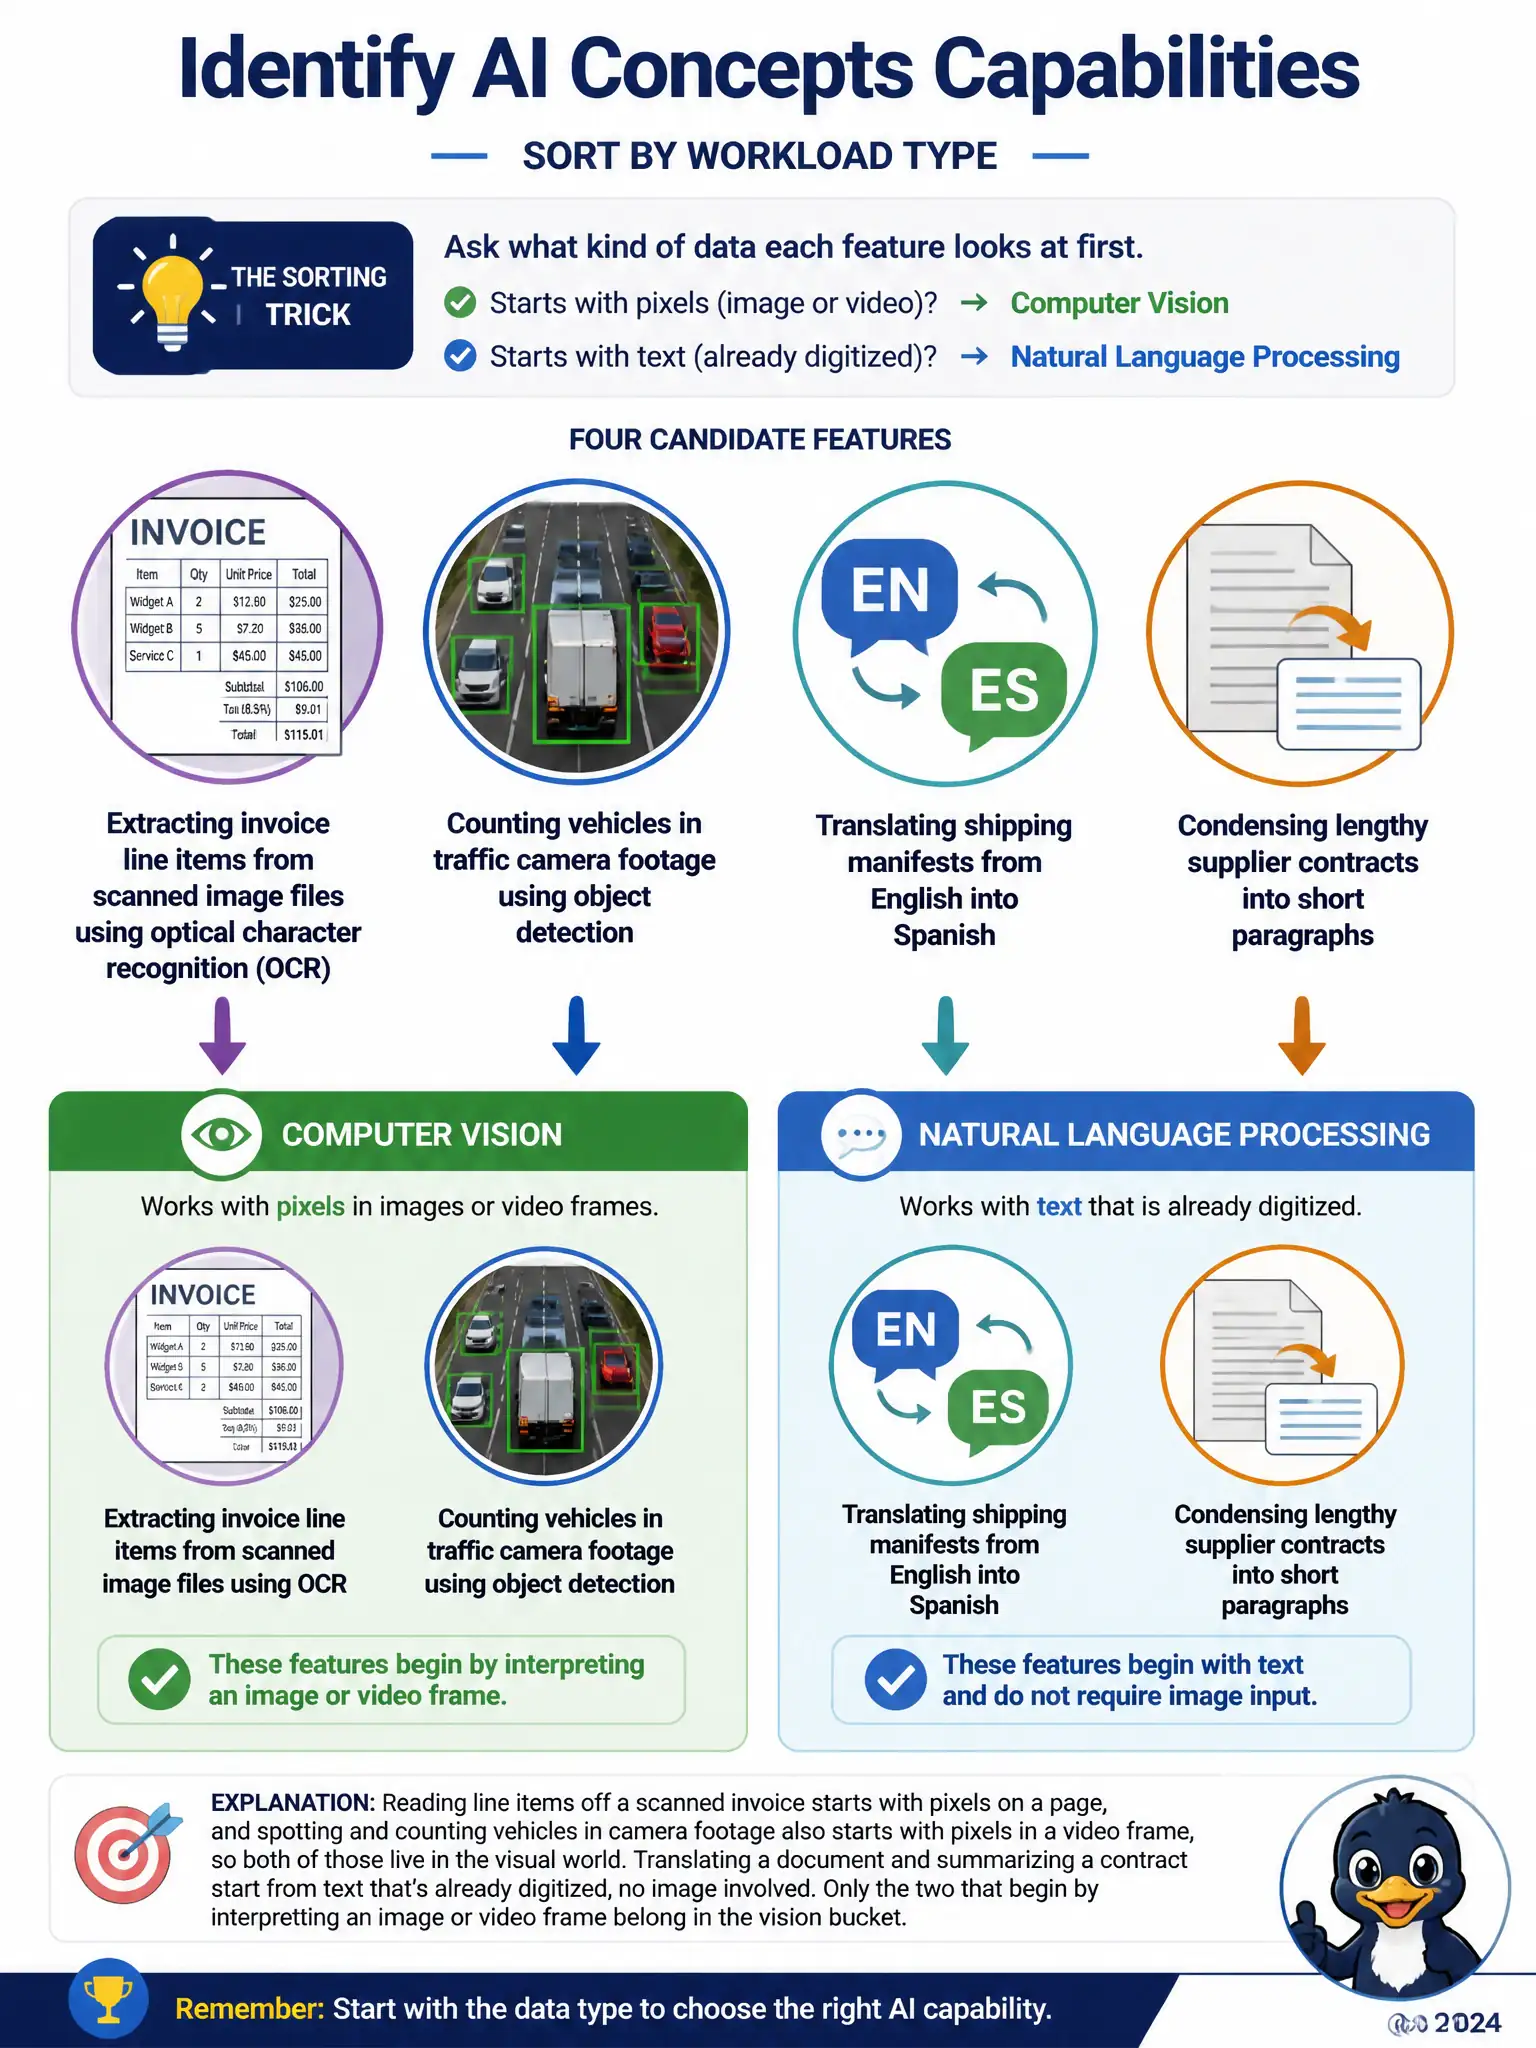
Short Explanation
You can sort these by asking what kind of data each feature actually looks at first. If it starts with pixels from a scanned page or camera frame, you put it in computer vision, so invoice extraction and vehicle counting belong there. If it starts with already-digitized text, it's language work, not vision.
Full Explanation
The correct answers are extracting invoice line items from scanned image files using optical character recognition and counting vehicles in traffic camera footage using object detection. Extracting invoice line items from scanned images relies on optical character recognition to read visual text from an image, and counting vehicles in traffic footage relies on object detection to locate and count discrete objects in visual frames; both operate on image data and both are core computer vision workloads. Translating shipping manifests from English into Spanish is incorrect because translating text between languages is a natural language processing workload, not a computer vision one, since it operates on already-digitized text rather than interpreting pixels in an image. Condensing lengthy supplier contracts into short paragraphs is incorrect for the same reason: condensing lengthy contracts into short paragraphs is text summarization, another natural language processing capability, and involves no image analysis at all. The distinguishing question for sorting any of these four candidates is whether the input the system analyzes is visual, an image or video frame, or purely textual; the two vision-based candidates both start from pixels, while the two language-based candidates both start from text.