
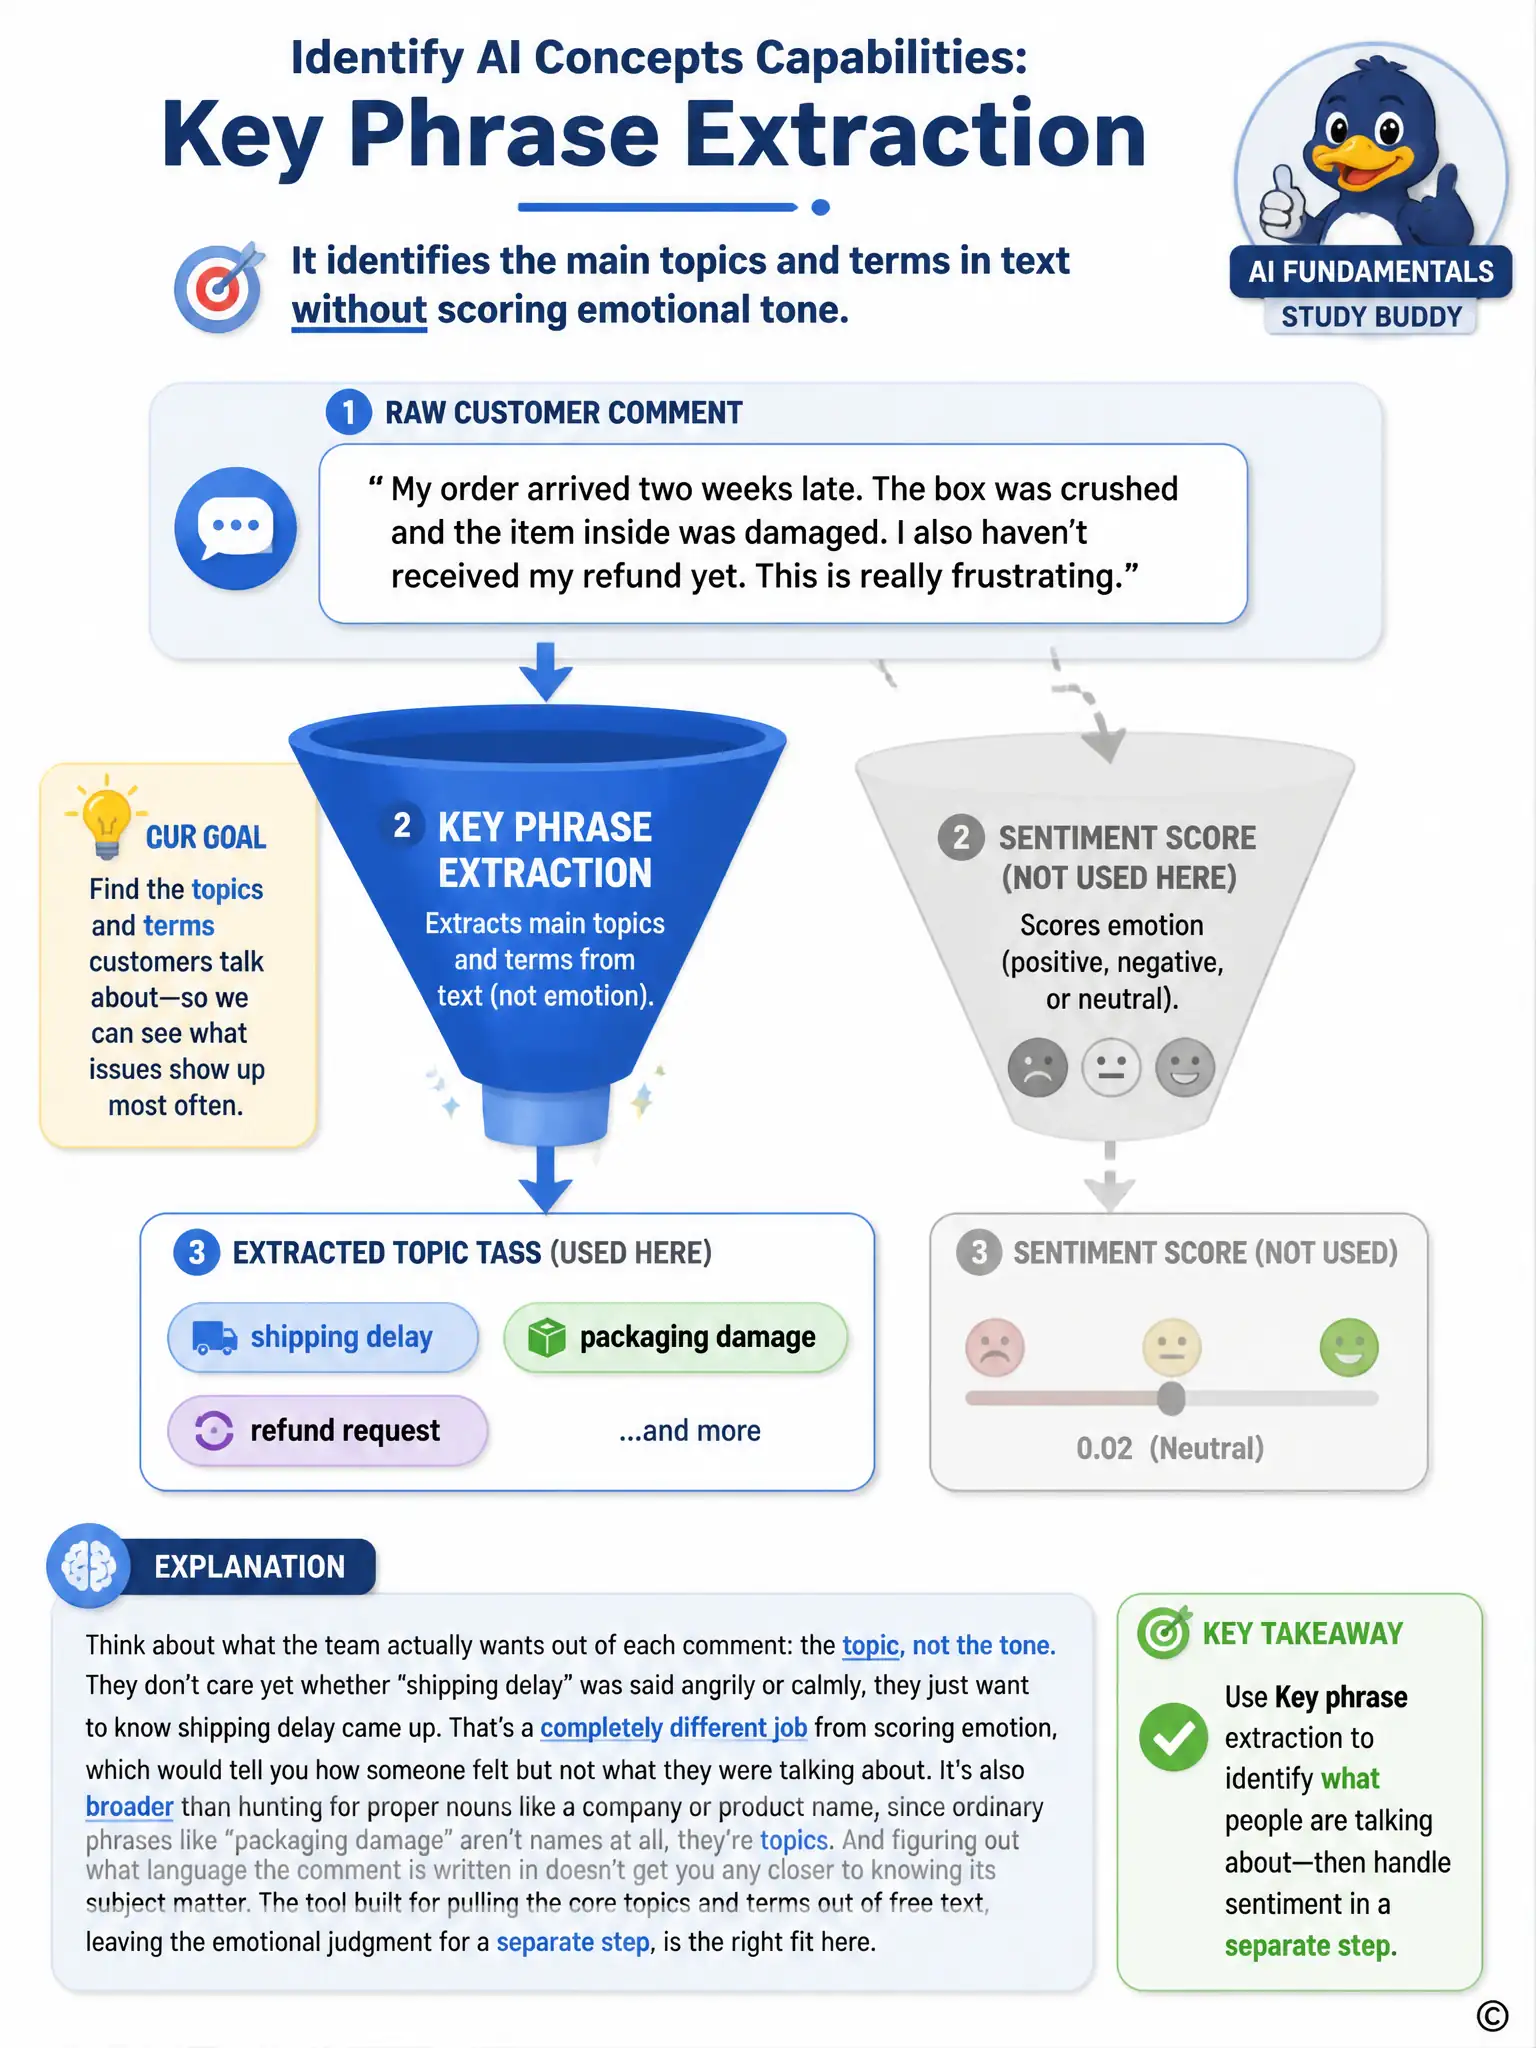
A customer support team receives thousands of open-ended feedback comments each week and wants software that automatically pulls out the main topics and terms mentioned in each comment, such as 'shipping delay' or 'packaging damage', without judging whether the comment expresses a positive or negative opinion. Which natural language processing capability should the team use?
Select an answer to reveal the explanation.
Short Explanation
You need the topics, not the tone. Key phrase extraction pulls out phrases like 'shipping delay' or 'packaging damage' without deciding if the customer was happy or angry. That's the tool for surfacing main terms in thousands of comments.
Full Explanation
The correct capability is key phrase extraction. The team wants the main subjects of each comment surfaced, such as 'shipping delay,' with no judgment about whether that topic was described positively or negatively, which is exactly what key phrase extraction does: it pulls out the salient terms and topics from a block of text. Sentiment analysis is incorrect because it produces a positive, negative, neutral, or mixed score for the emotional tone of text, which is the one output the team explicitly said it does not need. Language detection is incorrect because it identifies which language a piece of text is written in, a preprocessing step unrelated to surfacing topics within comments already assumed to be readable. Named entity recognition is incorrect because it tags specific proper nouns like people, organizations, or locations, which is narrower than general topic terms; 'shipping delay' and 'packaging damage' are ordinary phrases, not named entities, so this capability would miss most of what the team needs. Key phrase extraction is the workload built specifically for topic surfacing at scale.