
A retail company wants to add a product-recognition feature to an in-store kiosk that has limited processing power and a requirement that results appear within a fraction of a second, even when the kiosk's internet connection is unreliable. A larger, more accurate cloud-hosted vision model is available in Azure AI Foundry's model catalog but requires a network round trip and noticeably more processing time. Which factor should most influence the team's choice of model?
Select an answer to reveal the explanation.
Short Explanation
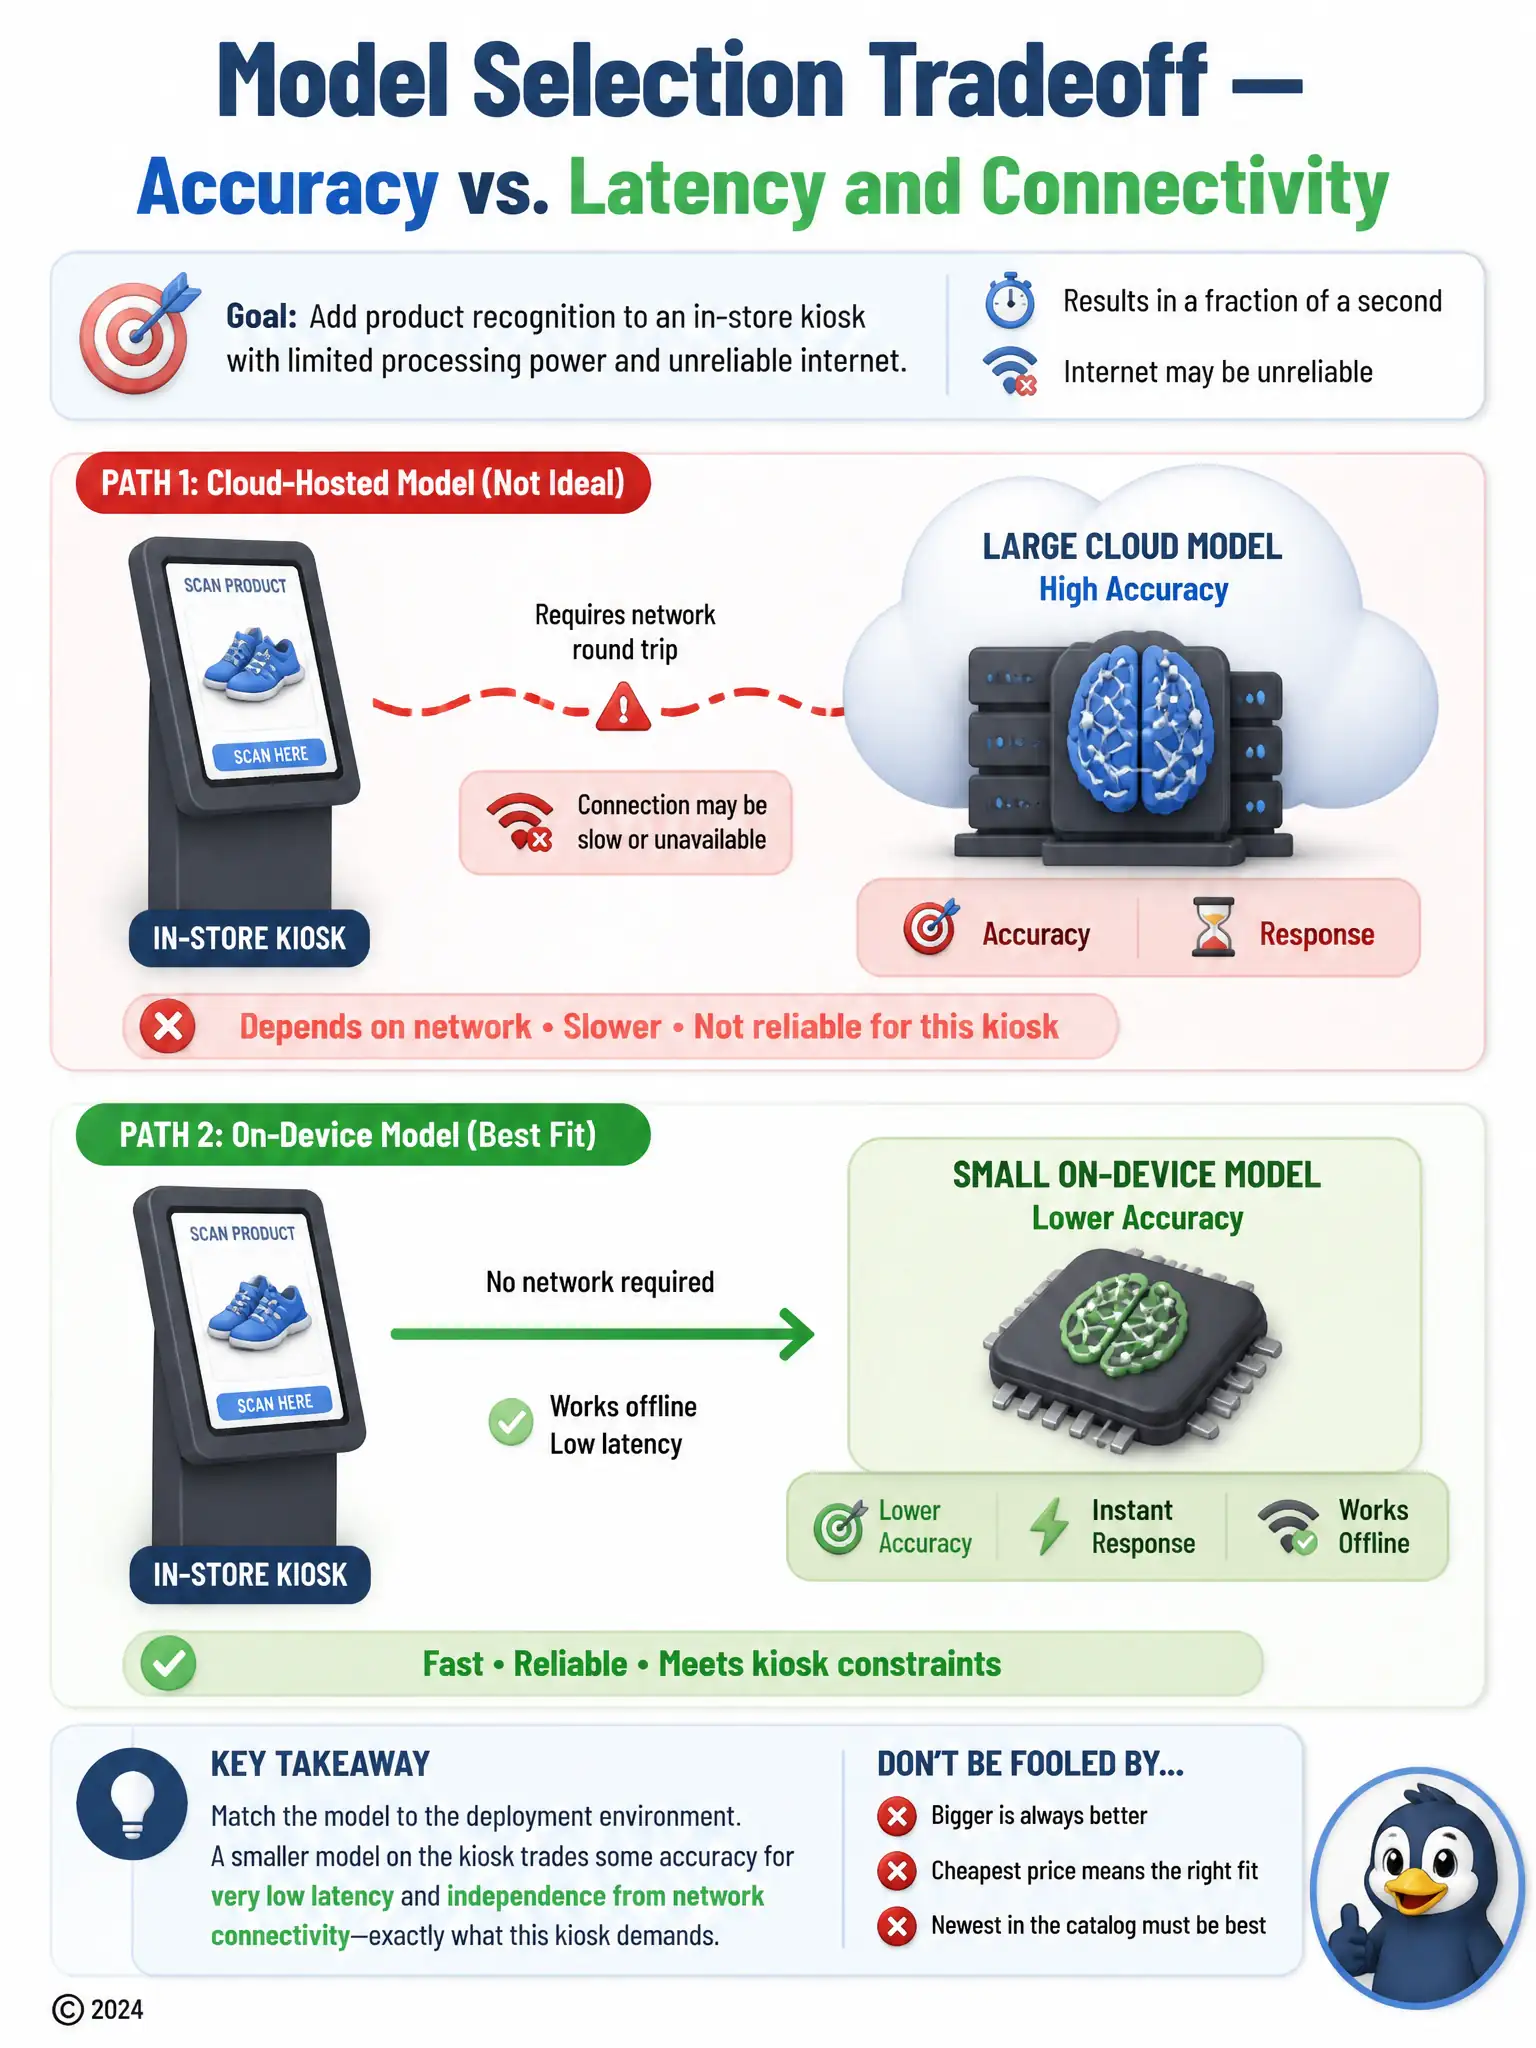
You need a model that fits the kiosk's real limits: weak hardware, near-instant results, and flaky internet. A smaller local model gives up some accuracy, but it stays fast and keeps working when the network drops. Chasing the biggest, cheapest, or newest model ignores what this deployment actually needs.
Full Explanation
The right choice is the smaller model that can run locally on the kiosk, trading some accuracy for low latency and independence from network connectivity. Given the kiosk's constraints, a limited processing budget, a sub-second latency requirement, and an unreliable internet connection, a smaller model that runs locally on the device is the right choice even though it sacrifices some accuracy compared to the larger cloud-hosted option, because it can meet the response-time requirement and keep working when the network drops. The choice of the largest available cloud-hosted model is incorrect because treating model size as the only relevant factor ignores the deployment constraints described in the scenario; the larger cloud model's extra accuracy is not useful if it cannot deliver results within the required time or when the connection fails. The choice of the model with the lowest listed price per API call, regardless of where the model runs or how quickly it responds, is incorrect because focusing solely on the lowest price per call ignores whether the model can even be deployed within the kiosk's hardware and connectivity limits; a cheap model that cannot run locally or respond fast enough does not solve the stated problem. The choice of the model most recently added to the catalog, because newer models always outperform older ones on every workload, is incorrect because newer models are not automatically better for every scenario; a recently added model could still be large, cloud-dependent, or otherwise poorly suited to a low-power, latency-sensitive, intermittently connected device. Selecting a model appropriate to this workload requires weighing accuracy against latency, footprint, and connectivity, not defaulting to size, price, or recency alone.