
A software company deploys a generative AI chatbot to answer customer questions about its own product line. To reduce the chance that the chatbot invents a feature or a return-policy detail that does not actually exist, the engineering team configures it to first retrieve relevant passages from the company's current product manuals and support articles, then instructs the model to base its answer only on those retrieved passages. What is this technique called?
Select an answer to reveal the explanation.
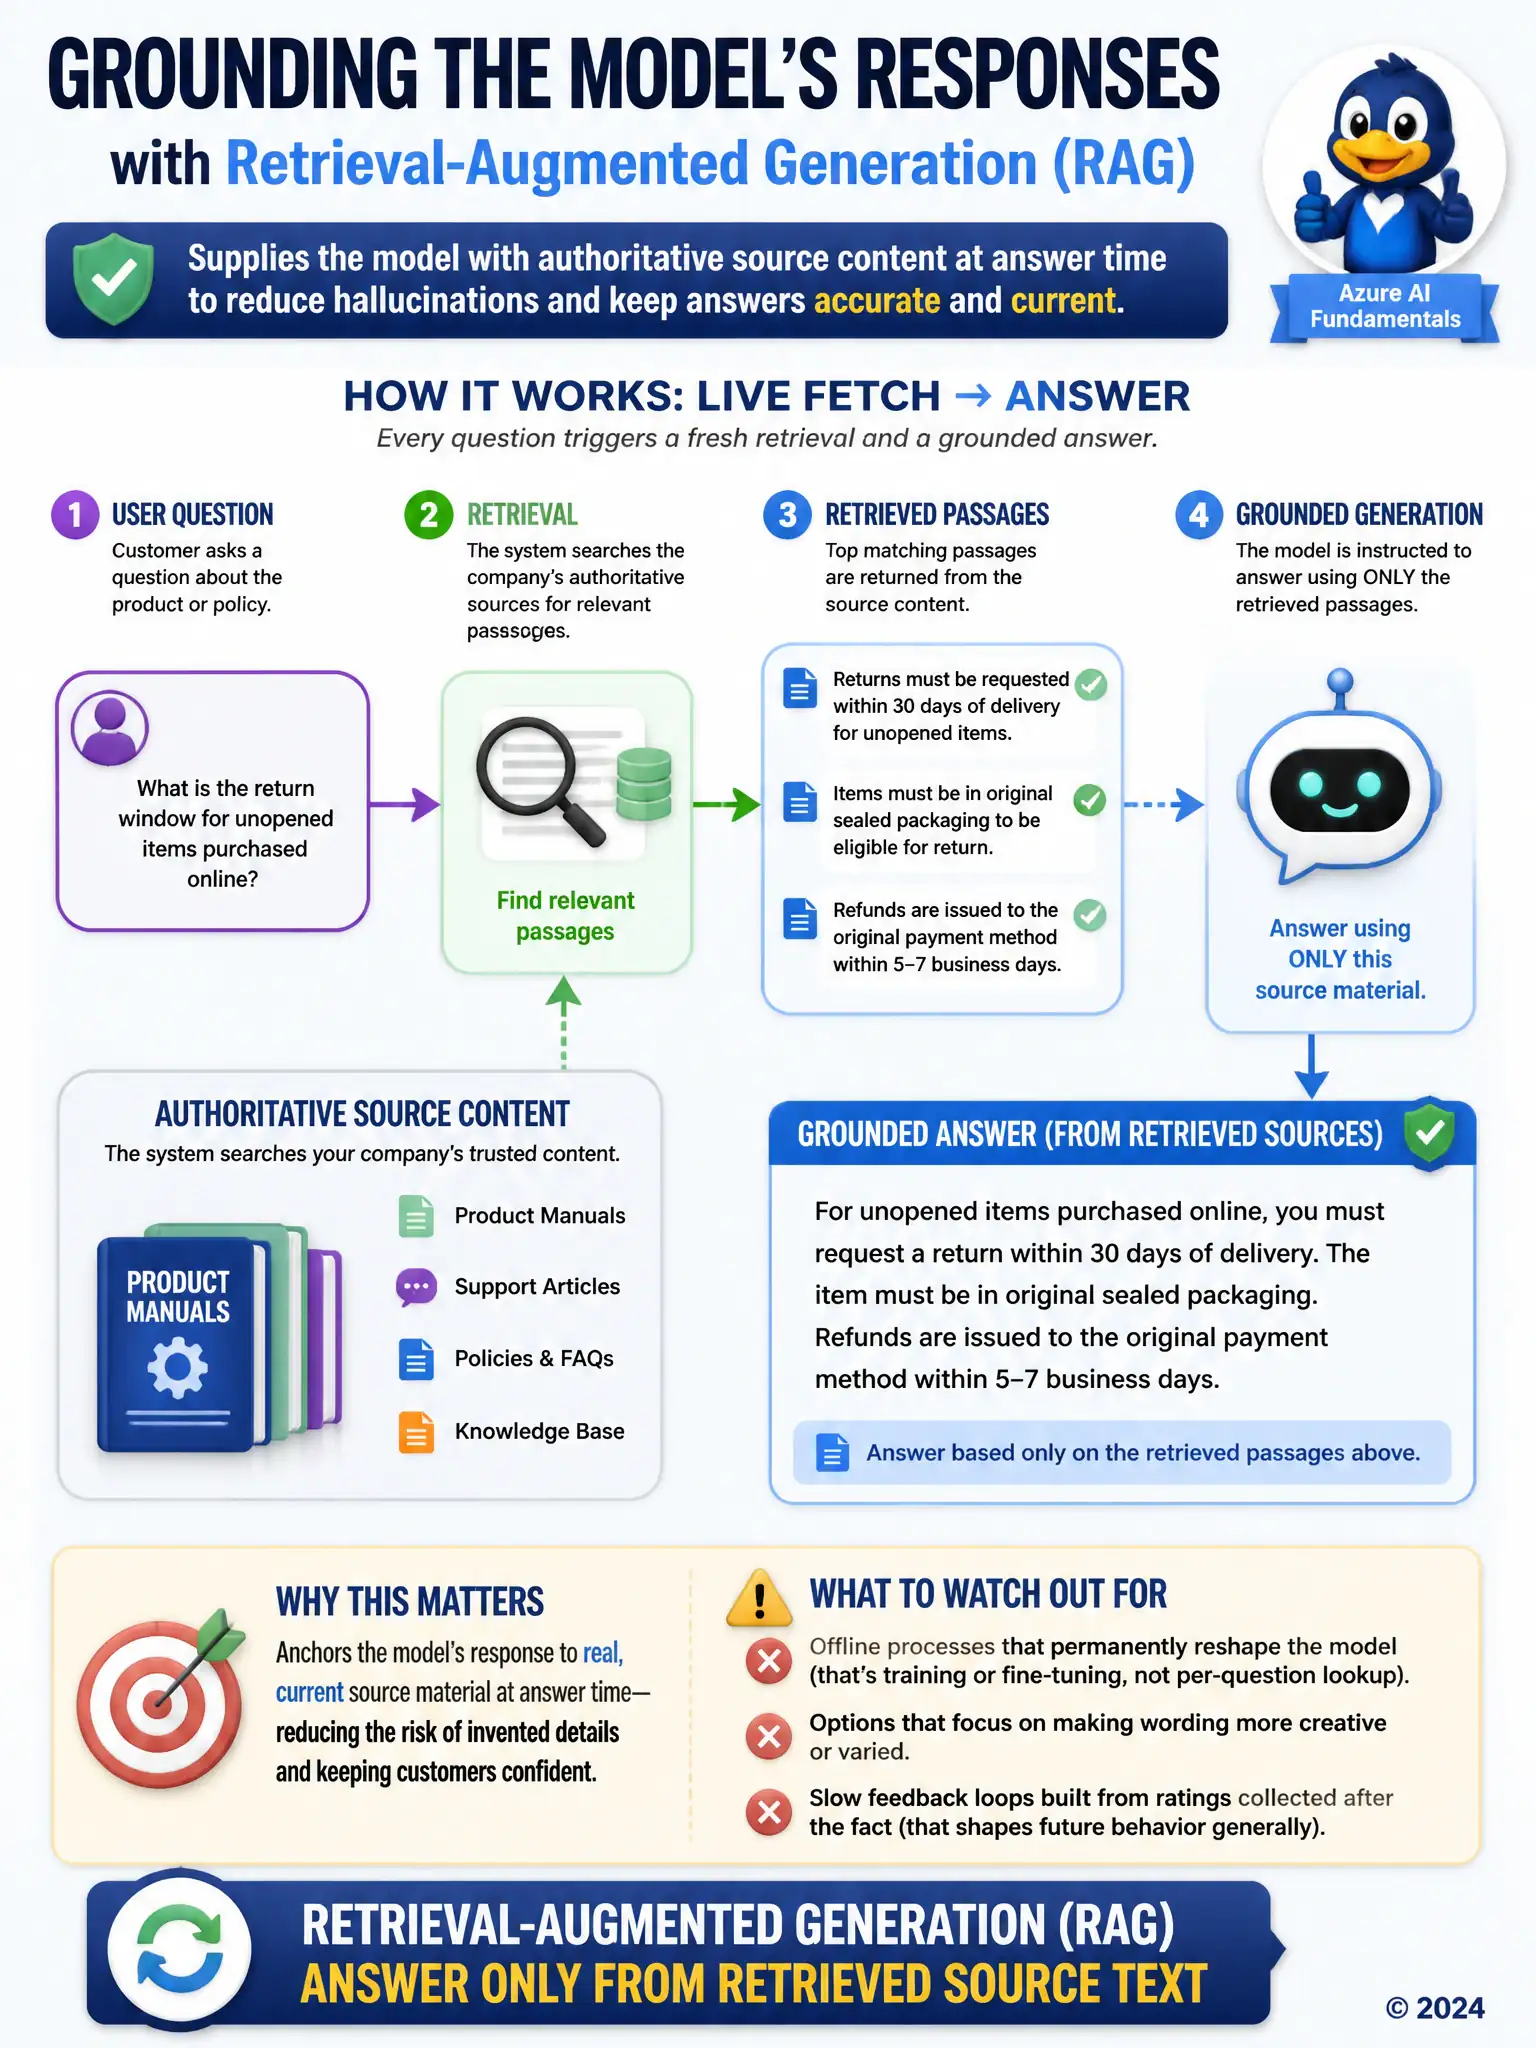
Short Explanation
You're looking for the live fetch-then-answer pattern: the system pulls current manual and support-article passages before each answer, then tells the model to use only that material. That grounds the response in real source text and helps stop it from inventing a feature or return-policy detail. Avoid answers that describe offline weight changes, more creative wording, or post-answer rating loops.
Full Explanation
The correct answer is grounding the model's responses with retrieval-augmented generation, which supplies the model with authoritative source content at answer time. Retrieving relevant passages from the company's own manuals and support articles at the moment a question is asked, then instructing the model to answer using only that retrieved content, is grounding through retrieval-augmented generation, and it directly addresses the invented-detail problem because the model's answer is anchored to real, current source text rather than relying solely on what it learned during training. The fine-tuning approach is incorrect because it permanently adjusts the model's internal weights ahead of time using a training process, which is a different, more expensive approach than retrieving fresh passages at answer time, and the scenario describes retrieval happening live for each question, not weight updates. The increased-temperature approach is incorrect because temperature controls how varied or random the model's word choices are, and increasing it would make invented details more likely, not less, which is the opposite of what the team is trying to achieve. The reinforcement-learning-from-human-feedback approach is incorrect because it is a training-time technique that adjusts model behavior using human ratings collected over time, not a mechanism for supplying source content at the moment a specific question is answered. Watch out for answers describing something that happens once, ahead of time, by permanently reshaping the model itself, since that's a heavier, offline process, not a per-question lookup. Also be wary of anything that talks about making the model's wording more varied or creative, since that pulls in the opposite direction, and anything describing a slow feedback loop built from ratings collected after the fact, since that shapes future behavior generally rather than grounding one specific answer in one specific source right now. The scenario's live retrieve-then-answer pattern is the defining signature of grounding.