
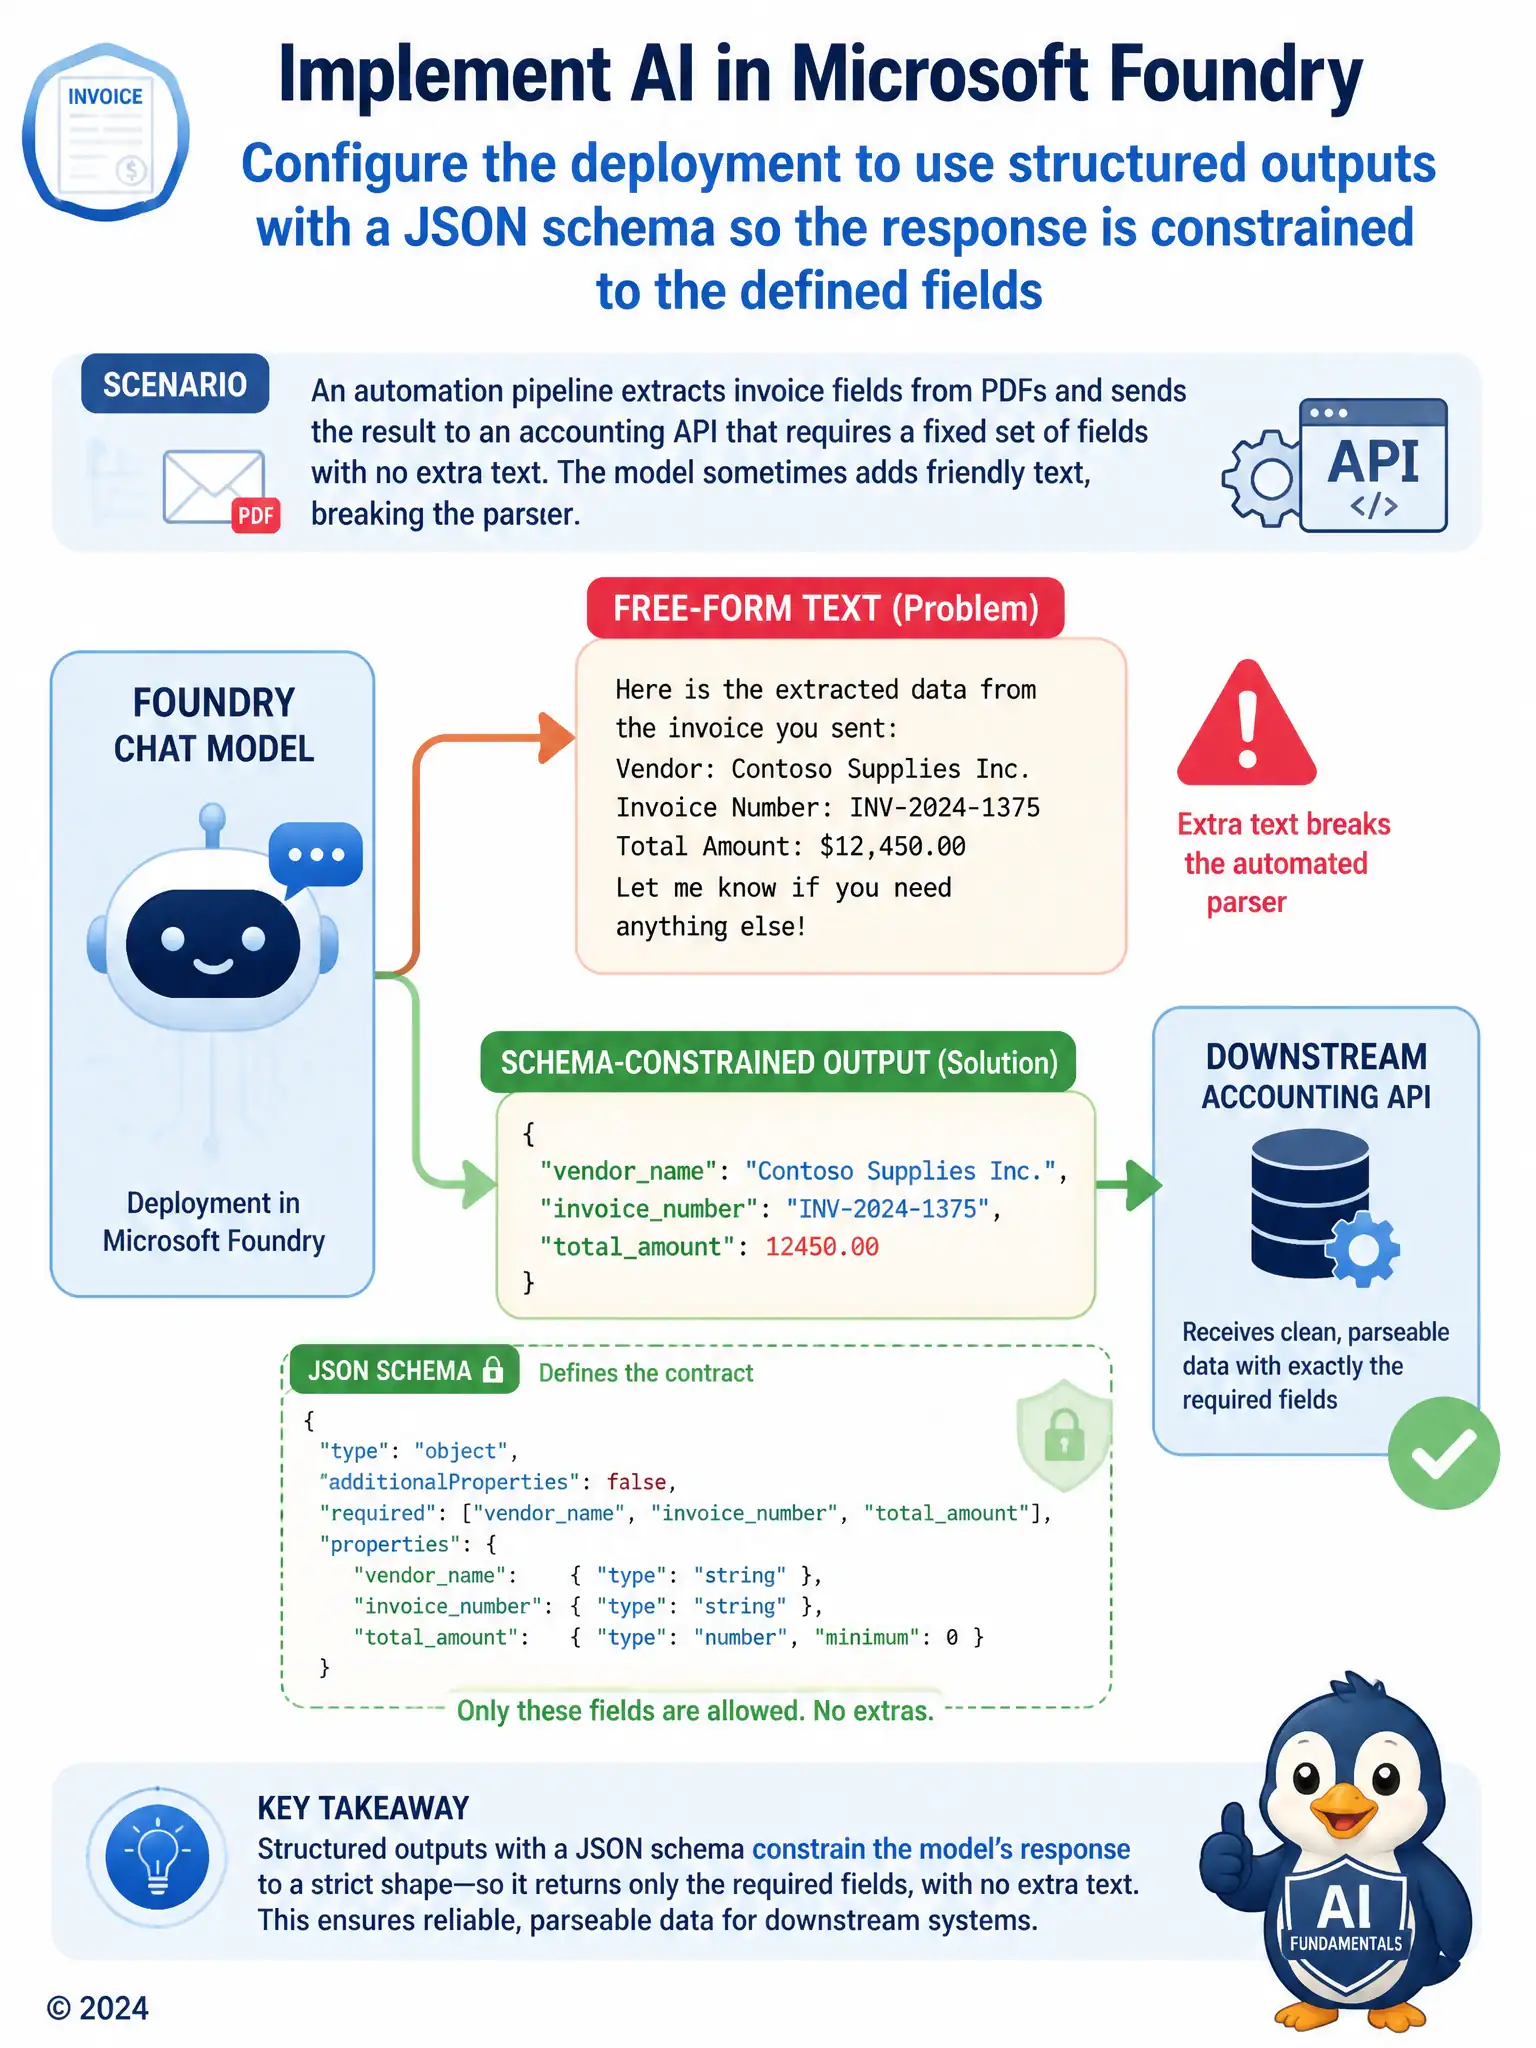
A software company's internal automation pipeline calls a Foundry-hosted chat model to extract invoice fields (vendor name, invoice number, total amount) from emailed PDFs and passes the result straight into an accounting API that requires a fixed set of named fields with no extra text. In several test runs the model wrapped its answer in a sentence like 'Here is the extracted data:' before the values, which broke the automated parser. Which approach should the team use so the model reliably returns only the required fields in a parseable form?
Select an answer to reveal the explanation.
Short Explanation
You've got a downstream parser, so don't rely on the model being polite. Configure structured outputs with a JSON schema so the model can only return the named invoice fields. That's how you make the response parseable every time.
Full Explanation
The right approach is to configure the deployment to use structured outputs with a JSON schema so the response is constrained to the defined fields. Structured outputs let the team supply a JSON schema that names the exact fields the accounting API expects; Foundry constrains the model's generation to that schema, so every response is machine-parseable with no stray sentences to strip. The approach that asks the model in the prompt to format its answer nicely and strips extra sentences with post-processing code is wrong because prompt wording is only a suggestion the model can ignore, and building post-processing code to catch every possible phrasing is fragile and will keep breaking as the model varies its wording. The approach that fine-tunes a new model version on thousands of manually labeled invoices before deploying it is wrong because fine-tuning on invoice examples might teach the model the domain vocabulary, but it does not guarantee a fixed output structure; the model can still add conversational framing unless the response format itself is constrained. The approach that lowers the model's temperature setting to reduce the randomness of its wording is wrong because temperature controls how varied or creative the wording is, not whether the model wraps its answer in extra text; a low-temperature response can still include an introductory sentence. Structured outputs address the actual problem directly: enforcing a schema at generation time rather than hoping for compliant phrasing or cleaning up the output afterward.