
A team wants a Foundry-hosted chatbot to answer questions grounded in the company's internal product manuals rather than the model's general training data. To set this up as a retrieval-augmented generation solution in Azure AI Foundry, which two components must they configure? (Select TWO.)
Select all correct answers, then click Submit.
Short Explanation
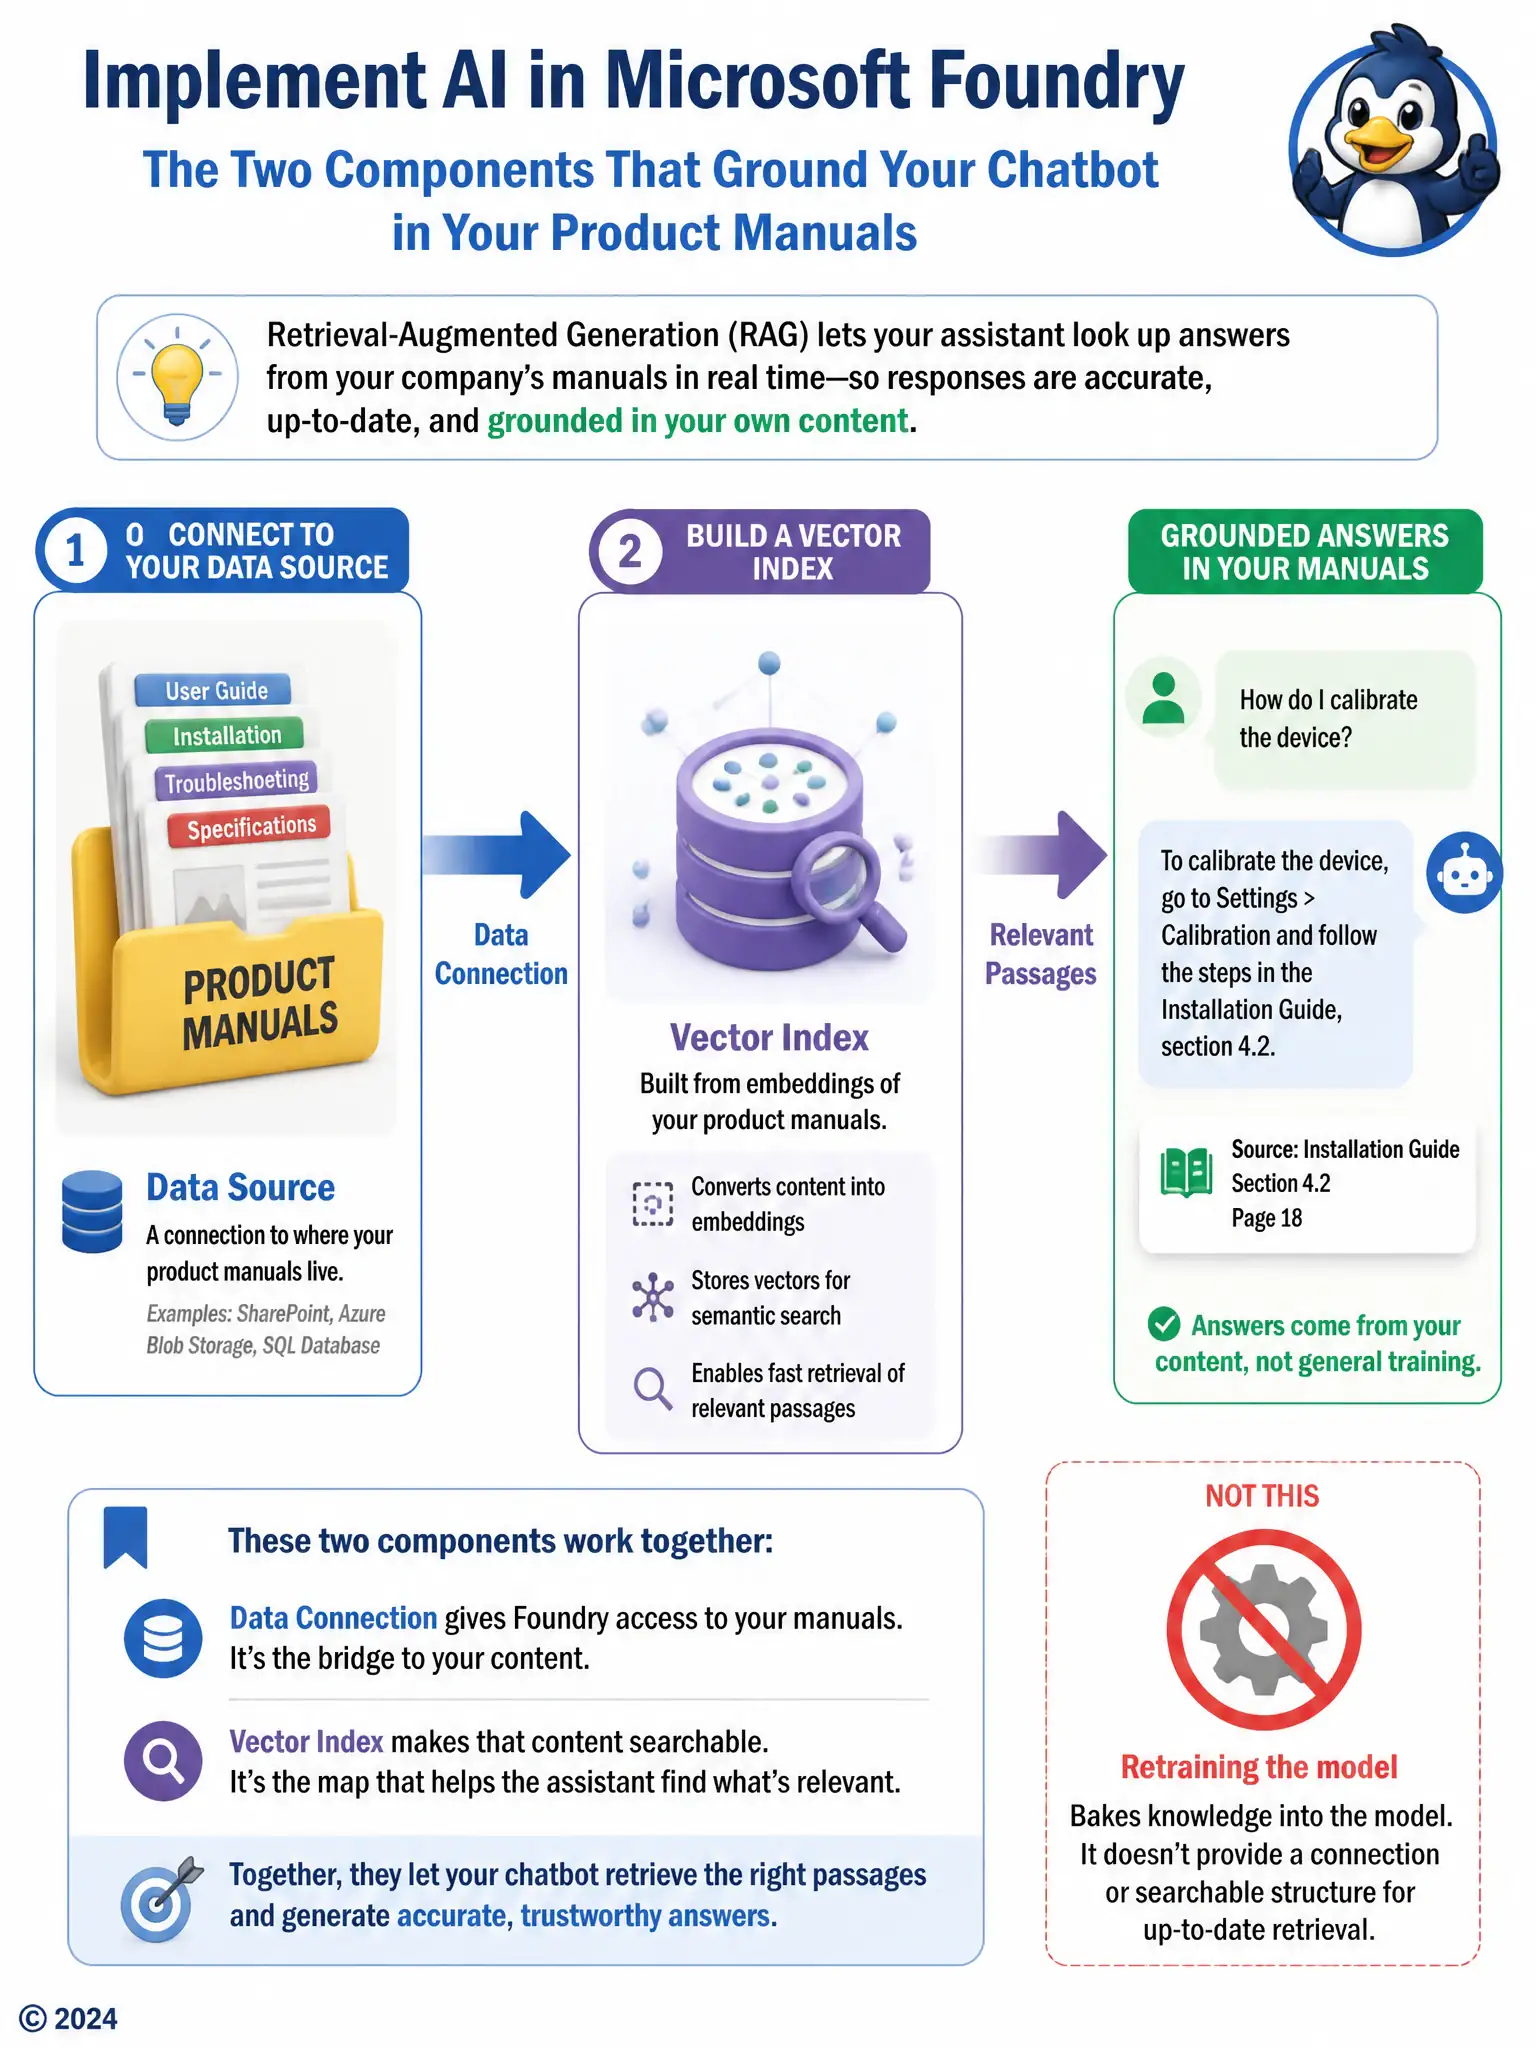
You need a connection to a data source containing the product manuals and a vector index built from embeddings of them. That gives the chatbot something to pull from and a way to find the right passages fast. Fine-tuning or blocking technical terms won't ground it in the manuals.
Full Explanation
A retrieval-augmented generation setup needs a connection to a data source containing the product manuals so Foundry can access them, and a vector index built from embeddings of that content so the assistant can retrieve the most relevant passages at query time and ground its answers in them; both pieces are required for grounding to work at all. A fine-tuning job that retrains the base model on the manuals is incorrect because fine-tuning retrains the model's weights on a training set, which is a separate customization technique from retrieval and does not, by itself, connect the assistant to the current manuals or let it cite them at query time. A content safety filter set to block all technical vocabulary is incorrect because a content safety filter screens generated or input content for policy violations such as hate speech or violence; blocking technical vocabulary would actually prevent the assistant from discussing the manuals at all and has nothing to do with grounding answers in company data.