
A retail marketing team wants to produce a batch of custom product lifestyle images from short text descriptions, such as 'a red backpack on a hiking trail at sunset', to use in social media ads, without hiring a photographer for each concept.
Select an answer to reveal the explanation.
Short Explanation
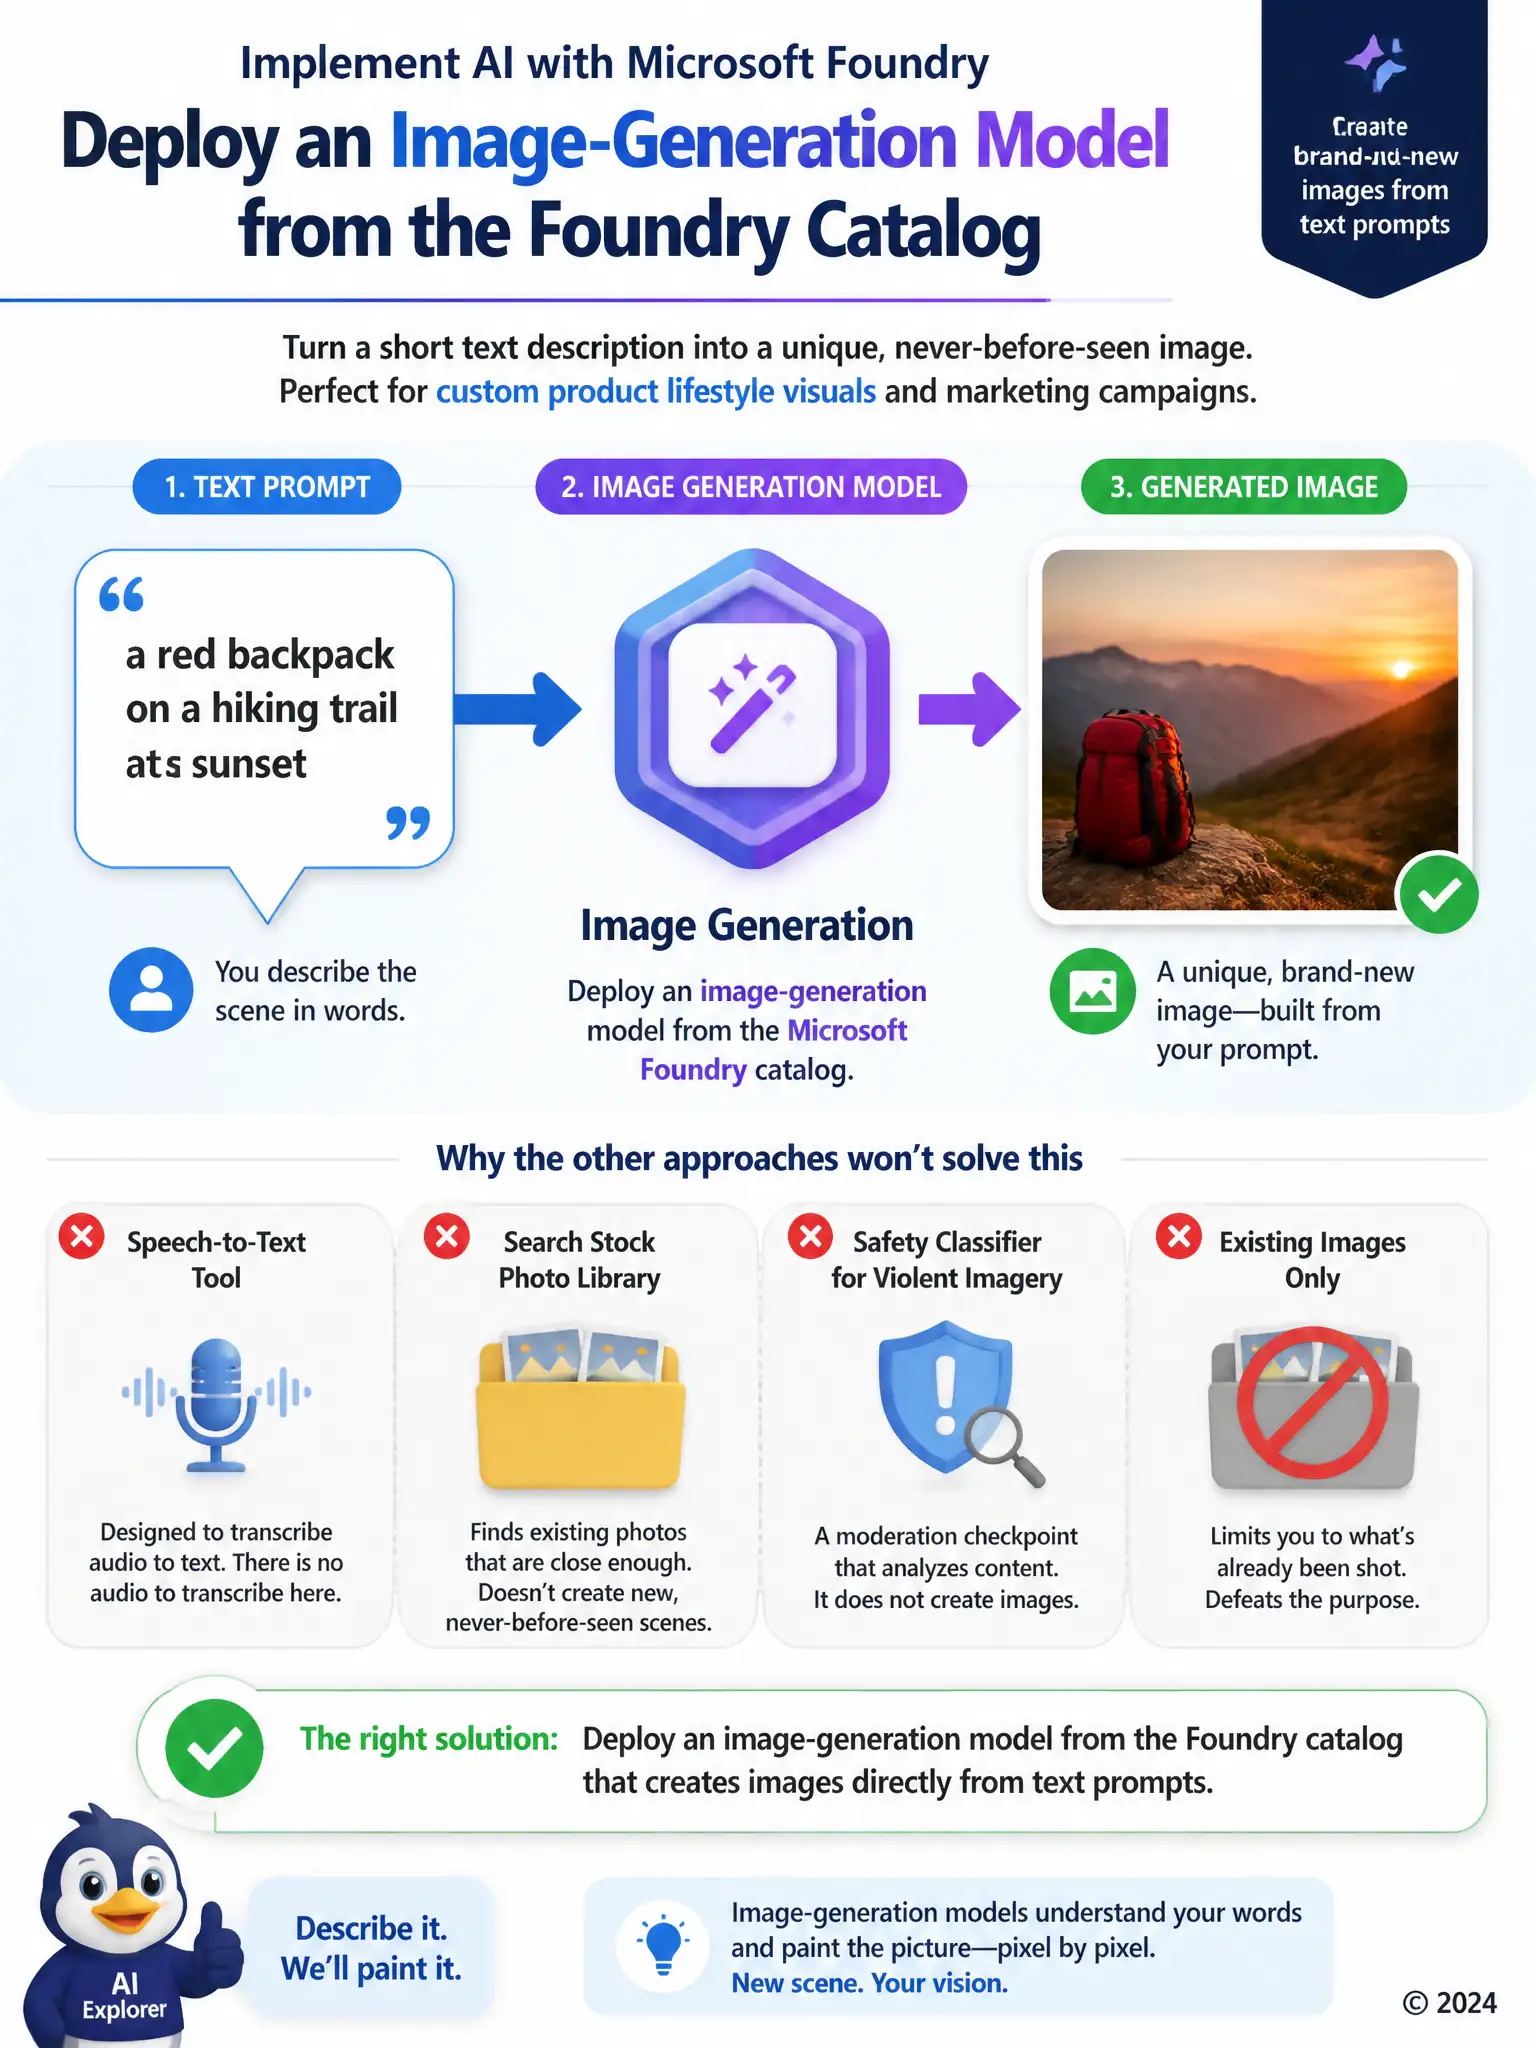
You need a brand-new image built from a sentence, so deploy an image-generation model from the Foundry catalog. It takes text prompts and creates the custom lifestyle visuals directly, without hunting for existing photos or transcribing notes.
Full Explanation
The correct choice is the image-generation model from the Foundry catalog. It takes a text description as input and produces a new image matching that description, which is exactly the capability this marketing team needs to turn short prompts into custom lifestyle visuals without commissioning original photography. The speech-to-text model is incorrect because it converts spoken audio into written text; it has no role here since the team is starting from written descriptions and needs an image as output, not a transcript. The text embedding model paired with a search over an existing photo database is incorrect because it can only retrieve images that already exist, which does not satisfy the team's need for entirely new, custom scenes built from novel prompts. The content safety classifier tuned to detect violent imagery is incorrect because it screens content for policy violations like violence; it is a moderation tool, not a generation tool, and deploying it alone would produce no images at all.