
A legal-tech team is building a Foundry-hosted assistant that must read entire merger agreements, some running past 250 pages, and produce a single risk summary in one pass. Early tests show the assistant silently drops content from the later sections of long documents. Which change addresses the root cause?
Select an answer to reveal the explanation.
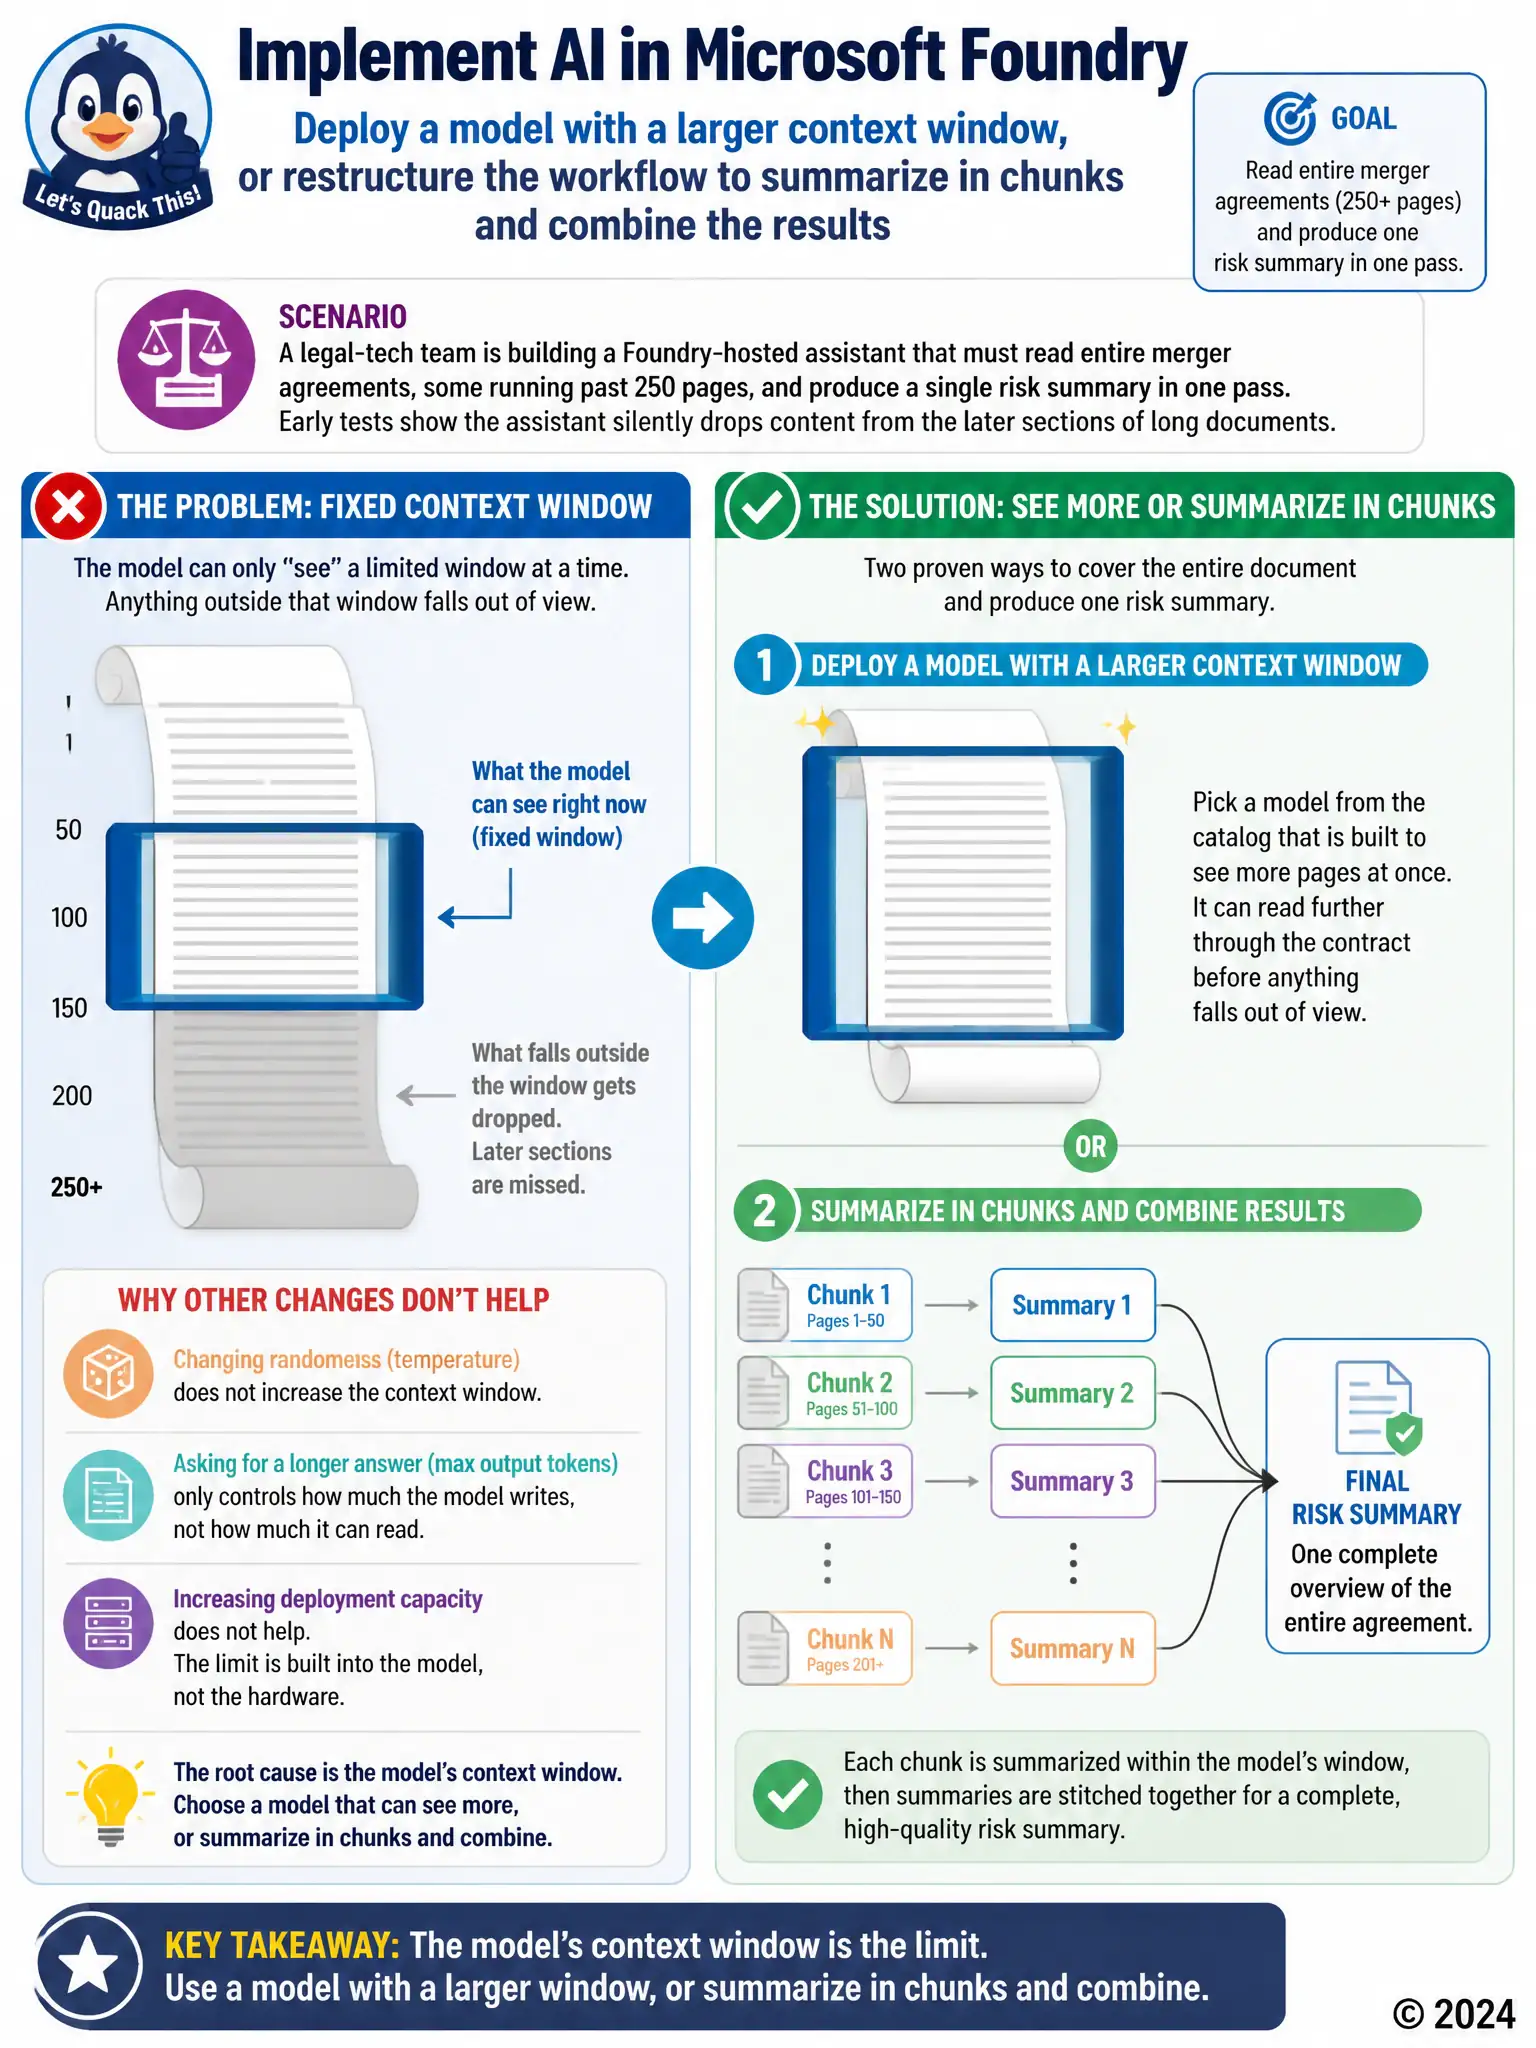
Short Explanation
Picture the model as reading through a fixed-size window. Once a 250-page merger agreement runs past that window, later sections drop out, so you need a larger context window or a chunk-and-combine workflow. Don't chase temperature, response length, or deployment type; they don't widen input capacity.
Full Explanation
The assistant is dropping content from later sections because the merger agreements exceed the model's context window, the maximum amount of text it can process in a single call. The fix must address input capacity, not output behavior: either choose a catalog model with a larger context window or restructure the workflow to chunk the document into sections, summarize each chunk, and combine the partial summaries into a final risk summary. The option that lowers temperature is incorrect because temperature controls the randomness of word choice, not how much input text the model can read. The option that increases max_tokens is incorrect because max_tokens governs the length of the generated response, and raising it does nothing to let the model see text it never received as input. The option that switches from serverless API to managed compute is incorrect because that change affects throughput and cost characteristics for high-volume traffic, but a single request to either deployment type is still bounded by the same underlying model's context window.